tencent/Qwen3-8B-DSpine-b16
- License
- apache-2.0
- Size
- not mirrored yet
No official torrent yet — requesting it tells the flock what to host next. You cannot seed a catalog-only page.
Cataloged from tencent/Qwen3-8B-DSpine-b16
All models by tencent →No official torrent yet — requesting it tells the flock what to host next. You cannot seed a catalog-only page.
Cataloged from tencent/Qwen3-8B-DSpine-b16
All models by tencent →Draft in Parallel, Condition Through Depth: Adjacent Causal Injection for Speculative Decoding
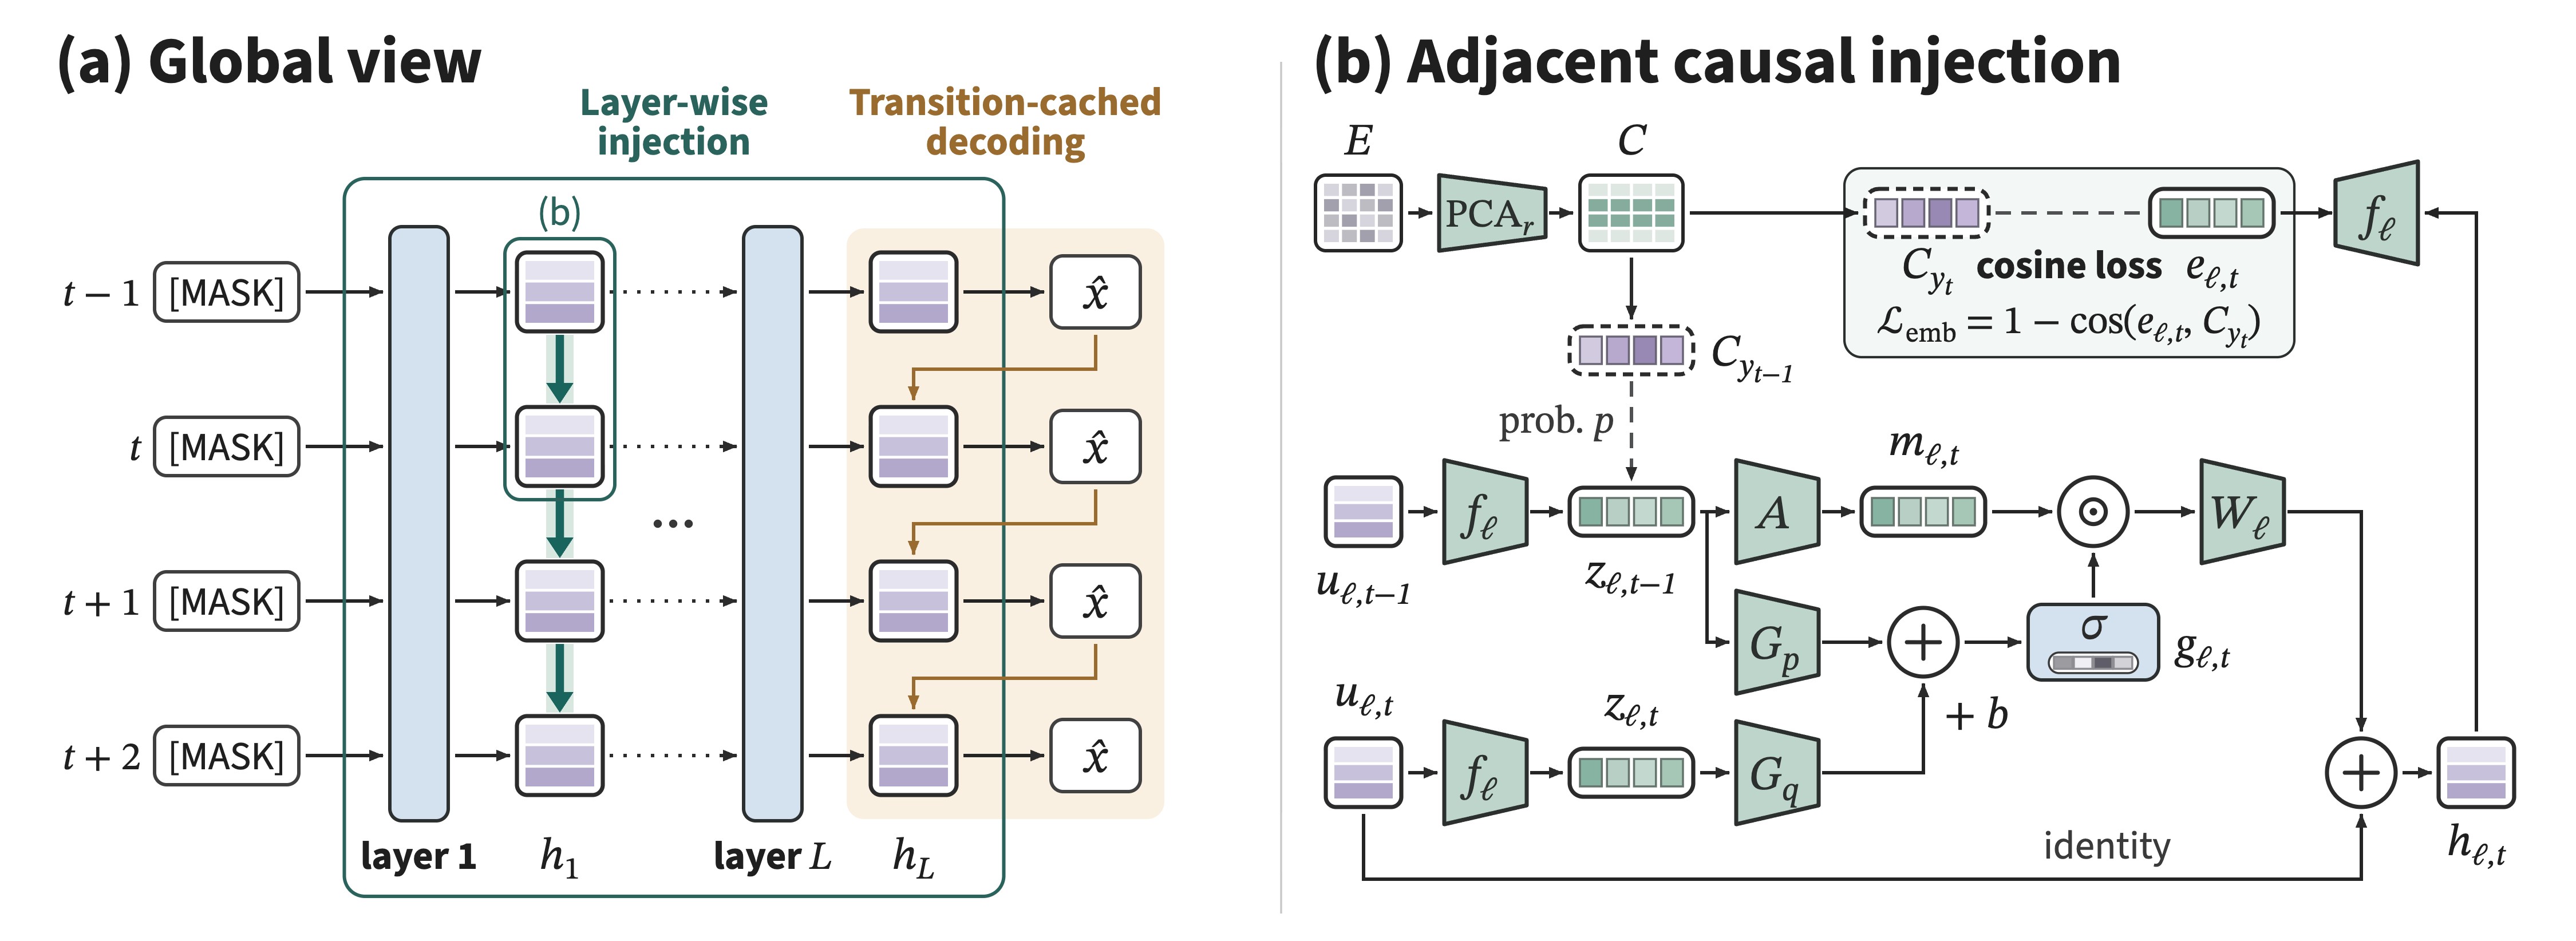
DSpine is a parallel drafter for speculative decoding. At every draft layer, each position receives the predicted feature of its predecessor, so the causal chain unfolds over network depth while all positions are still drafted in parallel.

Acceptance length on Qwen3-8B. DSpine, DSpark and DFlash2 are all retrained on Open-PerfectBlend with the same configuration.
† Official checkpoints: z-lab/Qwen3-8B-DFlash-b16 and Huang2020/Qwen3-8B-Domino-b16.
The server settings below are the ones behind the acceptance lengths and throughput reported in the paper.
☐ Training code for DSpine
☐ DSpine for Qwen3.8-27B
We thank DFlash, SpecForge, SGLang and FlashInfer for their open-source work.
git clone https://github.com/tencent/dspine.gitcd dspinepip install -e .sglang serve \ --model-path Qwen/Qwen3-8B \ --speculative-algorithm DSPINE \ --speculative-draft-model-path <dspine-model-path> \ --speculative-num-draft-tokens 16 \ --dtype bfloat16 \ --attention-backend fa3 \ --page-size 1 \ --mem-fraction-static 0.65 \ --context-length 8192 \ --max-running-requests 64 \ --cuda-graph-bs-decode 1 2 4 8 16 32 64 \ --trust-remote-code@article{zhang2026dspine, title = {Draft in Parallel, Condition Through Depth: Adjacent Causal Injection for Speculative Decoding}, author = {Zhang, Haohui and Chen, Keyu and Sun, Haocheng and Gu, Weibo and Qiao, Ruizhi and Sun, Xing and Jiang, Bo}, journal = {arXiv preprint arXiv:2609.36173}, year = {2026}}