This repository hosts the GPTQ (W4A16, GPTQModel) quantized version of MiniCPM-o 4.5. For the original BF16 weights and the full model card, please refer to openbmb/MiniCPM-o-4_5.
A Gemini 2.5 Flash Level MLLM for Vision, Speech, and Full-Duplex Mulitmodal Live Streaming on Your Phone
GitHub | CookBook | Omni-modal Demo | Vision-Language Demo
WeChat | Discord | CaseBook(Audio, Omni Full-Duplex)
News
[!NOTE]
[2026.02.06] 🥳 🥳 🥳 We open-sourced a realtime web demo deployable on your own devices like Mac or GPU. Try it now!
MiniCPM-o 4.5
MiniCPM-o 4.5 is the latest and most capable model in the MiniCPM-o series. The model is built in an end-to-end fashion based on SigLip2, Whisper-medium, CosyVoice2, and Qwen3-8B with a total of 9B parameters. It exhibits a significant performance improvement, and introduces new features for full-duplex multimodal live streaming. Notable features of MiniCPM-o 4.5 include:
-
🔥 Leading Visual Capability.
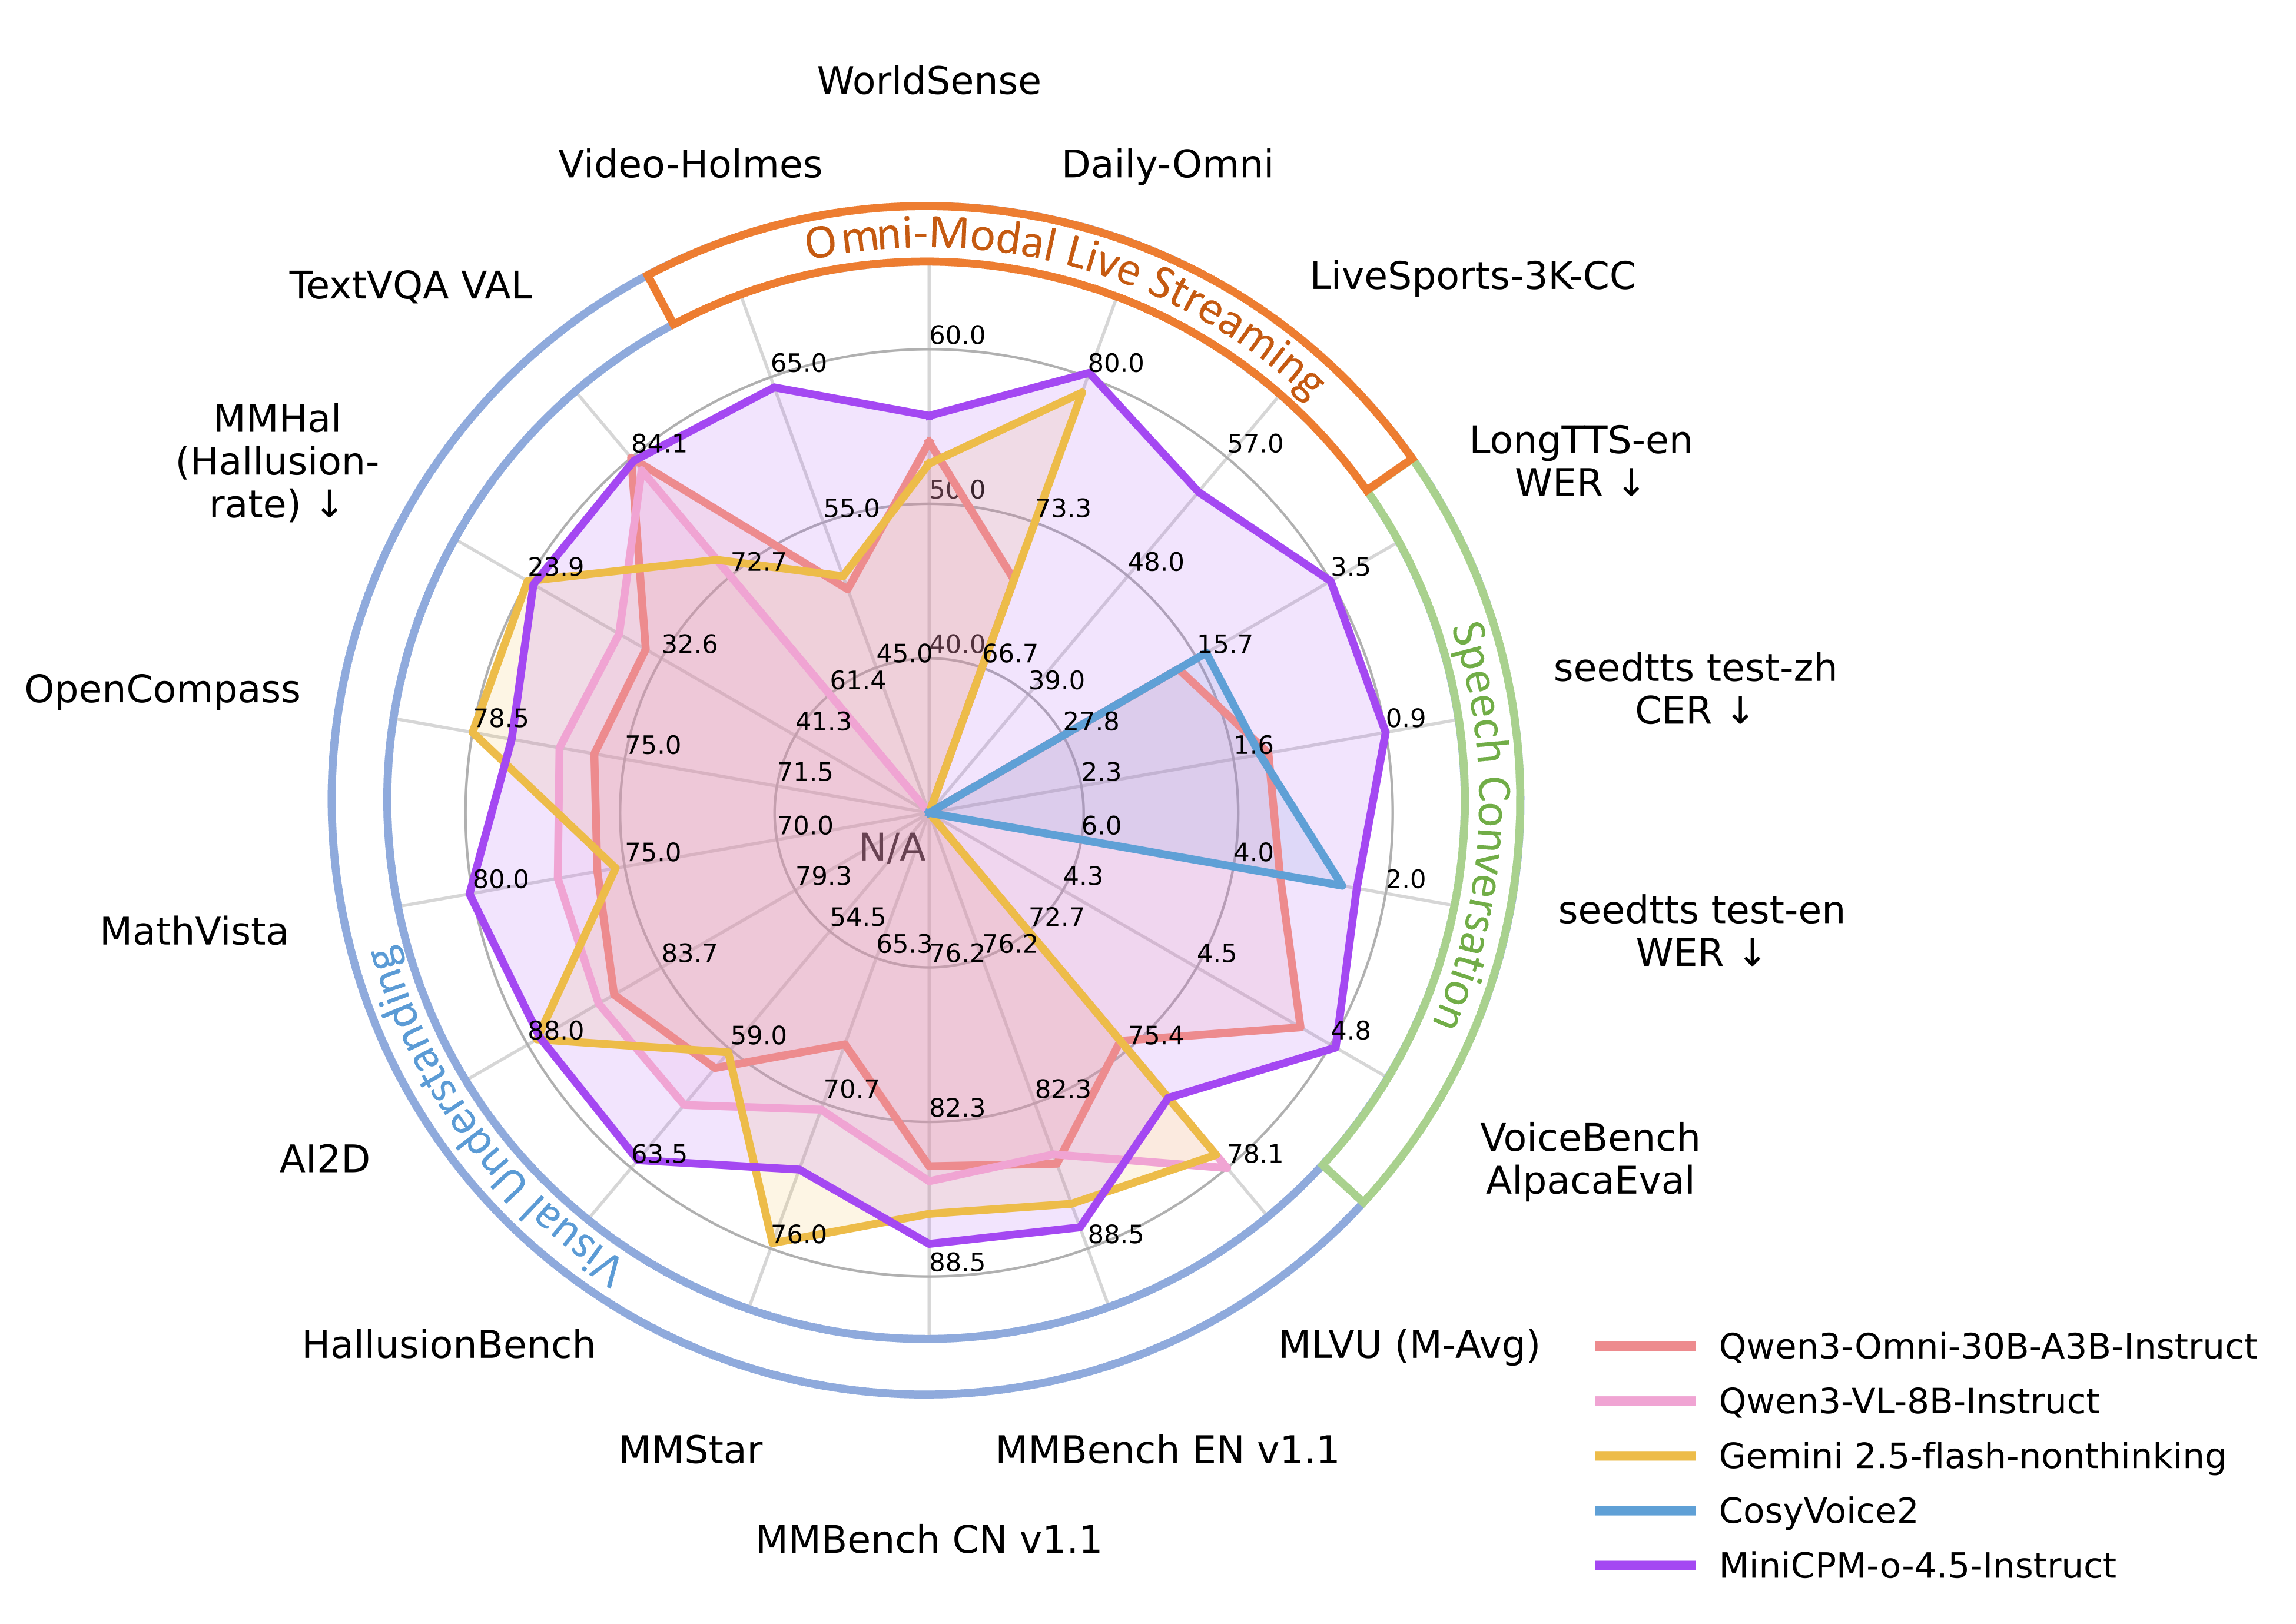
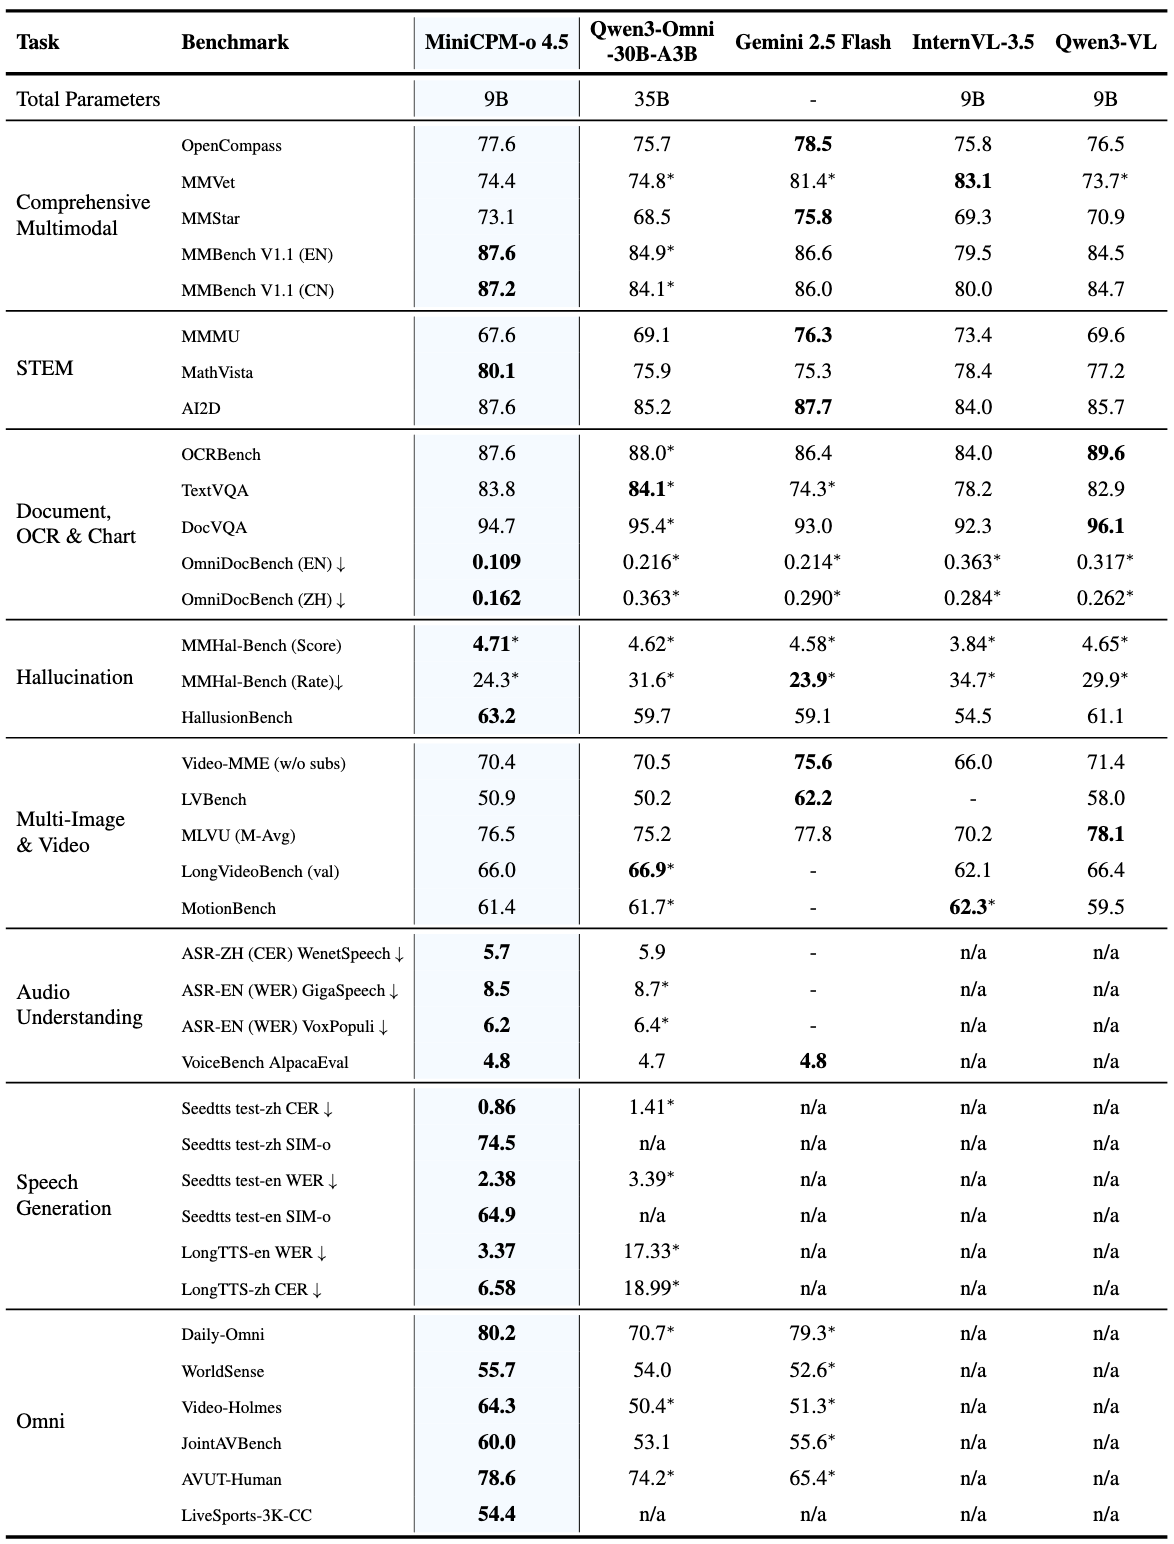
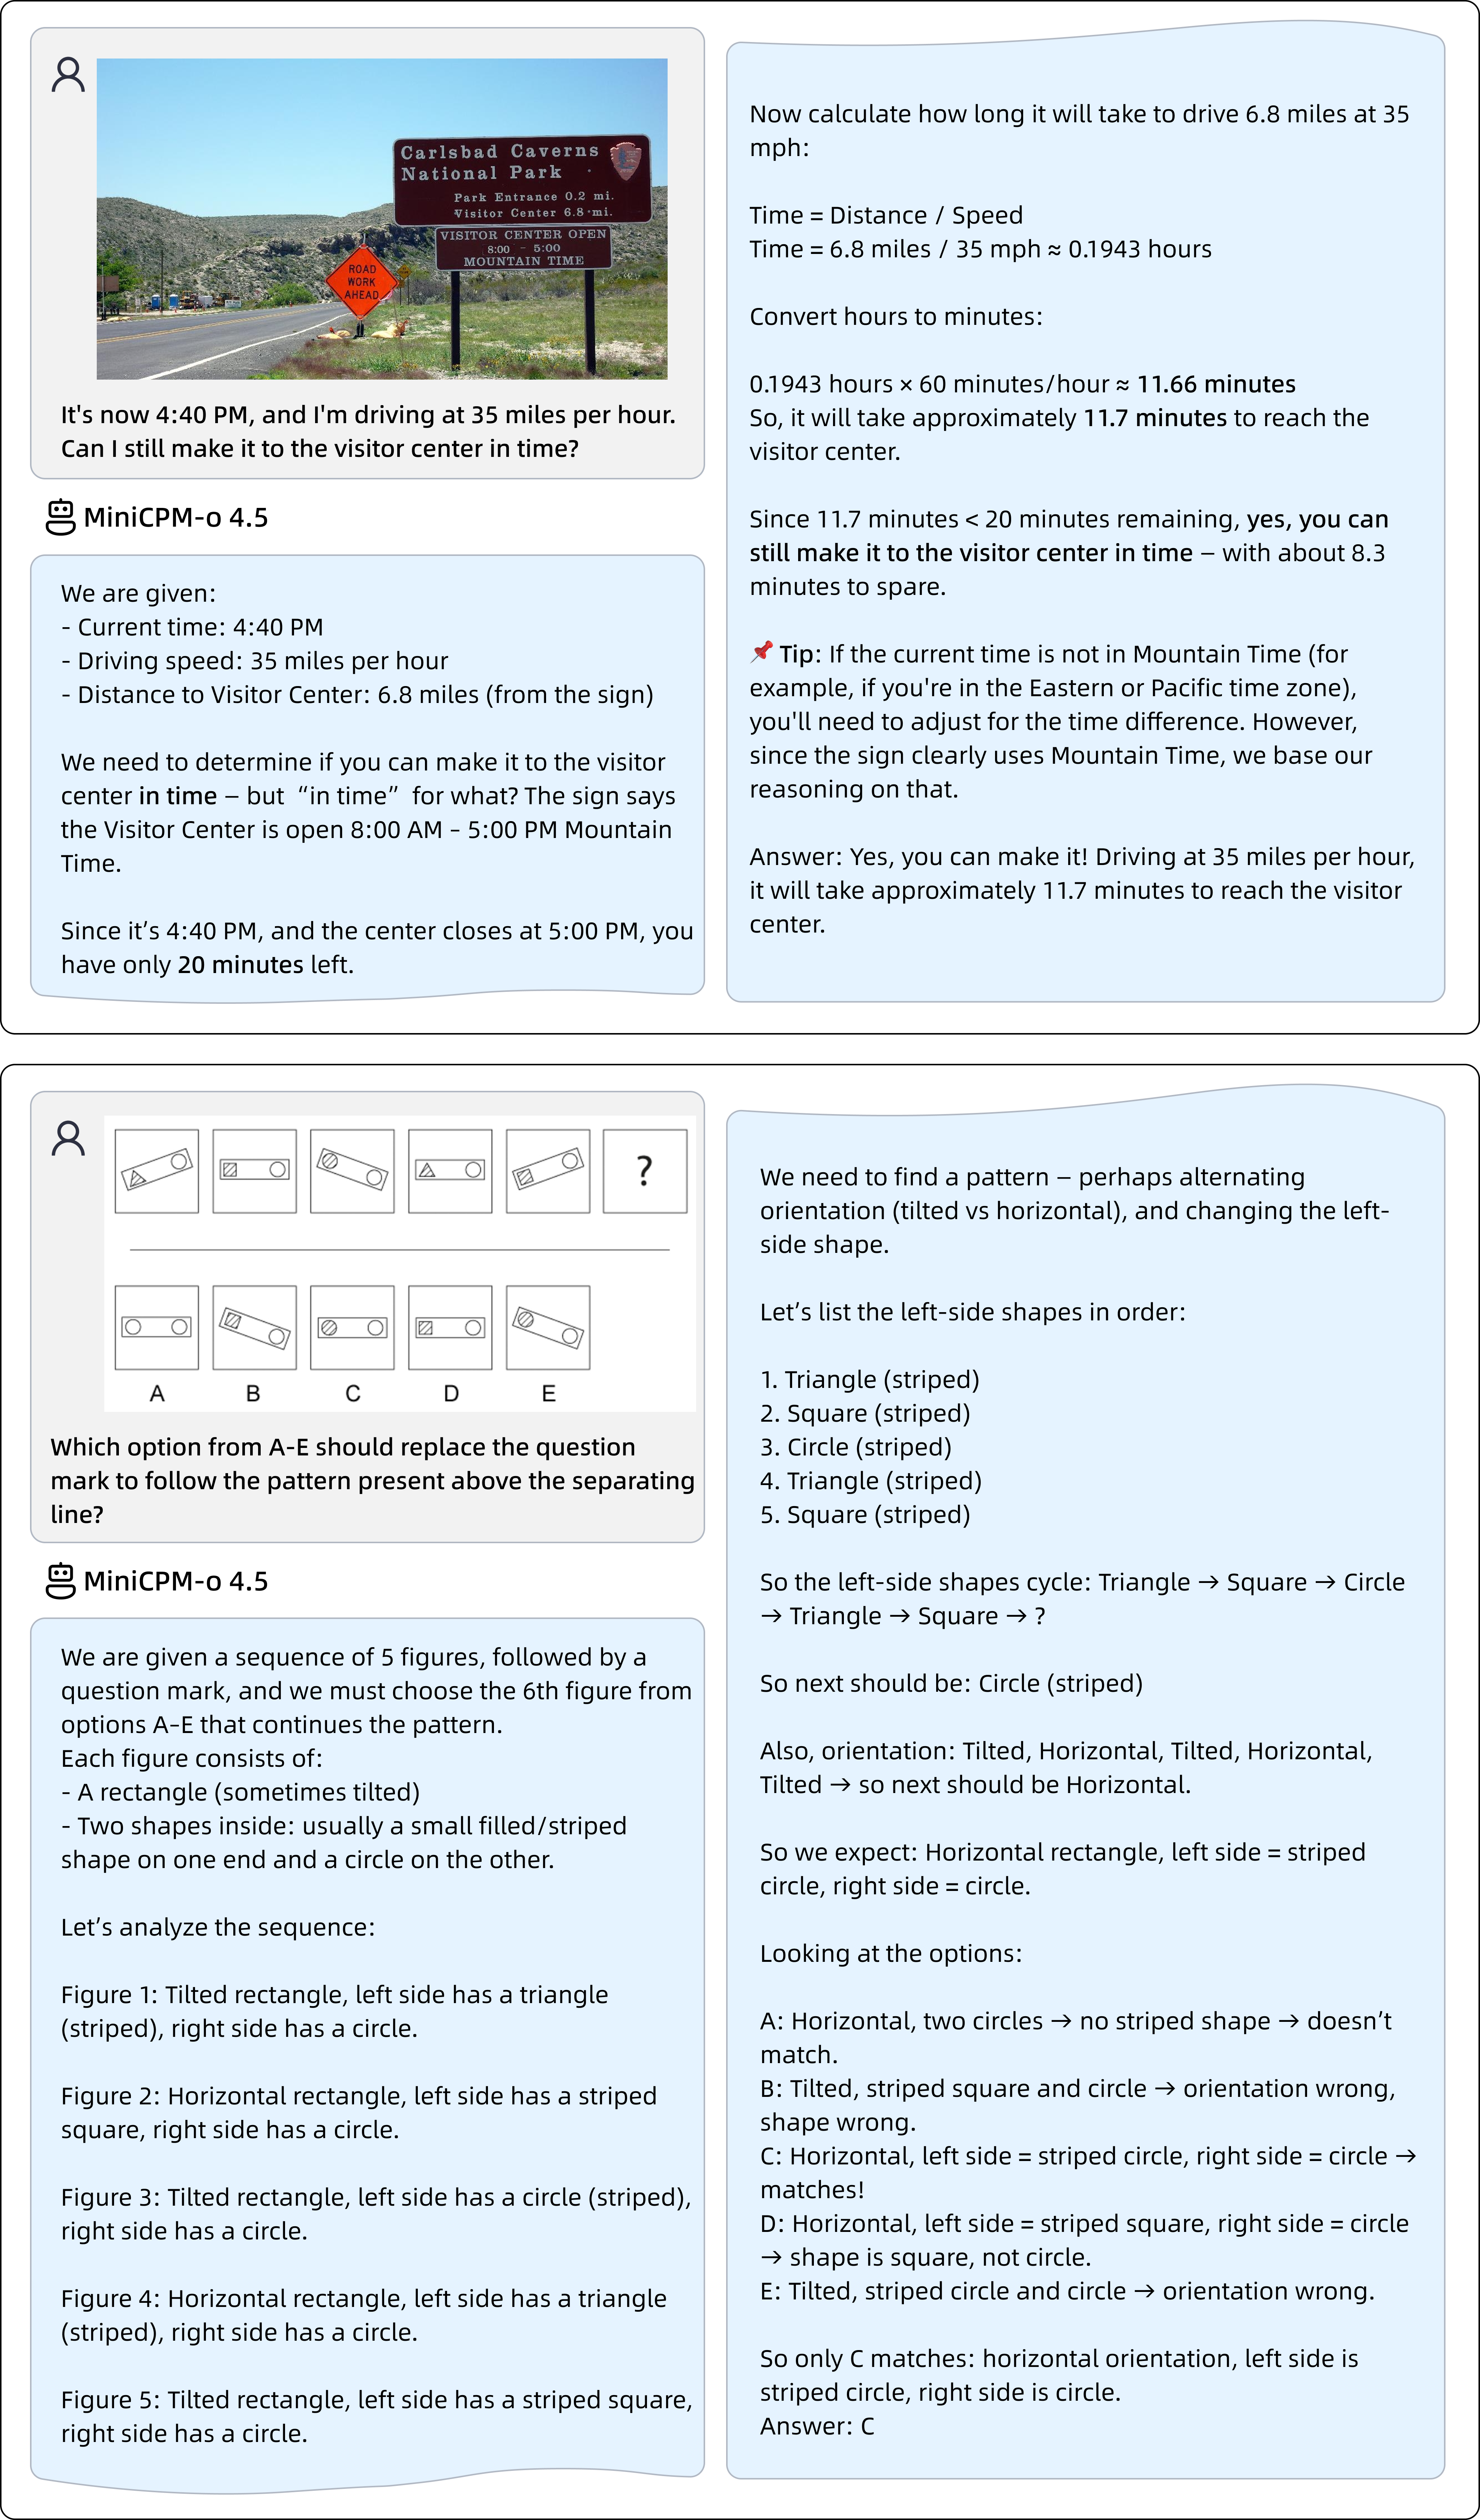
MiniCPM-o 4.5 achieves an average score of 77.6 on OpenCompass, a comprehensive evaluation of 8 popular benchmarks. With only 9B parameters, it surpasses widely used proprietary models like GPT-4o, Gemini 2.0 Pro, and approaches Gemini 2.5 Flash for vision-language capabilities. It supports instruct and thinking modes in a single model, better covering efficiency and performance trade-offs in different user scenarios.
-
🎙 Strong Speech Capability.
MiniCPM-o 4.5 supports bilingual real-time speech conversation with configurable voices in English and Chinese. It features more natural, expressive and stable speech conversation. The model also allows for fun features such as voice cloning and role play via a simple reference audio clip, where the cloning performance surpasses strong TTS tools such as CosyVoice2.
-
🎬 New Full-Duplex and Proactive Multimodal Live Streaming Capability.
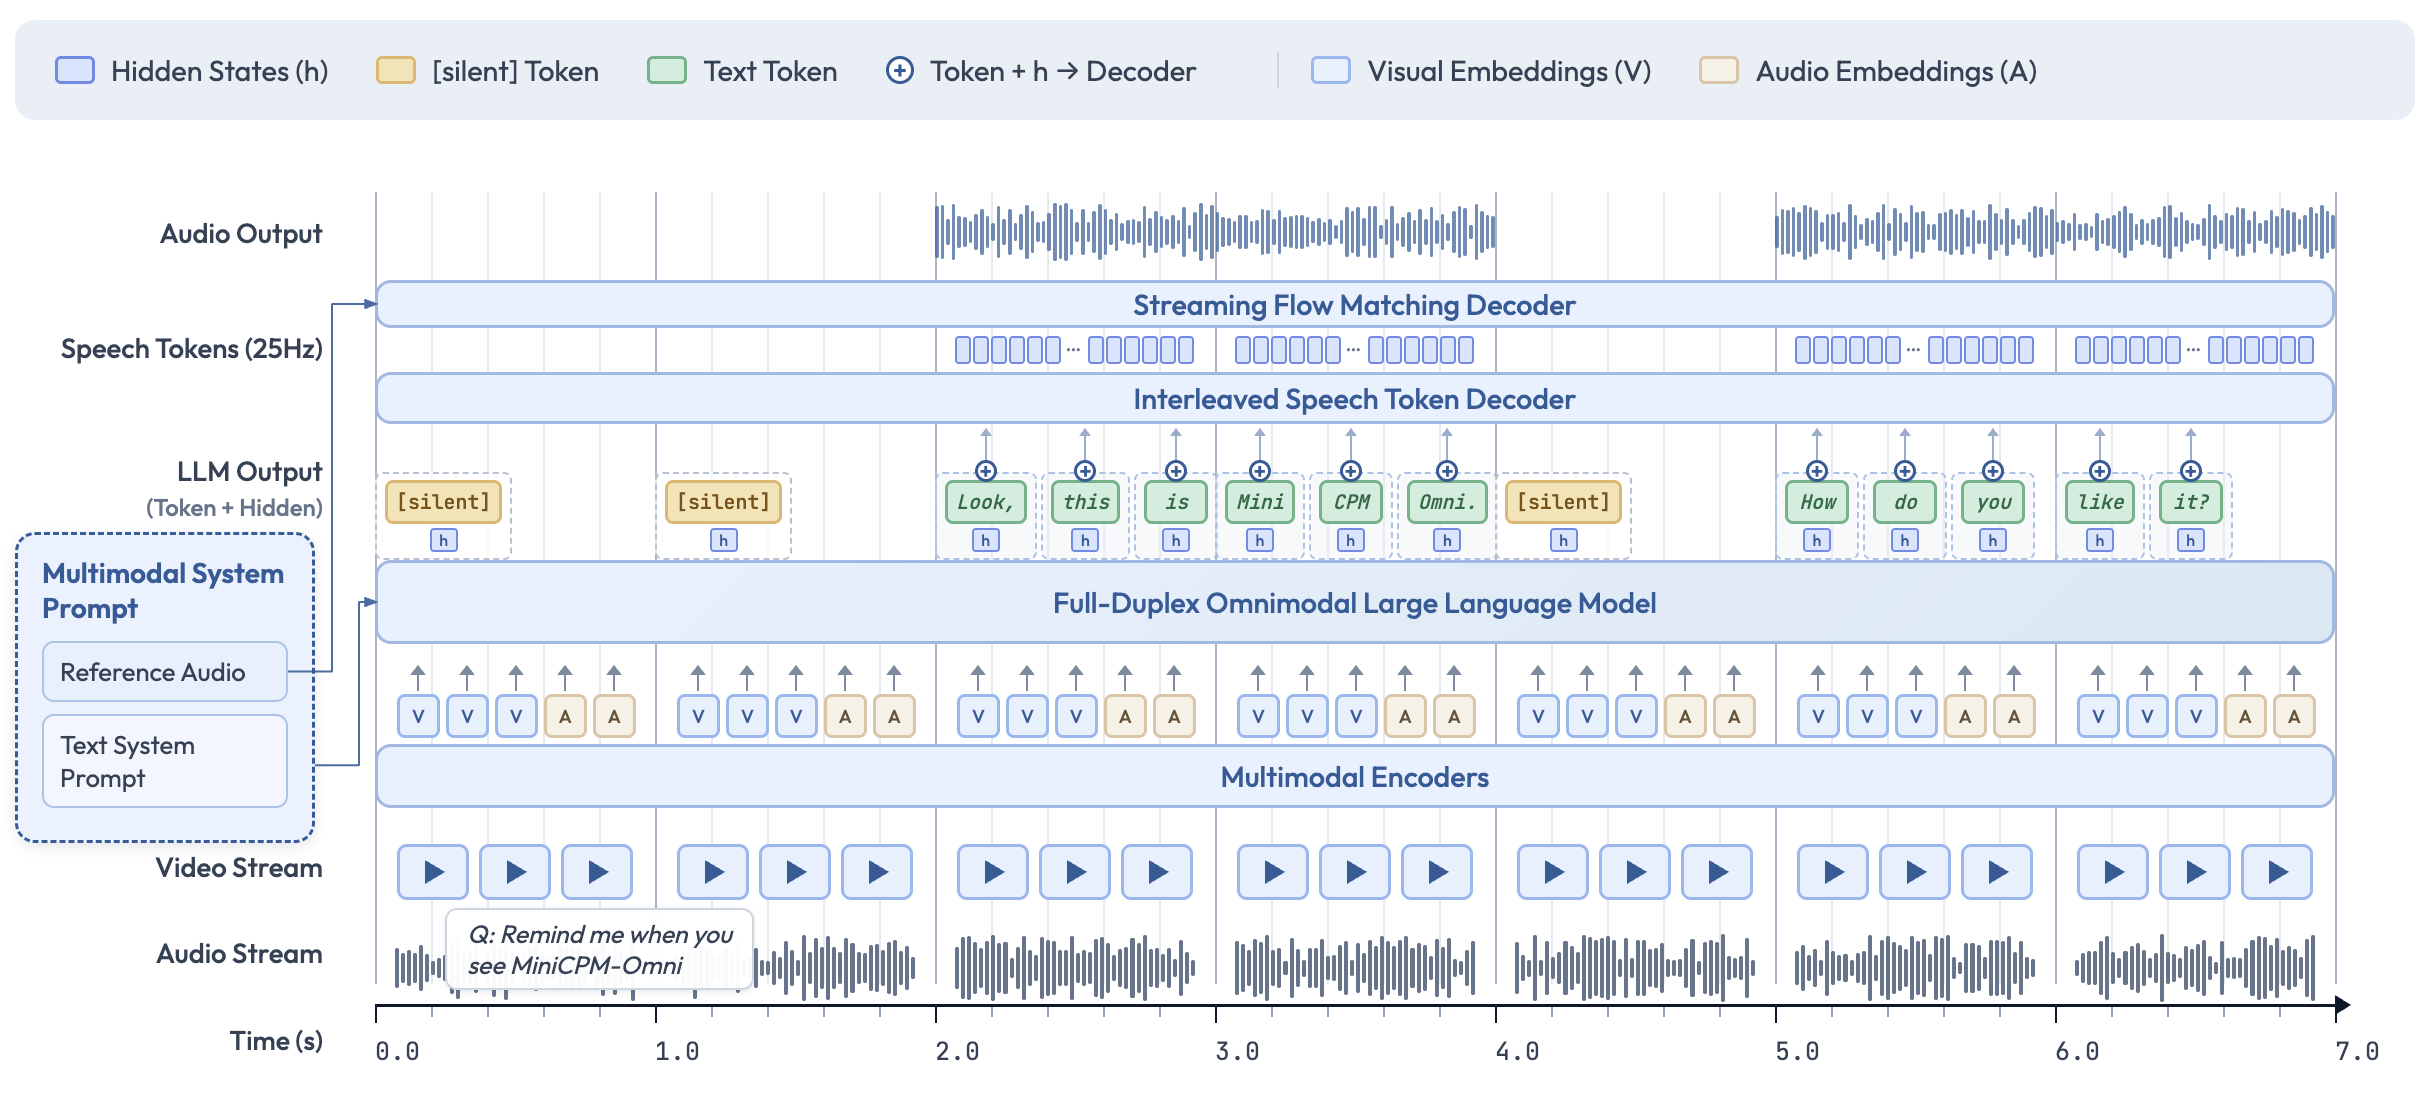
As a new feature, MiniCPM-o 4.5 can process real-time, continuous video and audio input streams simultaneously while generating concurrent text and speech output streams in an end-to-end fashion, without mutual blocking. This allows MiniCPM-o 4.5 to see, listen, and speak simultaneously, creating a fluid, real-time omnimodal conversation experience. Beyond reactive responses, the model can also perform proactive interaction, such as initiating reminders or comments based on its continuous understanding of the live scene.
-
💪 Strong OCR Capability, Efficiency and Others.
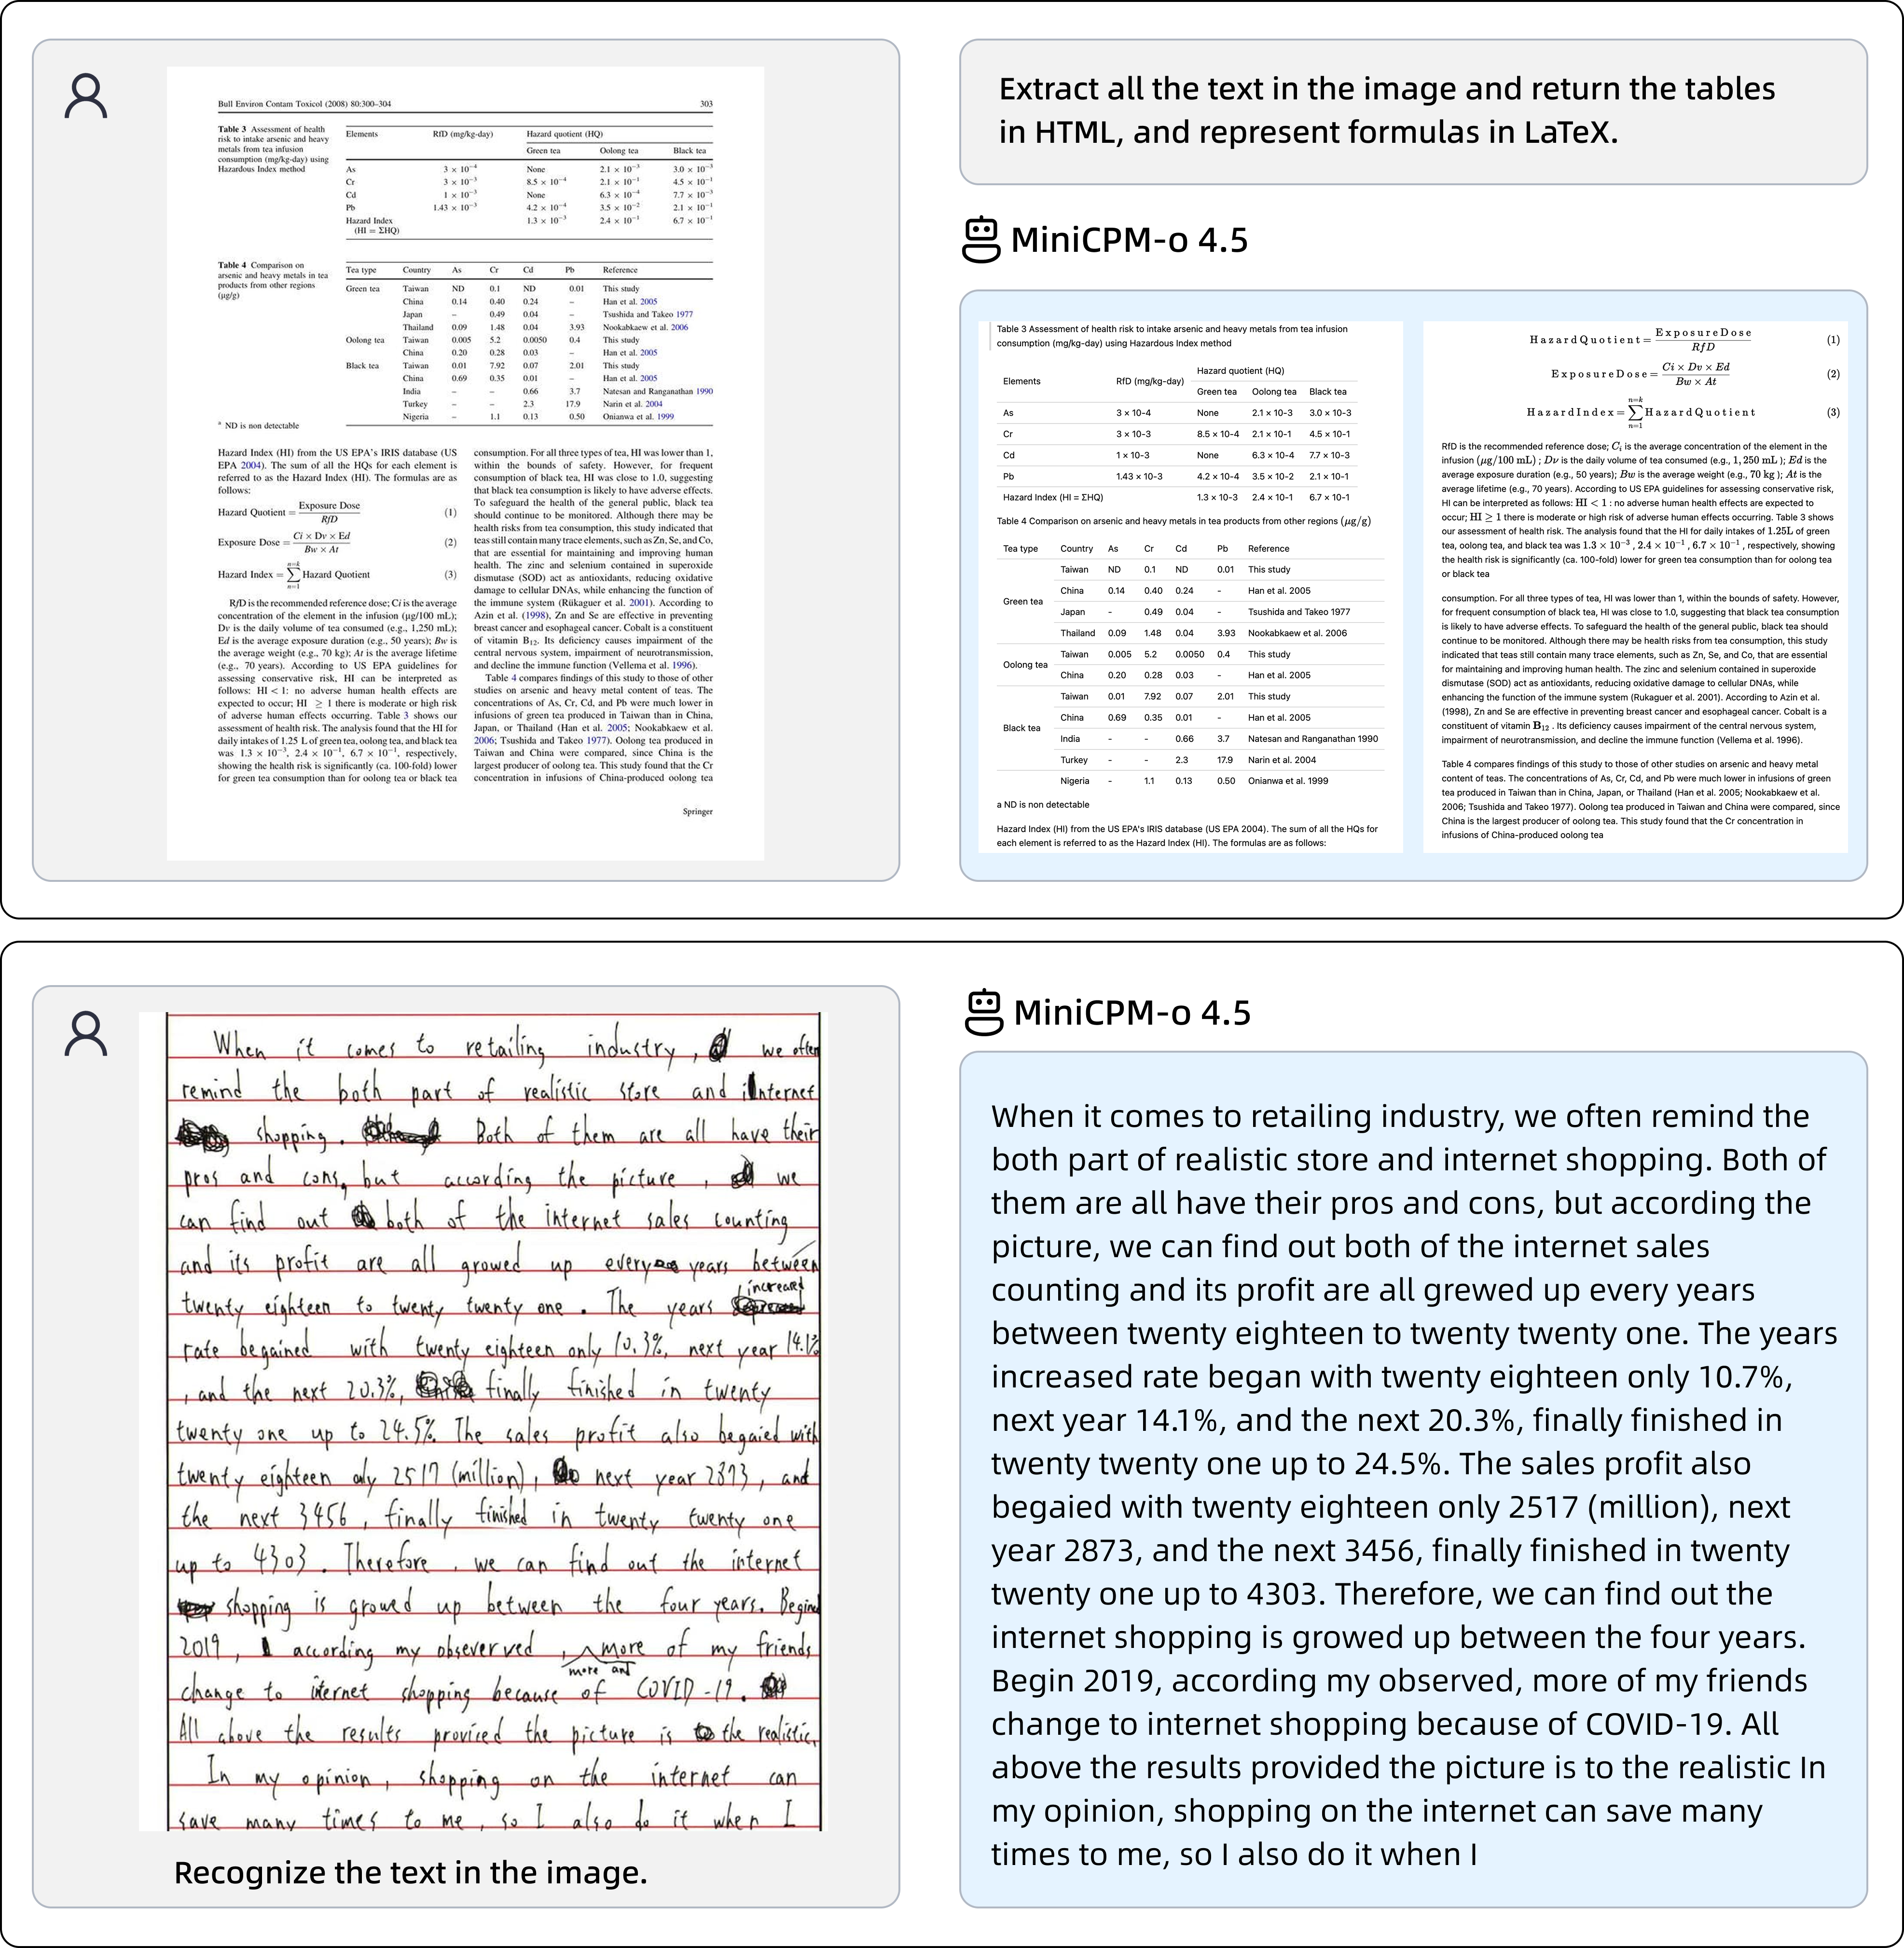
Advancing popular visual capabilities from MiniCPM-V series, MiniCPM-o 4.5 can process high-resolution images (up to 1.8 million pixels) and high-FPS videos (up to 10fps) in any aspect ratio efficiently. It achieves state-of-the-art performance for end-to-end English document parsing on OmniDocBench, outperforming proprietary models such as Gemini-3 Flash and GPT-5, and specialized tools such as DeepSeek-OCR 2. It also features trustworthy behaviors, matching Gemini 2.5 Flash on MMHal-Bench, and supports multilingual capabilities on more than 30 languages.
-
💫 Easy Usage.
MiniCPM-o 4.5 can be easily used in various ways: Basic usage, recommended for 100% precision: PyTorch inference with Nvidia GPU. Other end-side adaptation includes (1) llama.cpp and Ollama support for efficient CPU inference on local devices, (2) int4 and GGUF format quantized models in 16 sizes, (3) vLLM and SGLang support for high-throughput and memory-efficient inference, (4) FlagOS support for the unified multi-chip backend plugin. We also open-sourced web demos on which enables the full-duplex multimodal live streaming experience on local devices such as GPUs, PCs (e.g., on a MacBook).
Model Architecture.
- End-to-end Omni-modal Architecture. The modality encoders/decoders and LLM are densely connected via hidden states in an end-to-end fashion. This enables better information flow and control, and also facilitates full exploitation of rich multimodal knowledge during training.
- Full-Duplex Omni-modal Live Streaming Mechanism. (1) We turn the offline modality encoder/decoders into online and full-duplex ones for streaming inputs/outputs. The speech token decoder models text and speech tokens in an interleaved fashion to support full-duplex speech generation (i.e., sync timely with new input). This also facilitates more stable long speech generation (e.g., > 1min).
(2) We sync all the input and output streams on timeline in milliseconds, which are jointly modeled by a time-division multiplexing (TDM) mechanism for omni-modality streaming processing in the LLM backbone. It divides parallel omni-modality streams into sequential info groups within small periodic time slices.
- Proactive Interaction Mechanism. The LLM continuously monitors the input video and audio streams, and decides at a frequency of 1Hz to speak or not. This high decision-making frequency together with full-duplex nature are curcial to enable the proactive interaction capability.
- Configurable Speech Modeling Design. We inherent the multimodal system prompt design of MiniCPM-o 2.6, which includes a traditional text system prompt, and a new audio system prompt to determine the assistant voice. This enables cloning new voices and role play in inference time for speech conversation.
Evaluation
Note: Scores marked with ∗ are from our evaluation; others are cited from referenced reports. n/a indicates that the model does not support the corresponding modality. All results are reported in instruct mode/variant.
Click to view visual understanding results.
Image Understanding (Instruct)
Image Understanding (Thinking)
Video Understanding
Click to view document parsing results.
OmniDocBench
Click to view text capability results.
Text Capability
Click to view omni half-duplex results.
Omni Half-Duplex
Click to view vision duplex results.
Vision Duplex
Click to view audio understanding results.
Audio Understanding
Click to view speech generation results.
Speech Generation
Long Speech Generation
Emotion Control
Click to view inference efficiency results.
Inference Efficiency
Examples
Overall
Omnimodal Full-Duplex Conversation
[!NOTE]
For detailed speech conversation examples, refer to Omni Full-Duplex Casebook
Realtime Speech Conversation
[!NOTE]
For detailed speech conversation examples, refer to Audio Casebook
🚀 Elon Musk - Voice Roleplay (EN)
🤖 MiniCPM Assistant - Voice Acting: Emotion Shift (ZH)
Visual Understanding
Click to view visual understanding cases.
Usage
Note: This GPTQ model is pre-quantized to W4A16, reducing GPU memory usage from ~19GB (BF16) to ~11GB (INT4). For loading, use torch_dtype=torch.bfloat16 with device_map="auto" — the quantized layers weight format is automatically handled by the GPTQ kernel.
For omni-modal inference (vision + audio), ensure init_vision=True, init_audio=True, init_tts=True. For vision-only inference, set init_audio=False and init_tts=False.
For detailed usage (chat, streaming, full-duplex, TTS, visual understanding, etc.), see the base model README and the Cookbook.
License
Model License
- The MiniCPM-o/V model weights and code are open-sourced under the Apache-2.0 license.
Statement
- As MLLMs, MiniCPM-o/V models generate content by learning a large number of multimodal corpora, but they cannot comprehend, express personal opinions, or make value judgements. Anything generated by MiniCPM-o/V models does not represent the views and positions of the model developers
- We will not be liable for any problems arising from the use of MiniCPM-o/V models, including but not limited to data security issues, risk of public opinion, or any risks and problems arising from the misdirection, misuse, dissemination, or misuse of the model.
Key Techniques and Other Multimodal Projects
👏 Welcome to explore key techniques of MiniCPM-o/V and other multimodal projects of our team:
VisCPM | RLPR | RLHF-V | LLaVA-UHD | RLAIF-V
Citation
If you find our model/code/paper helpful, please consider citing our papers 📝 and staring us ⭐️!