This repository hosts the GGUF (llama.cpp) quantized version of MiniCPM-V 4.7 35B-A3B. For the original BF16 weights and the full model card, please refer to openbmb/MiniCPM-V-4.7-35B-A3B.
MiniCPM-V 4.7
GitHub · On-device results · Evaluation · Examples · Usage · Model weights · DSpark
MiniCPM-V 4.7 is the latest model in the MiniCPM-V series, available in a 35B-A3B variant, with 35B-A3B being the first MoE model in the MiniCPM-V series. It builds on the family's single-image, multi-image, and video understanding capabilities, combining stronger foundation capabilities with efficient visual encoding and on-device inference. Notable features of MiniCPM-V 4.7 include:
- 📱 The First Open-Source MoE Model with Lossless, Smooth On-Device Inference.
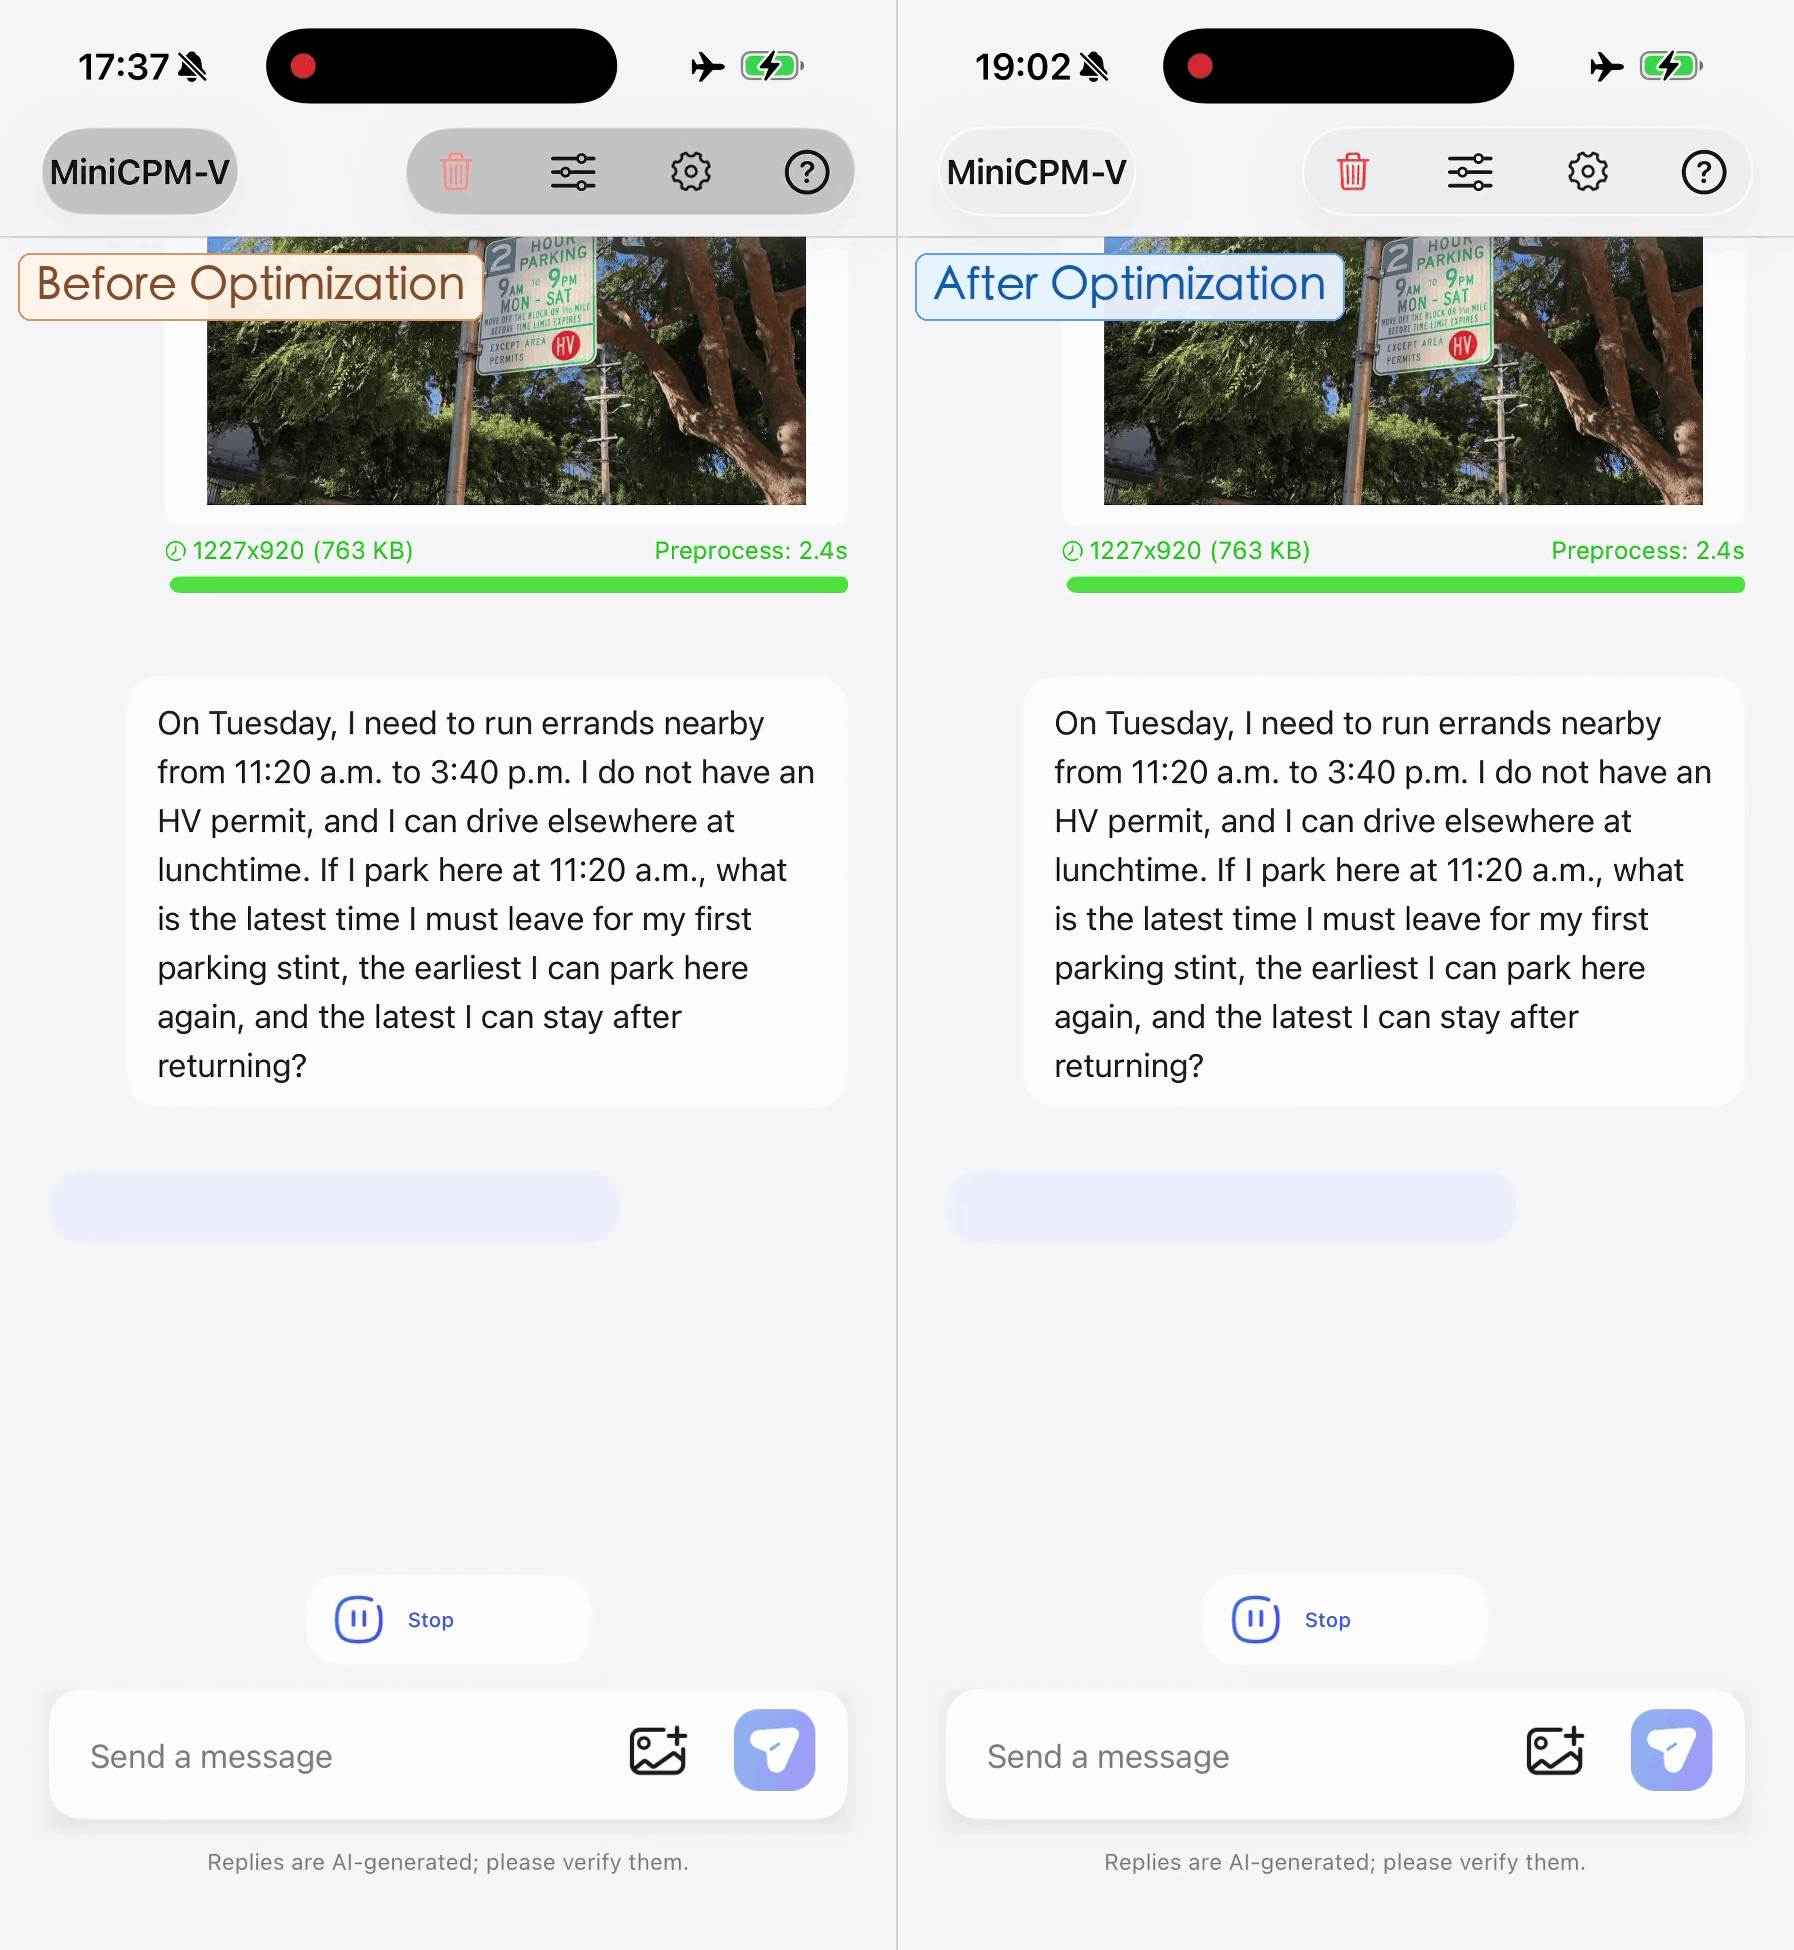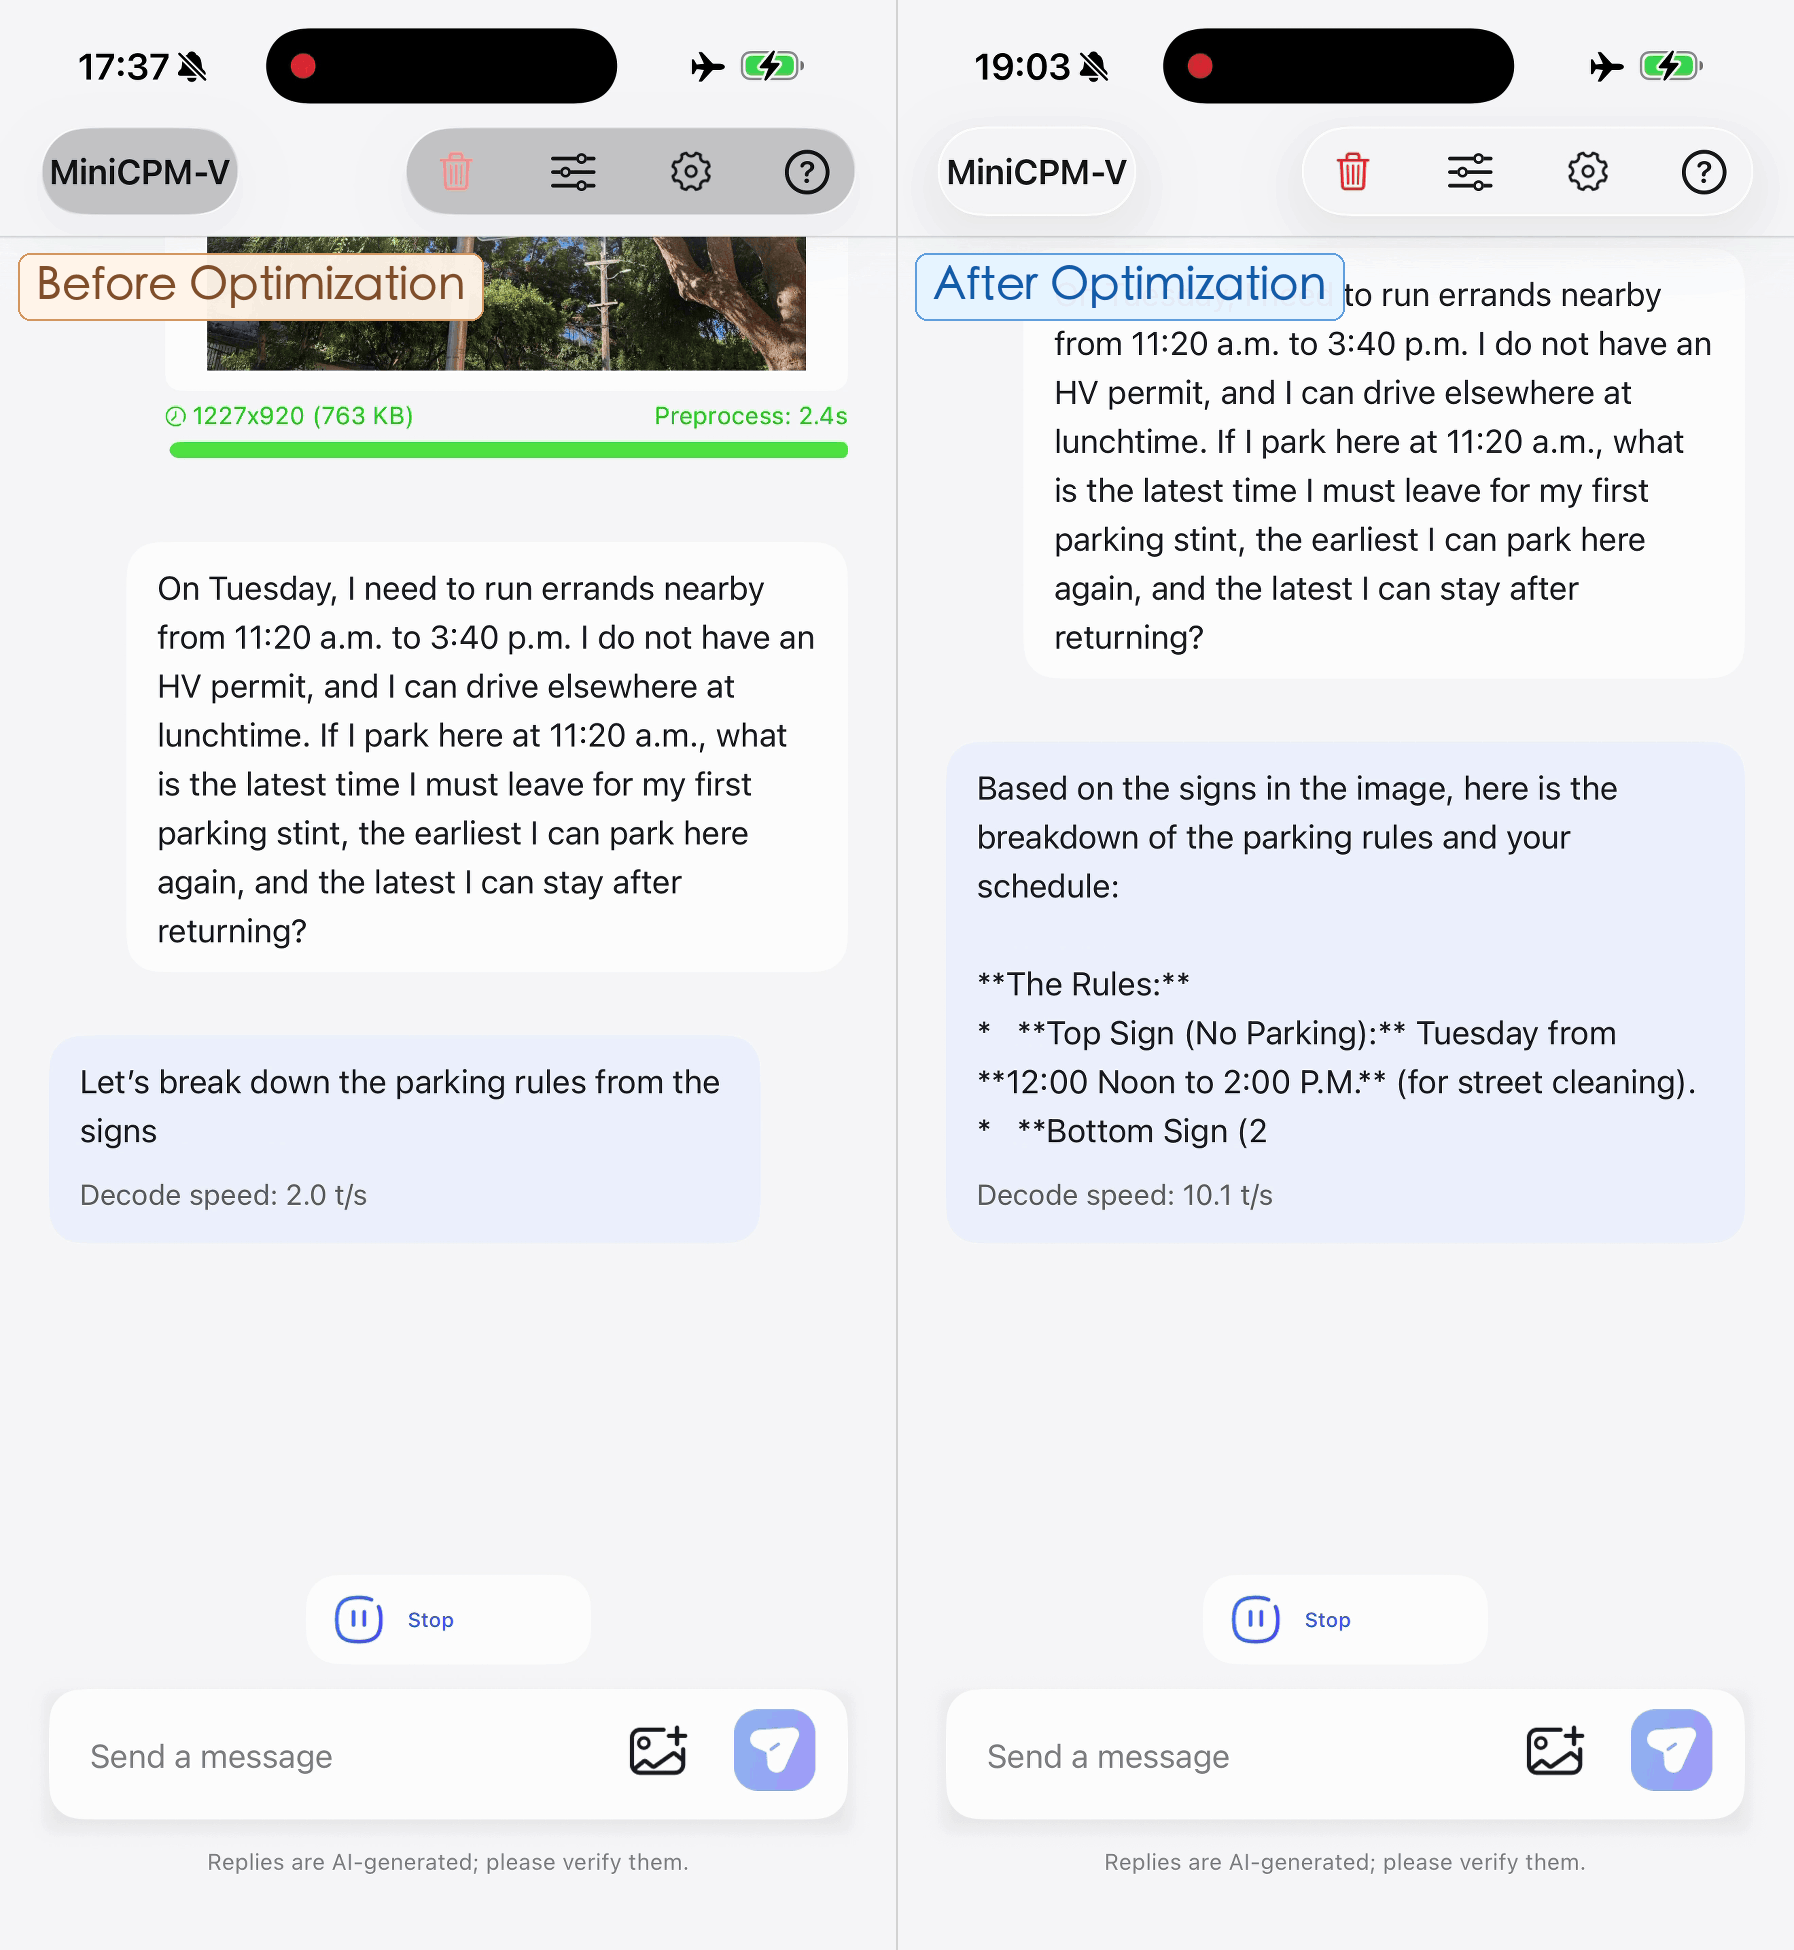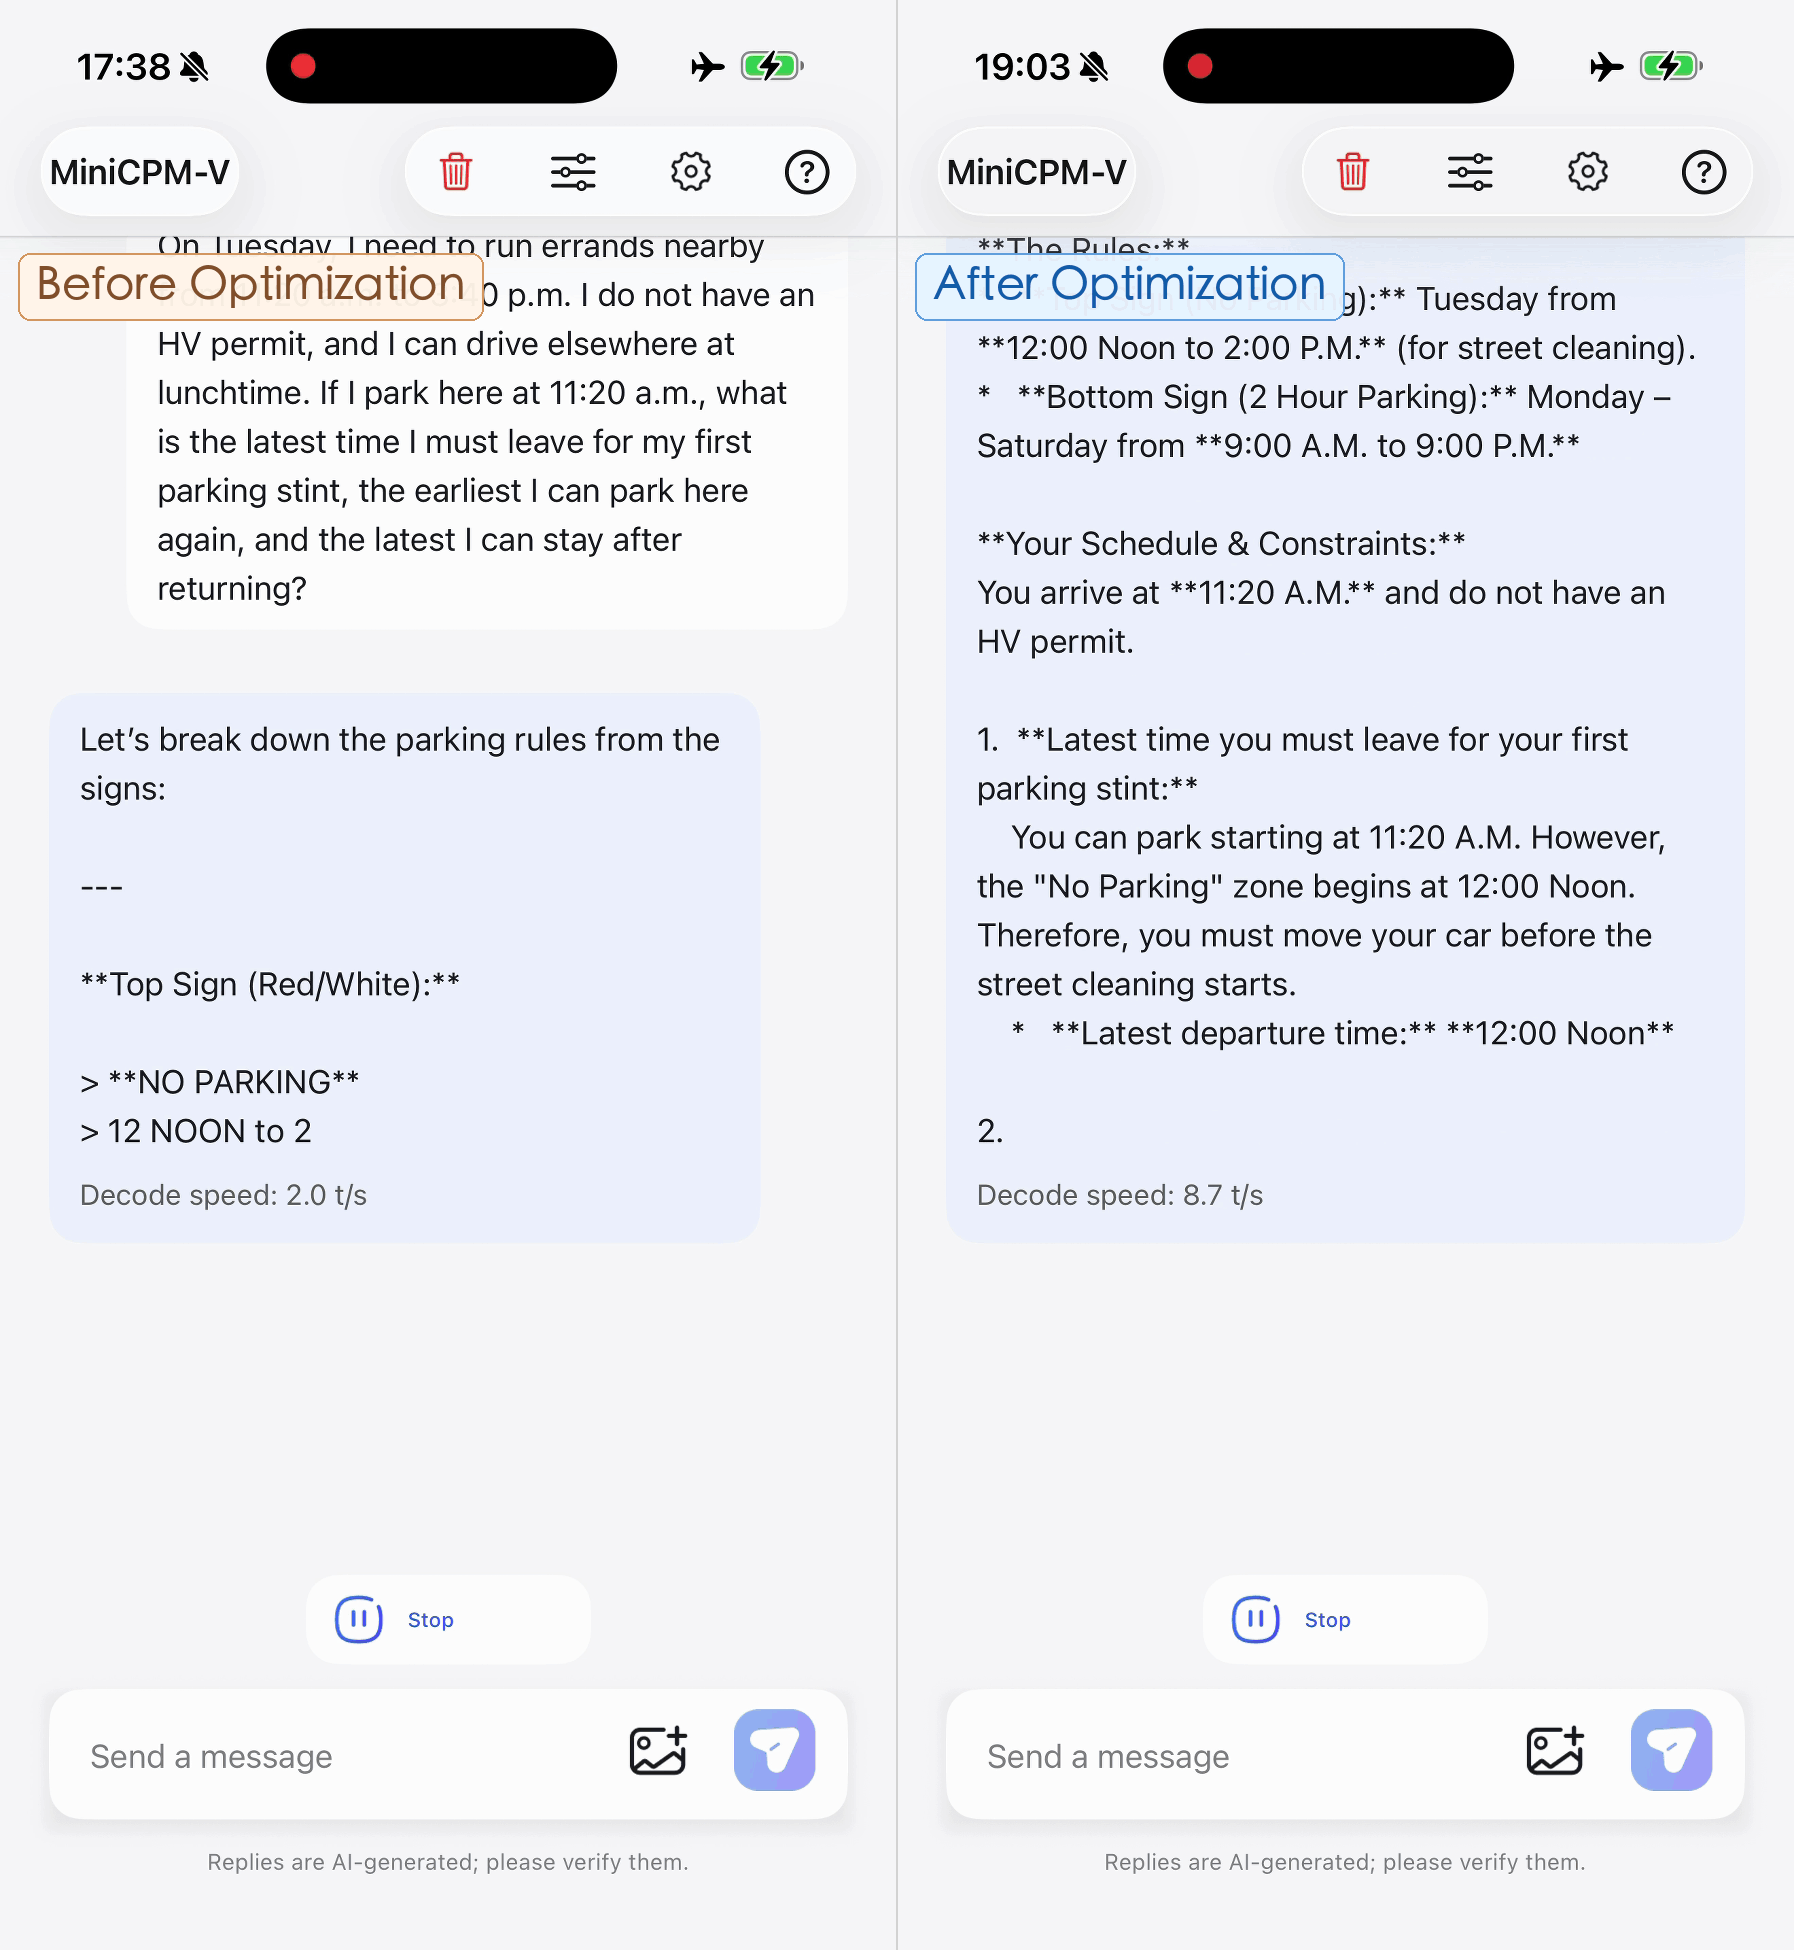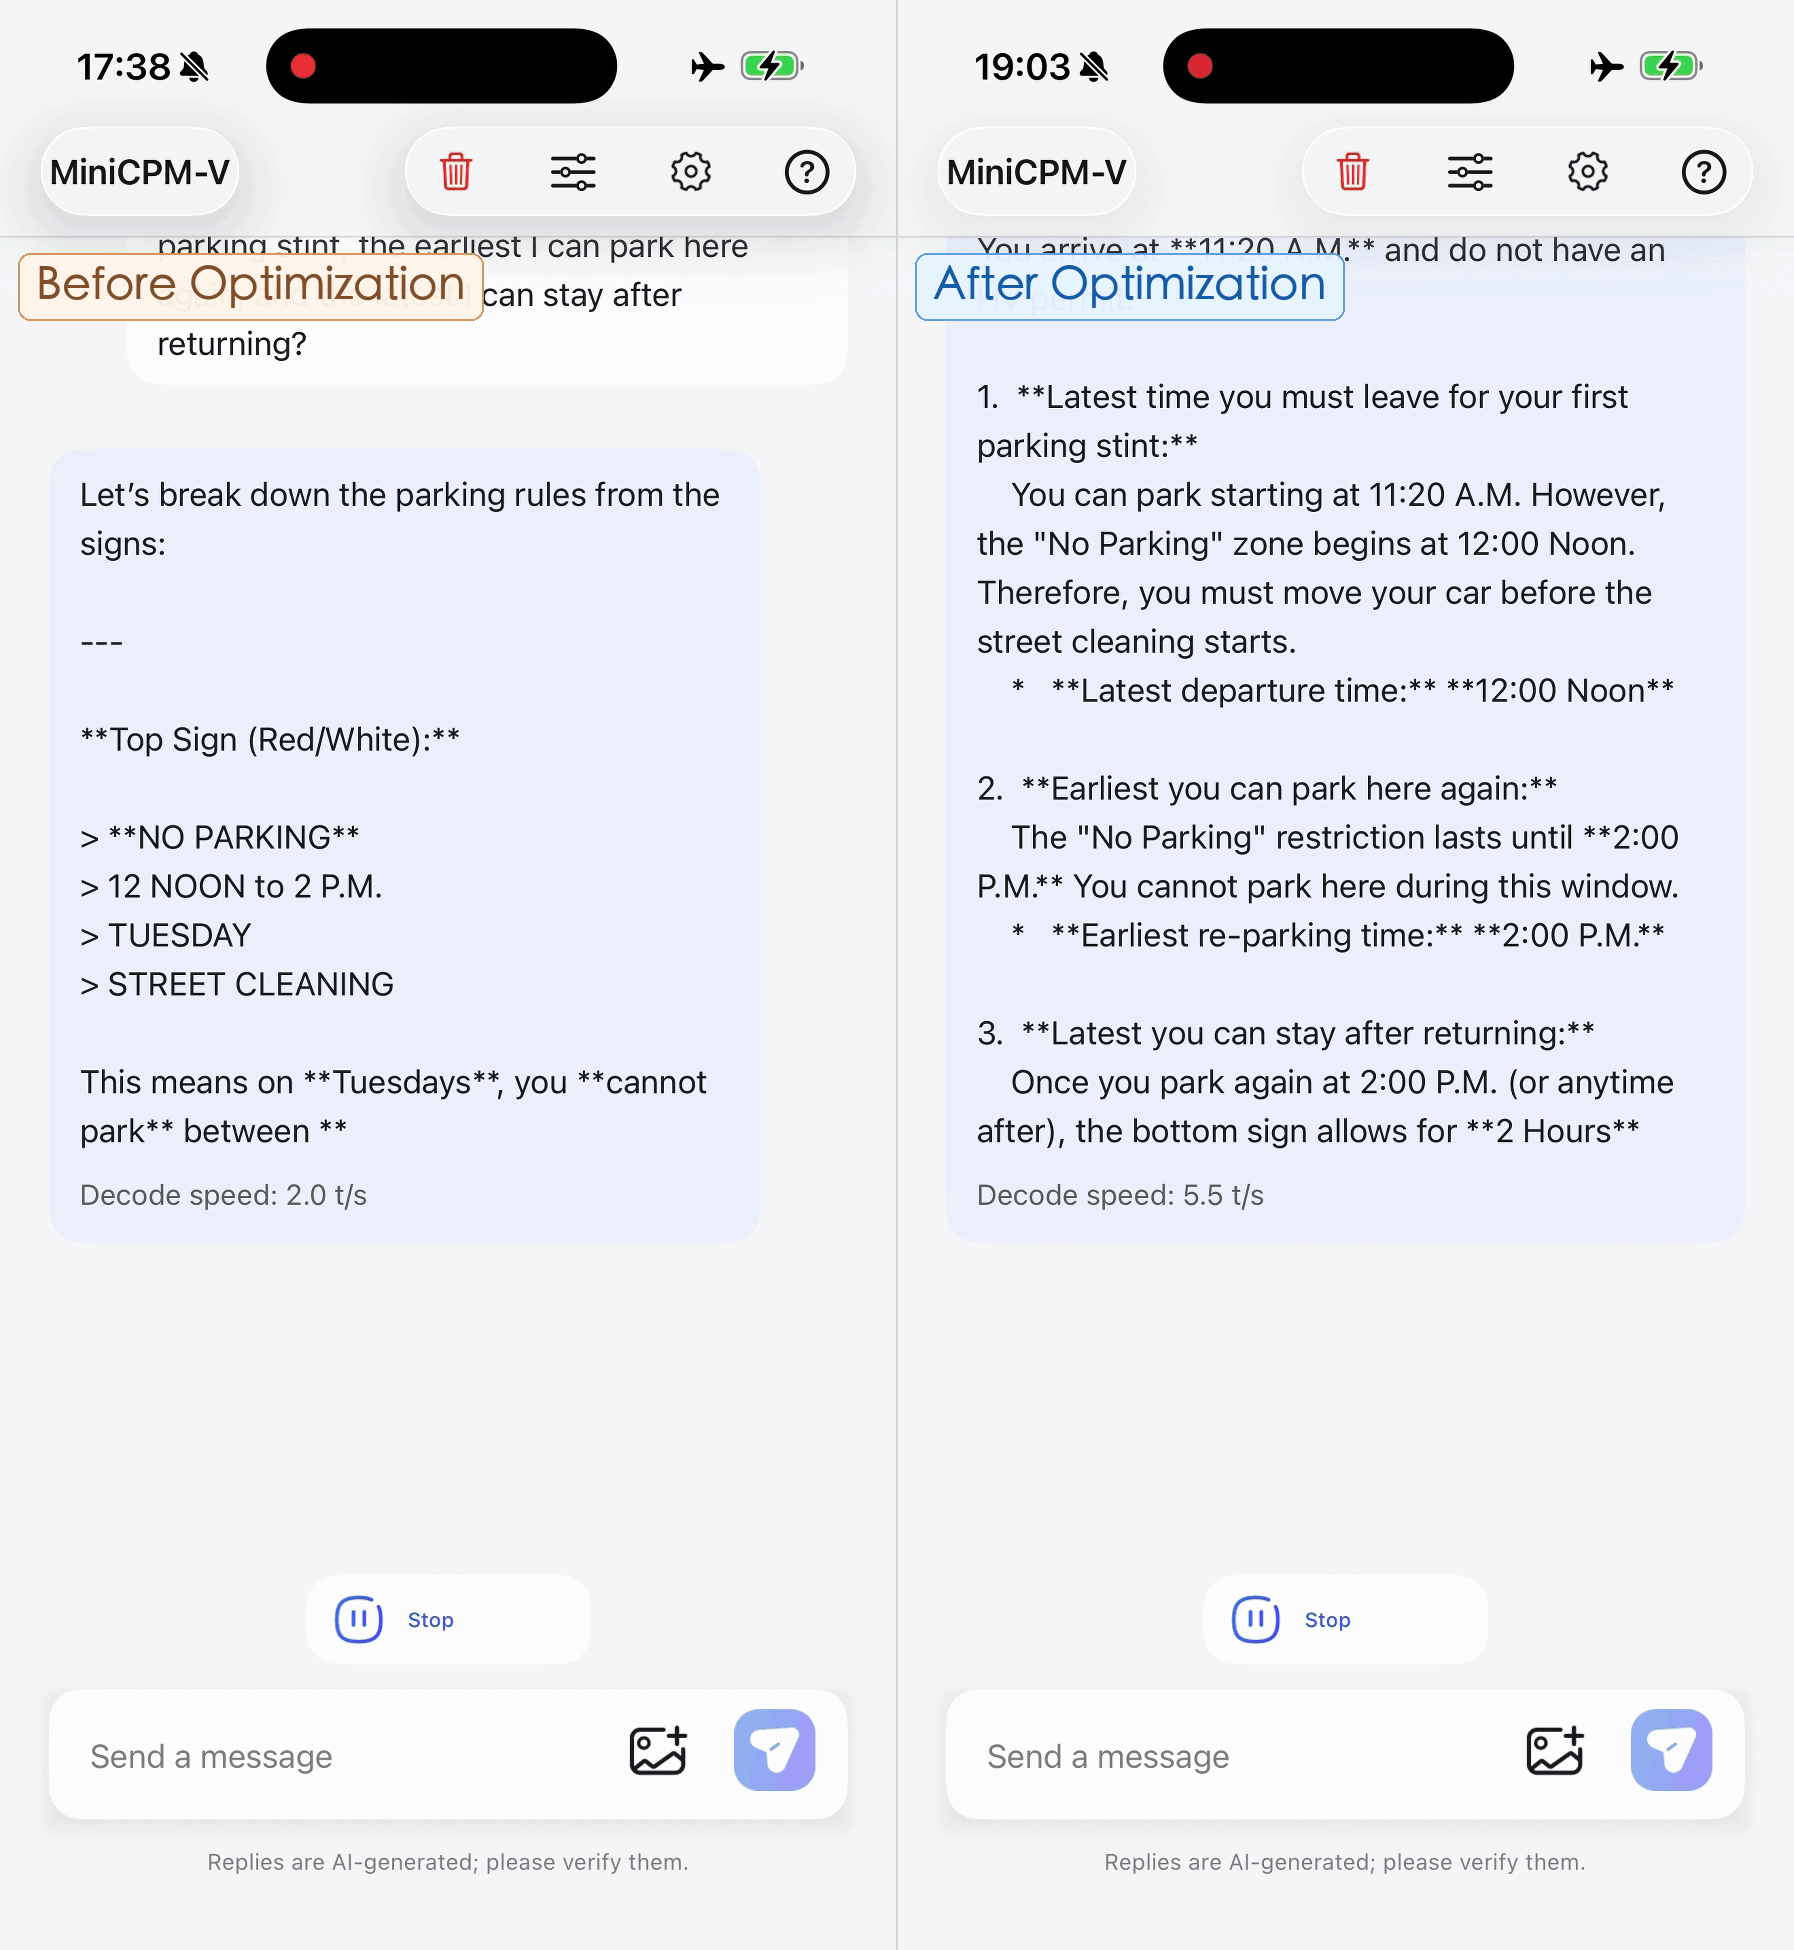
With our Lookahead Expert Scheduling (LES) technique introduced alongside MiniCPM-V 4.7, combined with fine-grained layer-wise quantization and DSpark speculative sampling integration, MiniCPM-V 4.7 35B-A3B becomes the first open-source MoE model to run smoothly on-device without compromising performance, achieving a decoding speed of 13+ tokens/s with just 3 GB of memory on iPhone 17 Pro Max.
- 🔥 A New Pareto Frontier in Performance and Efficiency.
As model capabilities continue to advance, inference efficiency has become an important measure of a model's value. On resource-constrained devices, delivering the strongest possible capabilities within a limited resource budget calls for higher capability density. The 35B-A3B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier for MLLMs. In Instruct mode, 35B-A3B achieves a higher overall score in less inference time than Qwen3.6 35B-A3B.
- 🚀 Efficient Architecture.
Based on the intra-ViT early compression technique from LLaVA-UHD v4, MiniCPM-V 4.7 compresses visual tokens early within the vision encoder, reducing computation in subsequent encoder layers. It also supports mixed 4x/16x visual token compression, allowing developers to balance visual detail and inference cost across tasks.
- 💻 Broad Platform and Chip Support.
MiniCPM-V 4.7 supports iOS, Android, and HarmonyOS, together with open-source on-device deployment support. It also provides day-0 support for chip platforms from Rockchip, Houmo, Intel, AMD, and Arm, extending deployment options across mobile and local computing devices.
- 🛠️ Developer Friendly.
MiniCPM-V 4.7 supports inference frameworks including SGLang, vLLM, llama.cpp, and Ollama, along with fine-tuning frameworks including SWIFT and LLaMA-Factory. It provides GGUF, BNB, AWQ, and GPTQ quantized variants and adds FP8 quantization support. We also release Self-Replay Fine-Tuning (SRFT), a fine-tuning approach that helps developers extend model capabilities at low cost while reducing forgetting of existing capabilities, making further customization easier.
Get started
Model weights ·
Inference ·
Fine-tuning ·
Live demo ·
Local deployment ·
API ·
Cookbook
On-Device Capability and Efficiency
Smooth On-Device MoE Inference without compromising performance
An MoE model can have far more total parameters than it activates for a single token, but its on-device storage requirements are not limited to those active parameters. Different tokens can select different experts at different layers, while device memory often cannot hold all expert weights. Without a latency constraint, weights can remain on SSD or other storage, be loaded as needed, and be released after computation. This makes large-model inference possible, but repeated loading stalls can make decoding too slow for real-time interaction.
Another approach is to restrict the pool of available experts. For example, fixing an expert subset for an entire prompt can reduce loading frequency, but limits subsequent token-level routing to that subset, potentially excluding experts the model would otherwise select and reducing its capabilities. The central goal is therefore smooth inference without compromising performance: preserving model capability while delivering sufficient throughput under limited memory and bandwidth.
MiniCPM-V 4.7 35B-A3B addresses this challenge through three complementary techniques:
- Lookahead Expert Scheduling (LES) uses cross-layer routing prediction to preload experts likely to be needed by the next layer. Among the experts selected by the actual router, it prioritizes those successfully prefetched and overlaps their computation with loading the remaining required experts. Predictions guide only prefetching and scheduling; computation still follows the model's original token-level routing, and required experts missed by the prediction are loaded and evaluated as usual.
- Fine-grained layer-wise quantization reduces the storage footprint and memory traffic of expert weights while preserving model capability, making expert loading better suited to on-device memory and bandwidth constraints.
- DSpark speculative sampling integration incorporates speculative sampling into the on-device inference process, working with expert scheduling and quantization to improve decoding efficiency.
Together, these techniques make MiniCPM-V 4.7 35B-A3B the first open-source MoE model to run smoothly on-device without compromising performance, achieving 13+ tokens/s on iPhone 17 Pro Max.
On-Device MoE Inference: Before and After Optimization
Evaluation
Significantly Advancing the Performance–Efficiency Pareto Frontier
The 35B-A3B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier. In Instruct mode, 35B-A3B reaches a higher overall score in less inference time than Qwen3.6 35B-A3B.
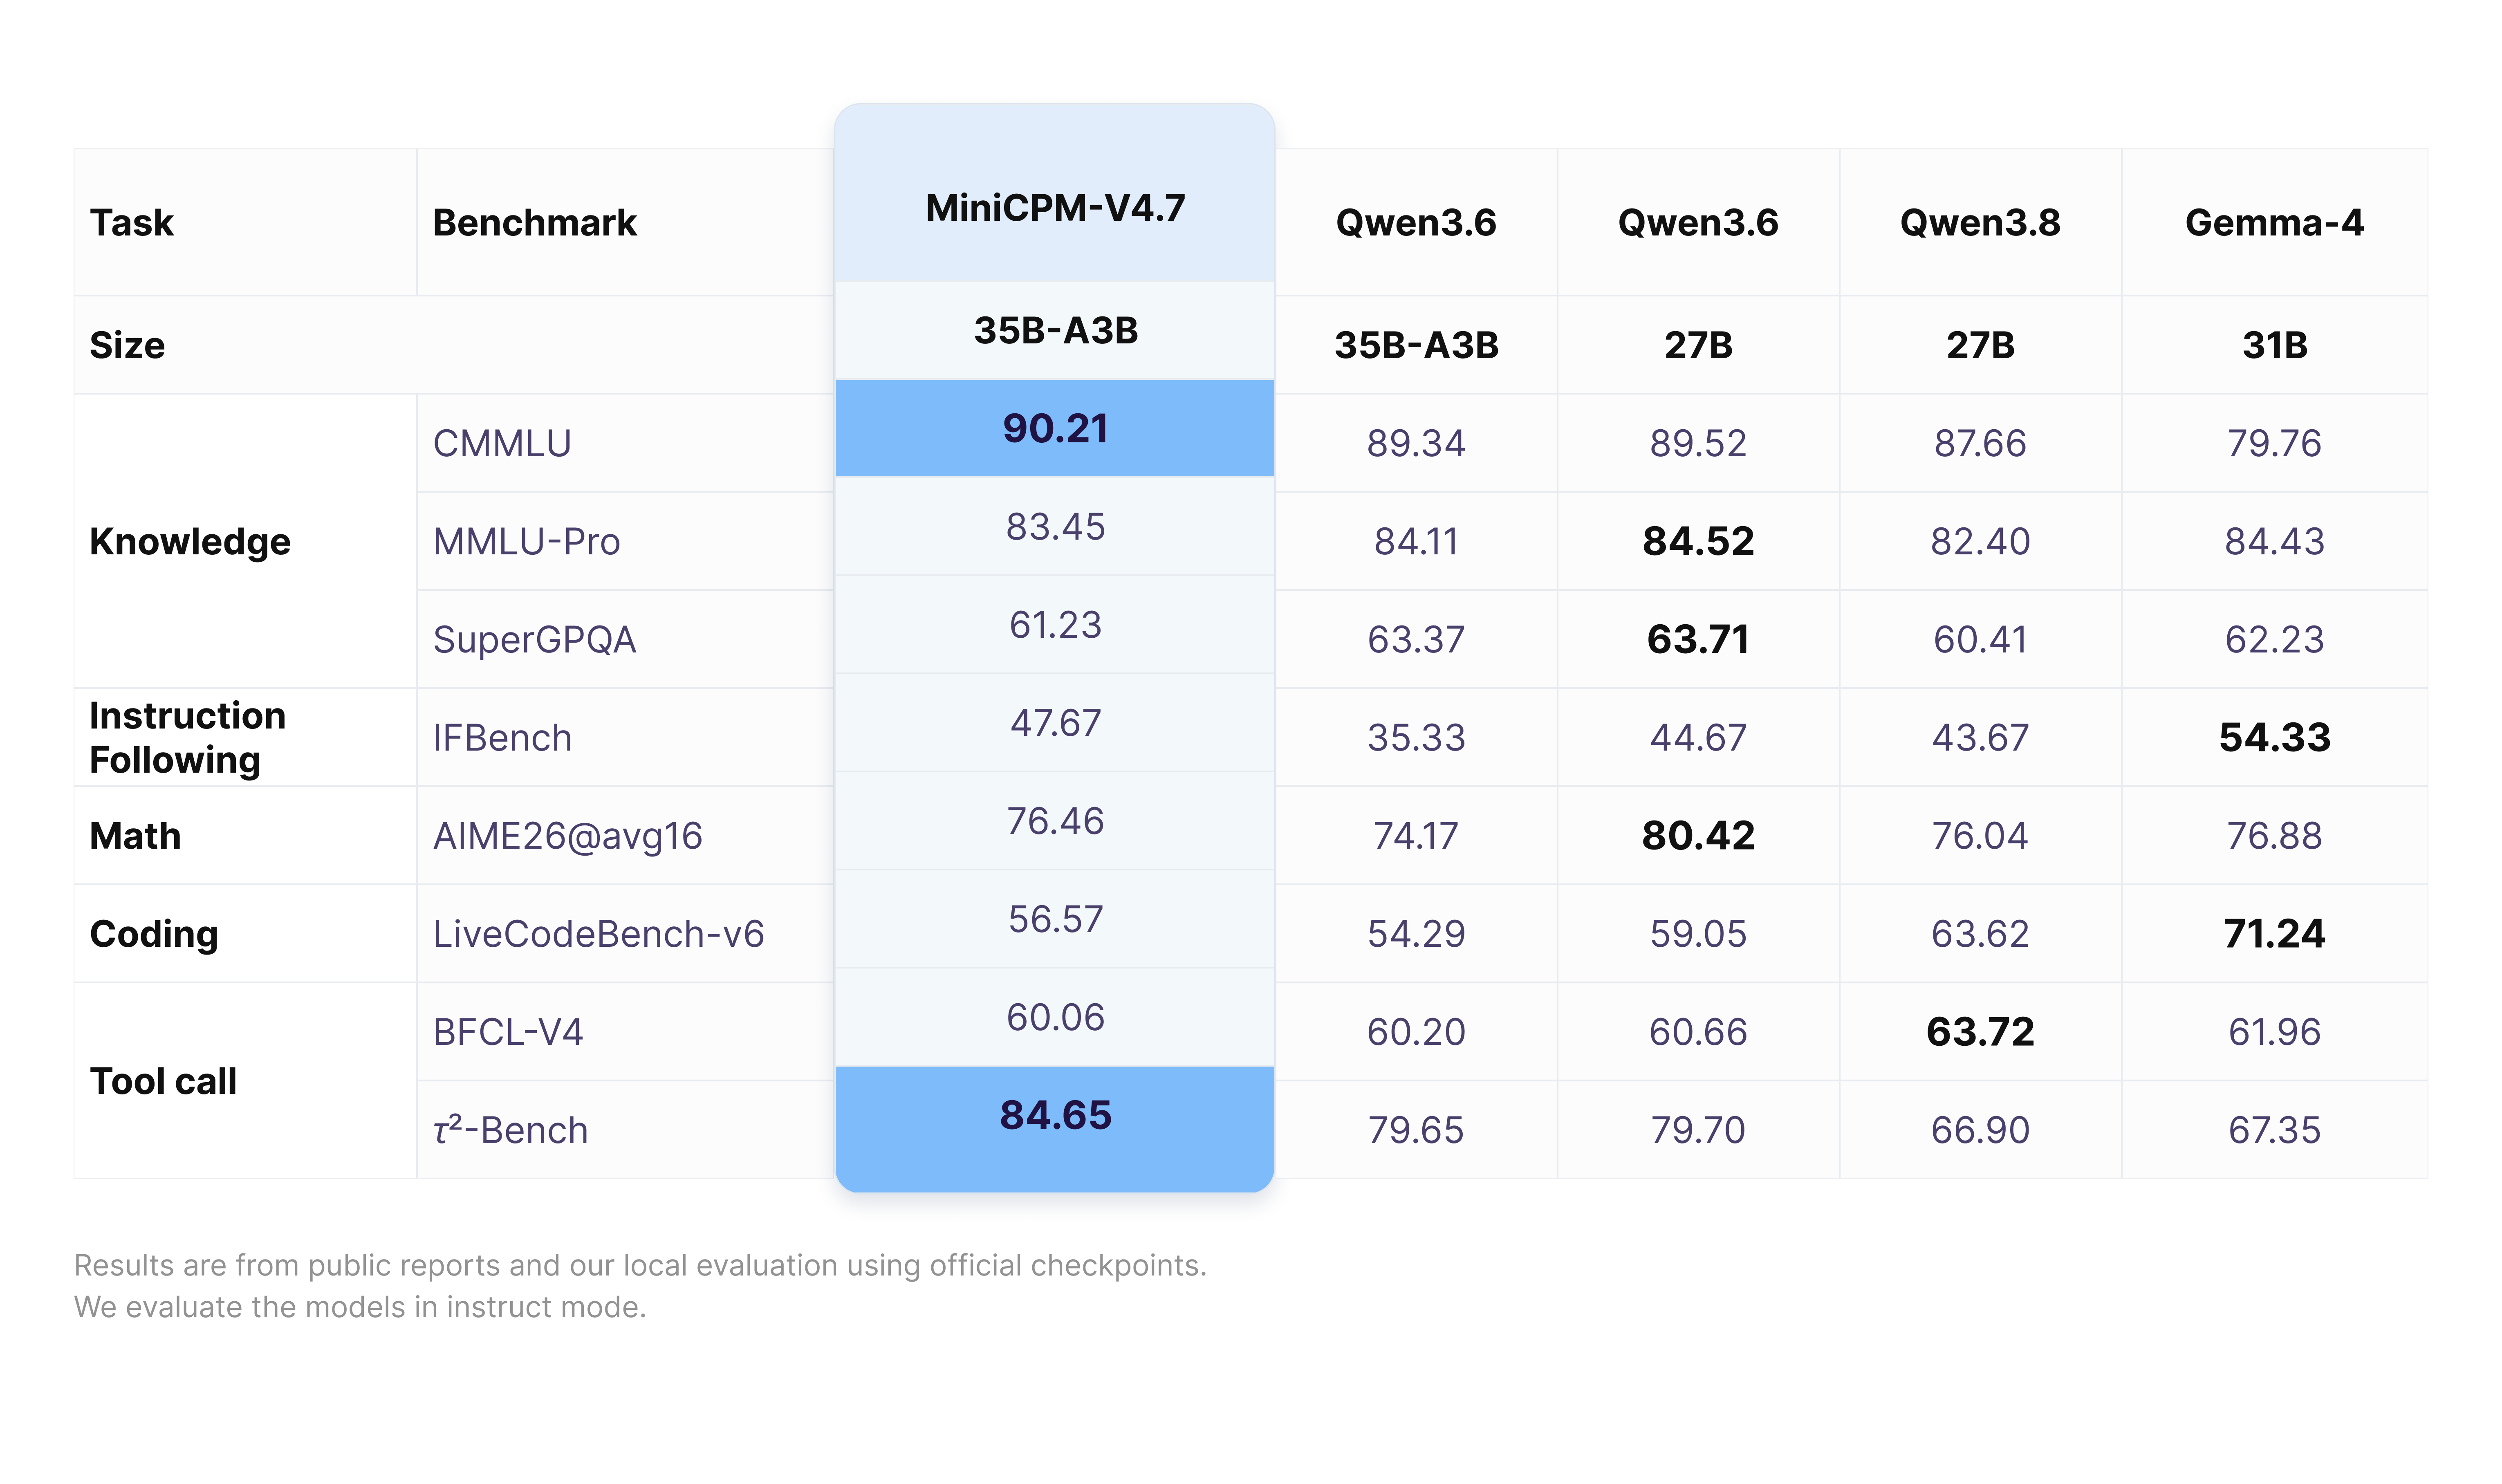
Overall Performance (35B-A3B, Instruct)
Vision-Language
Language
Examples
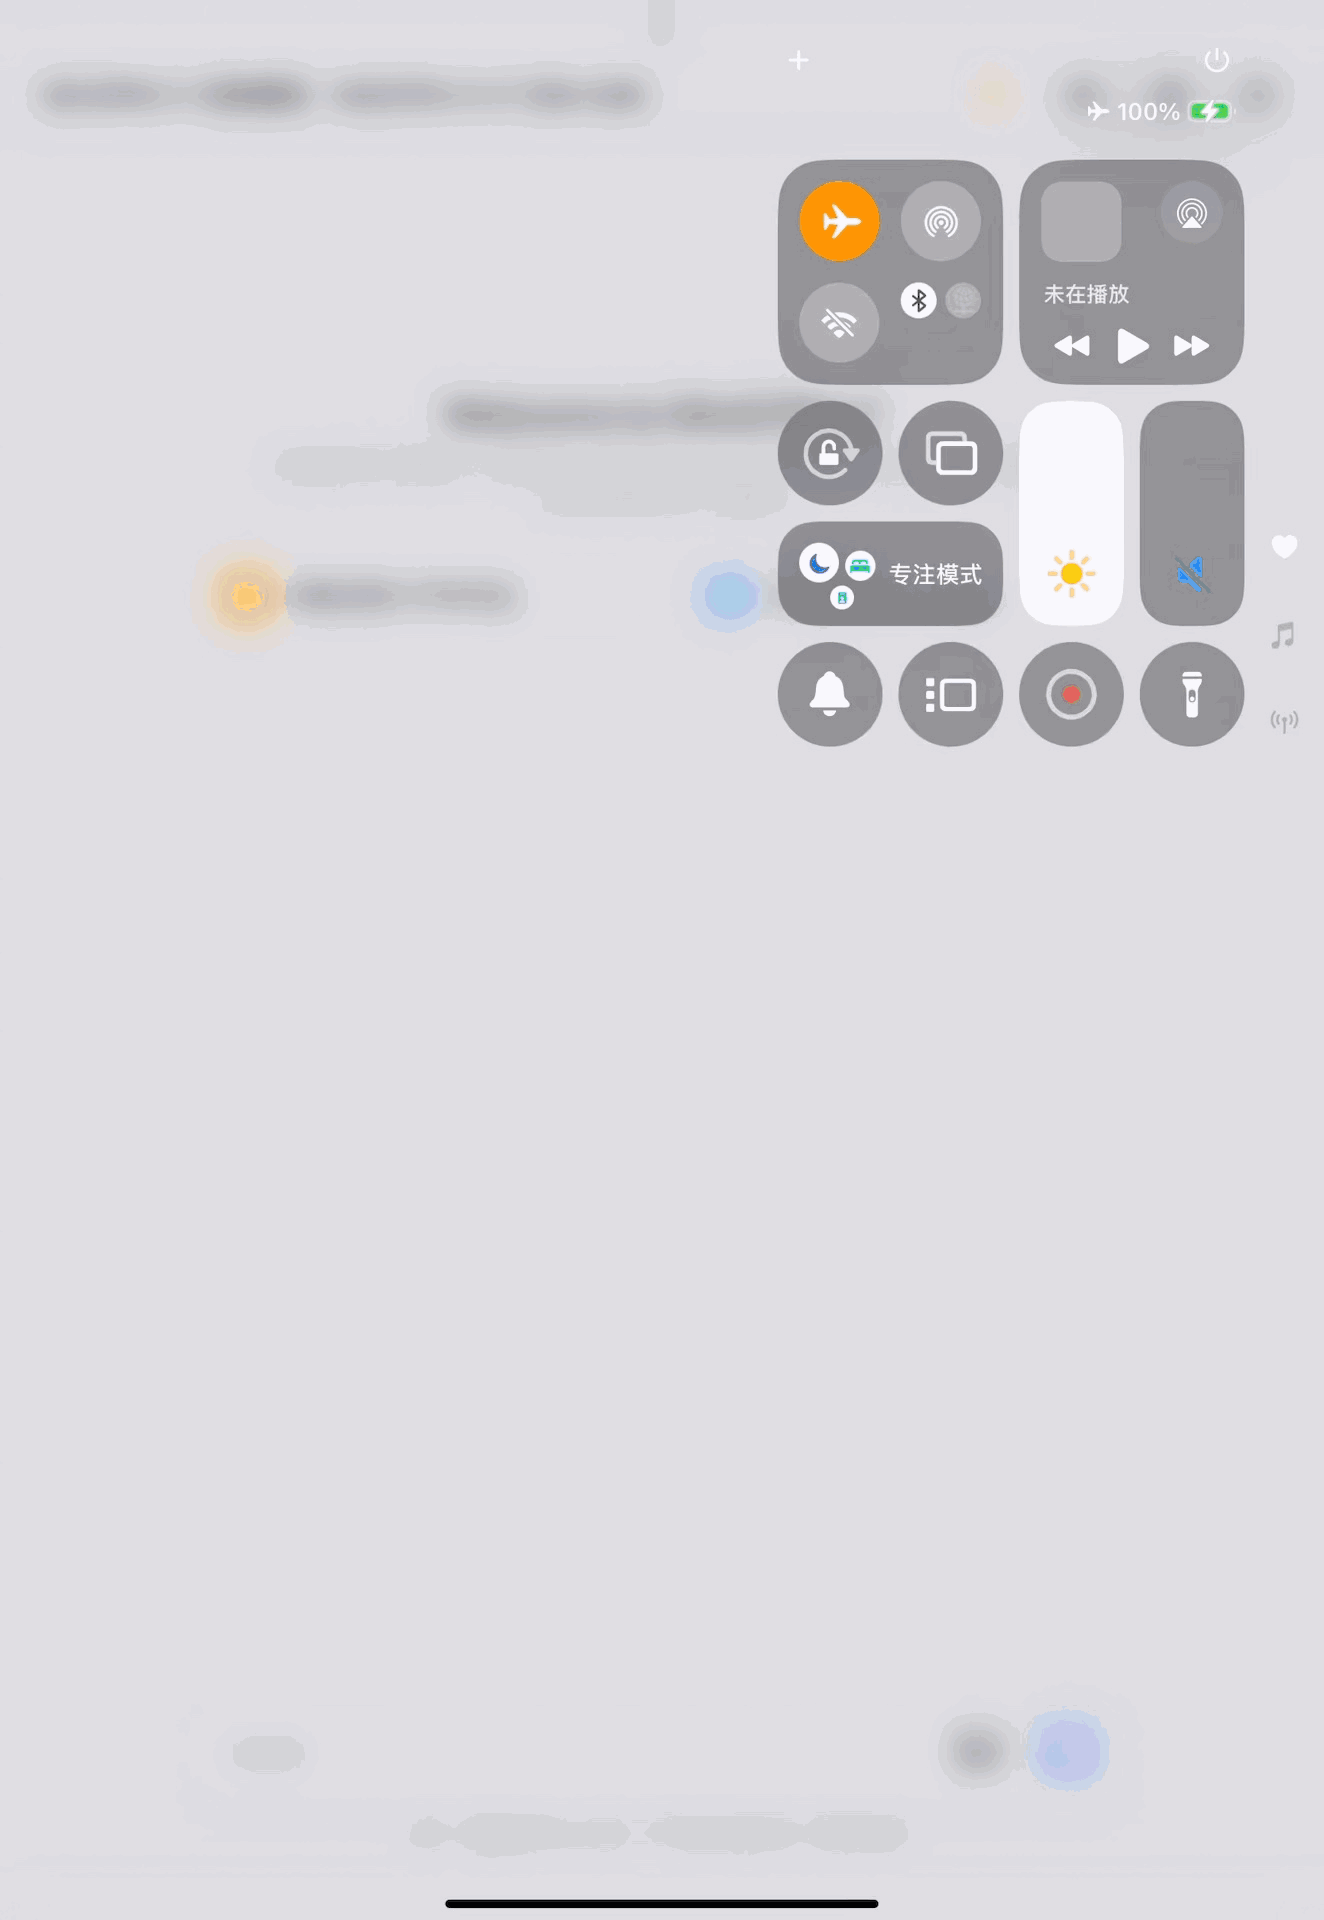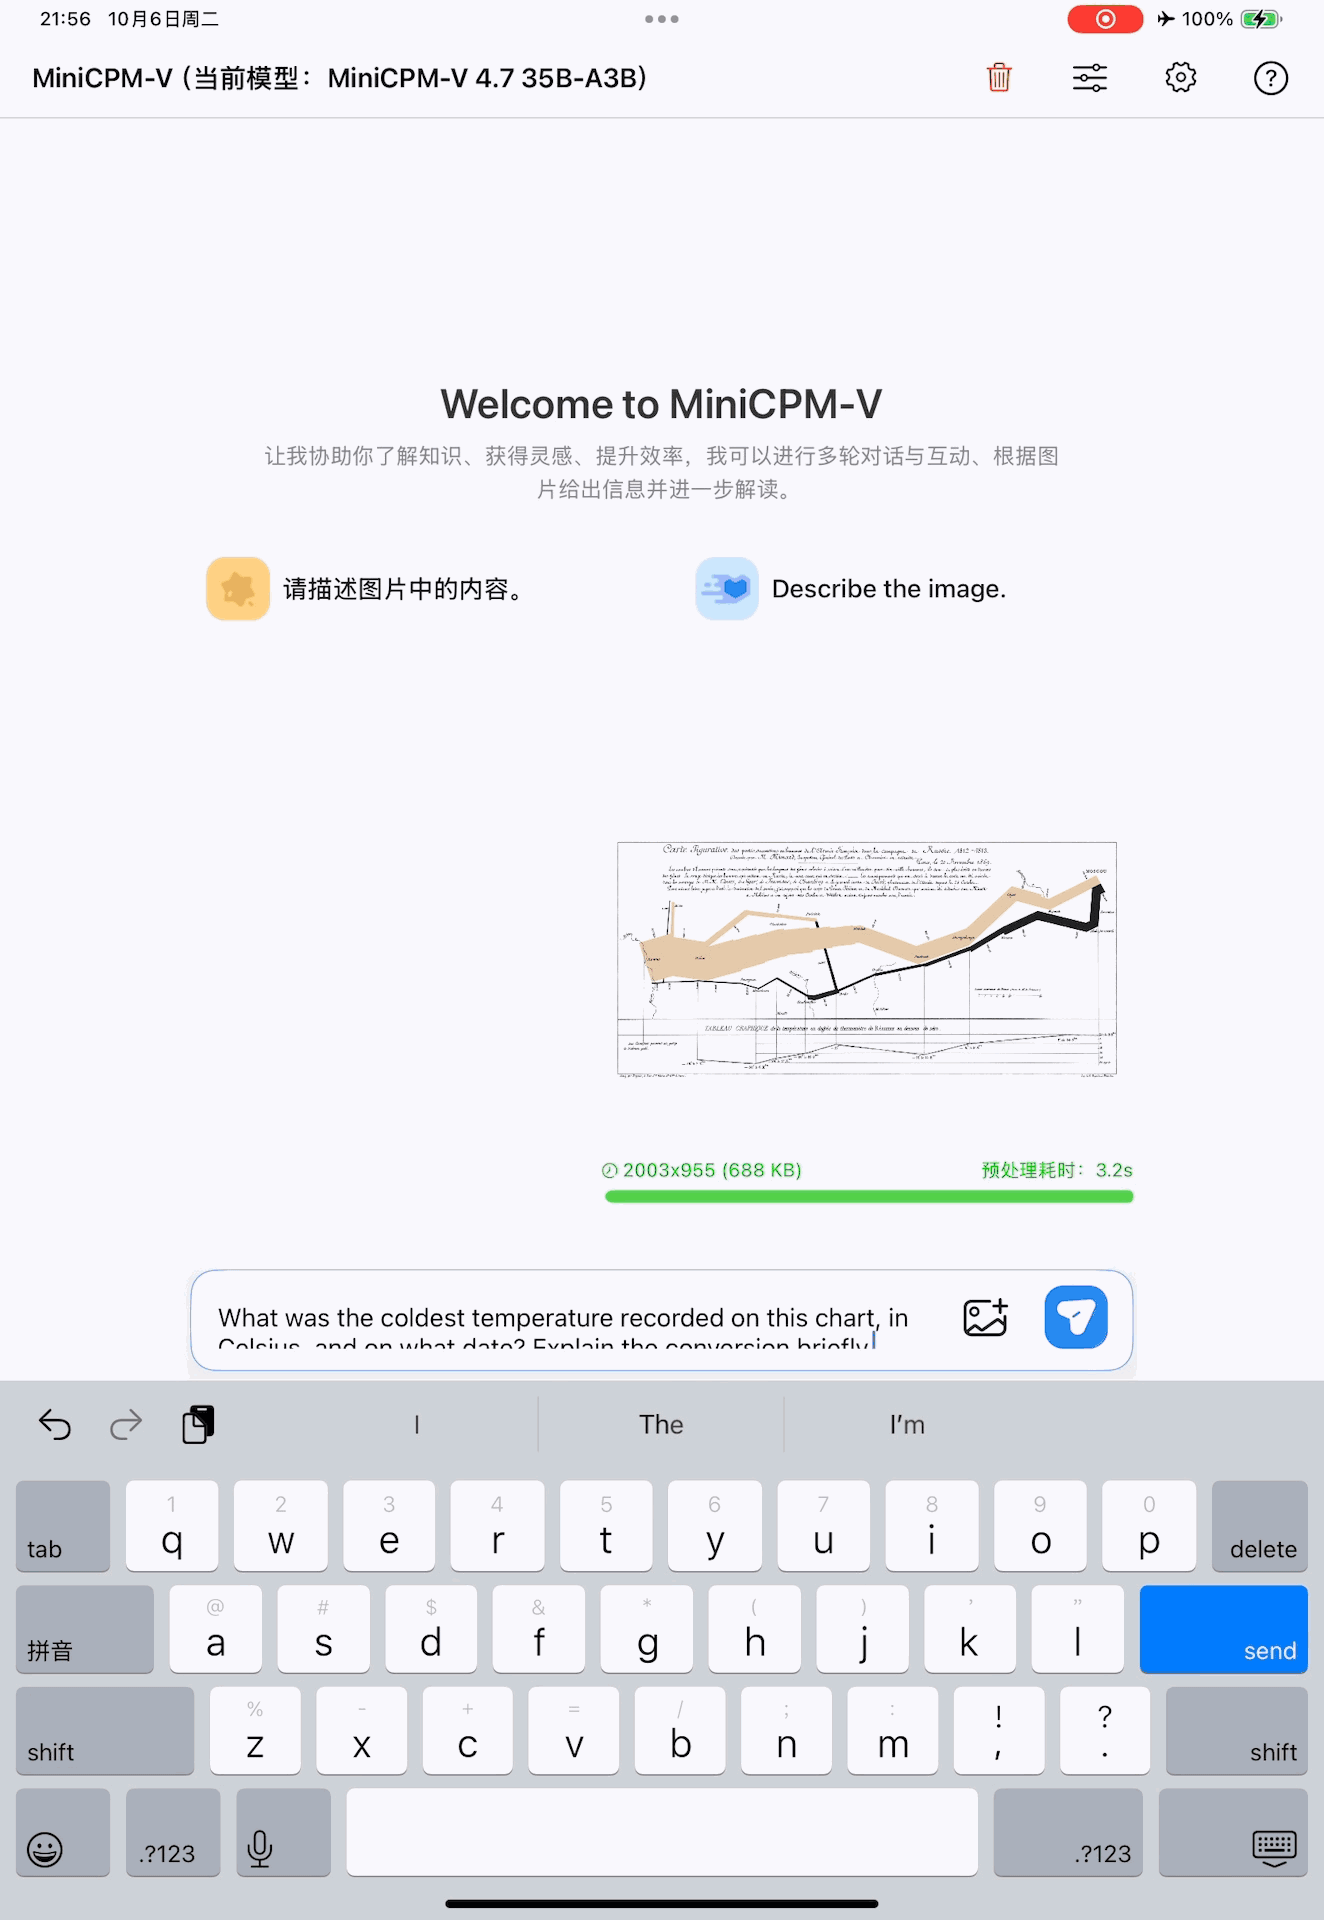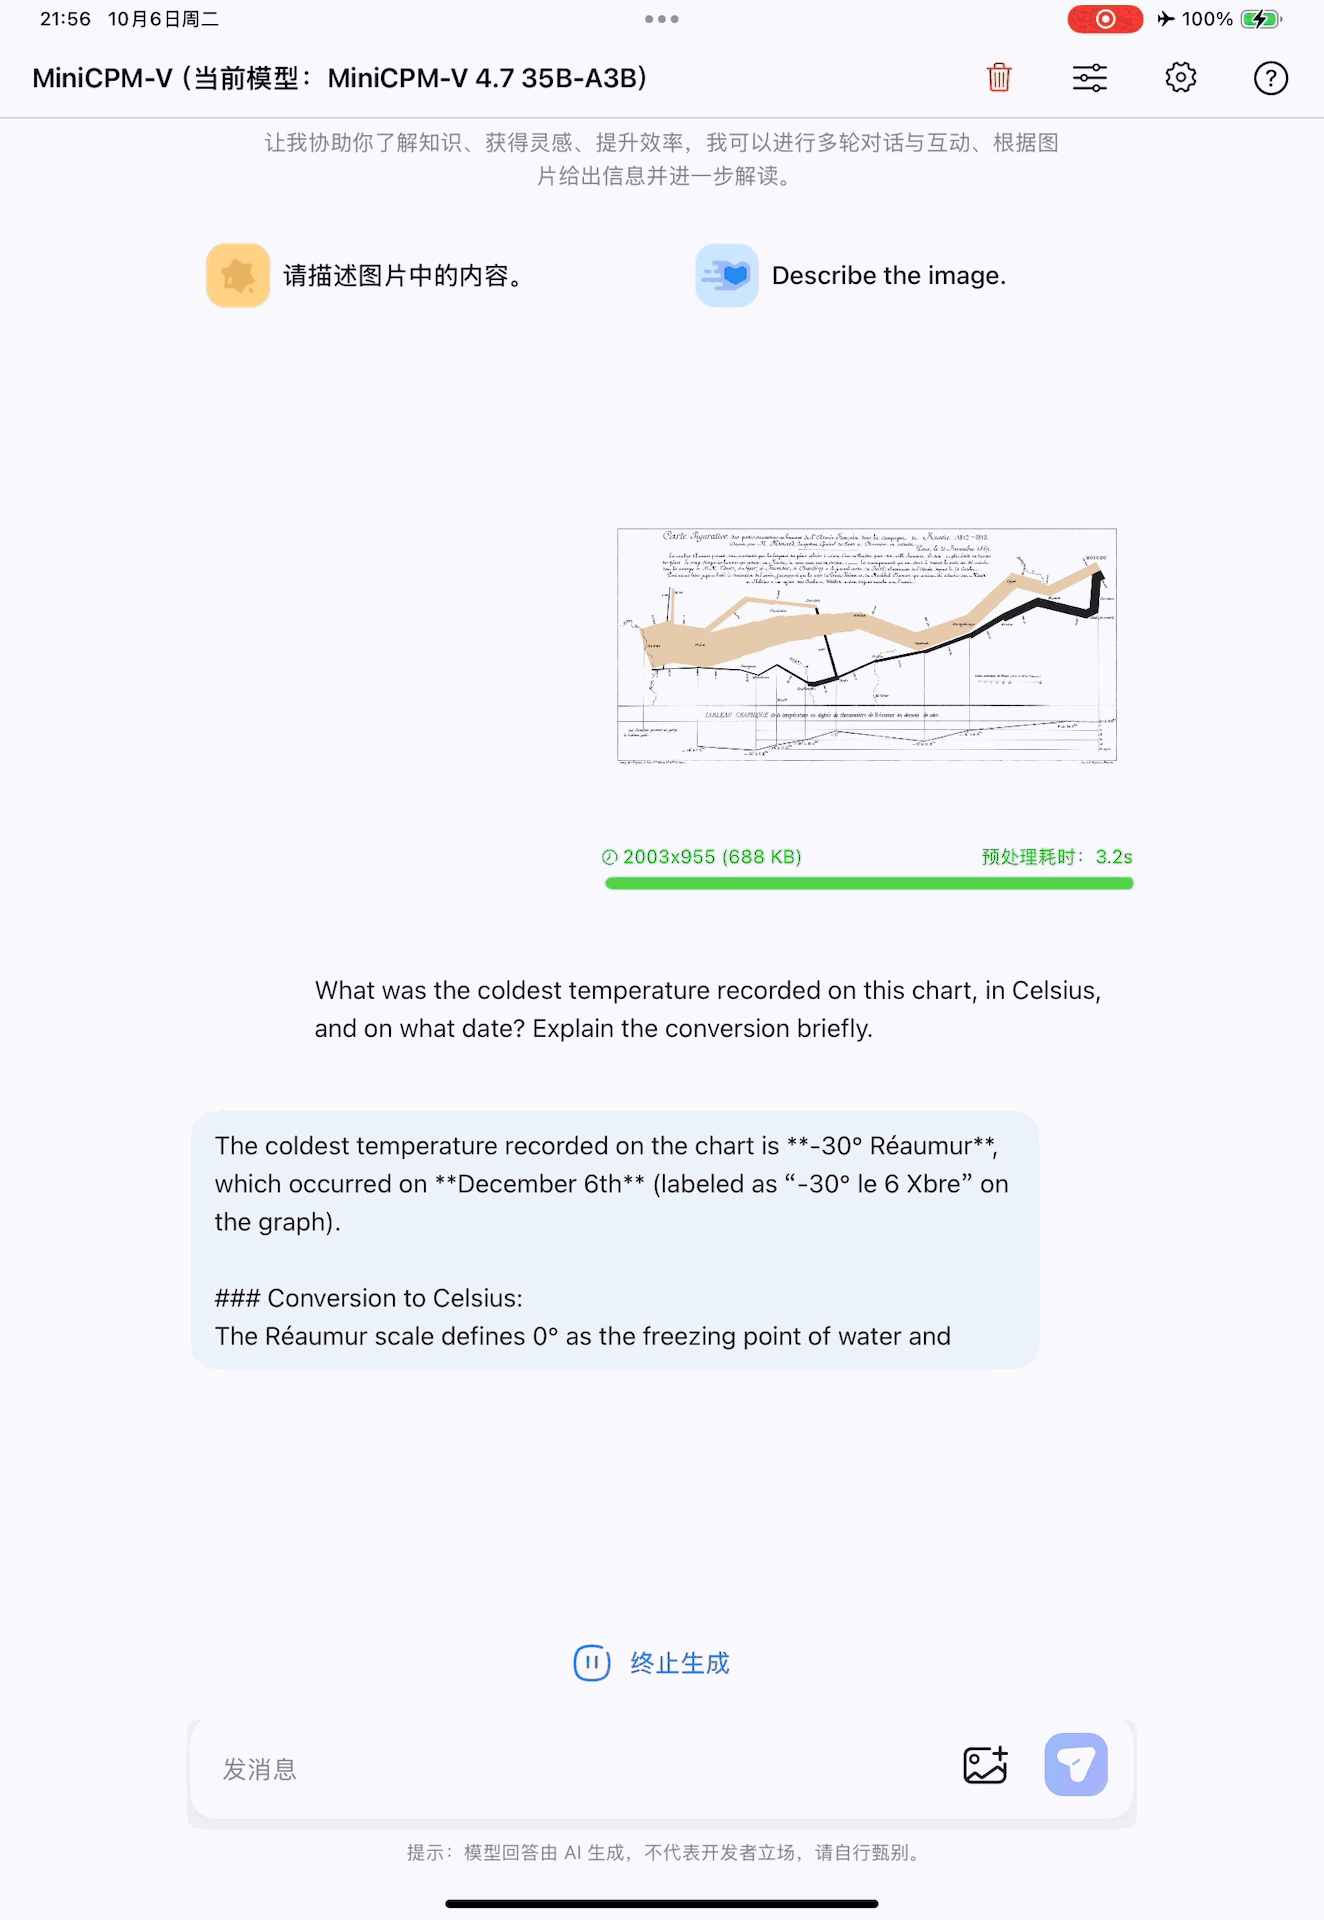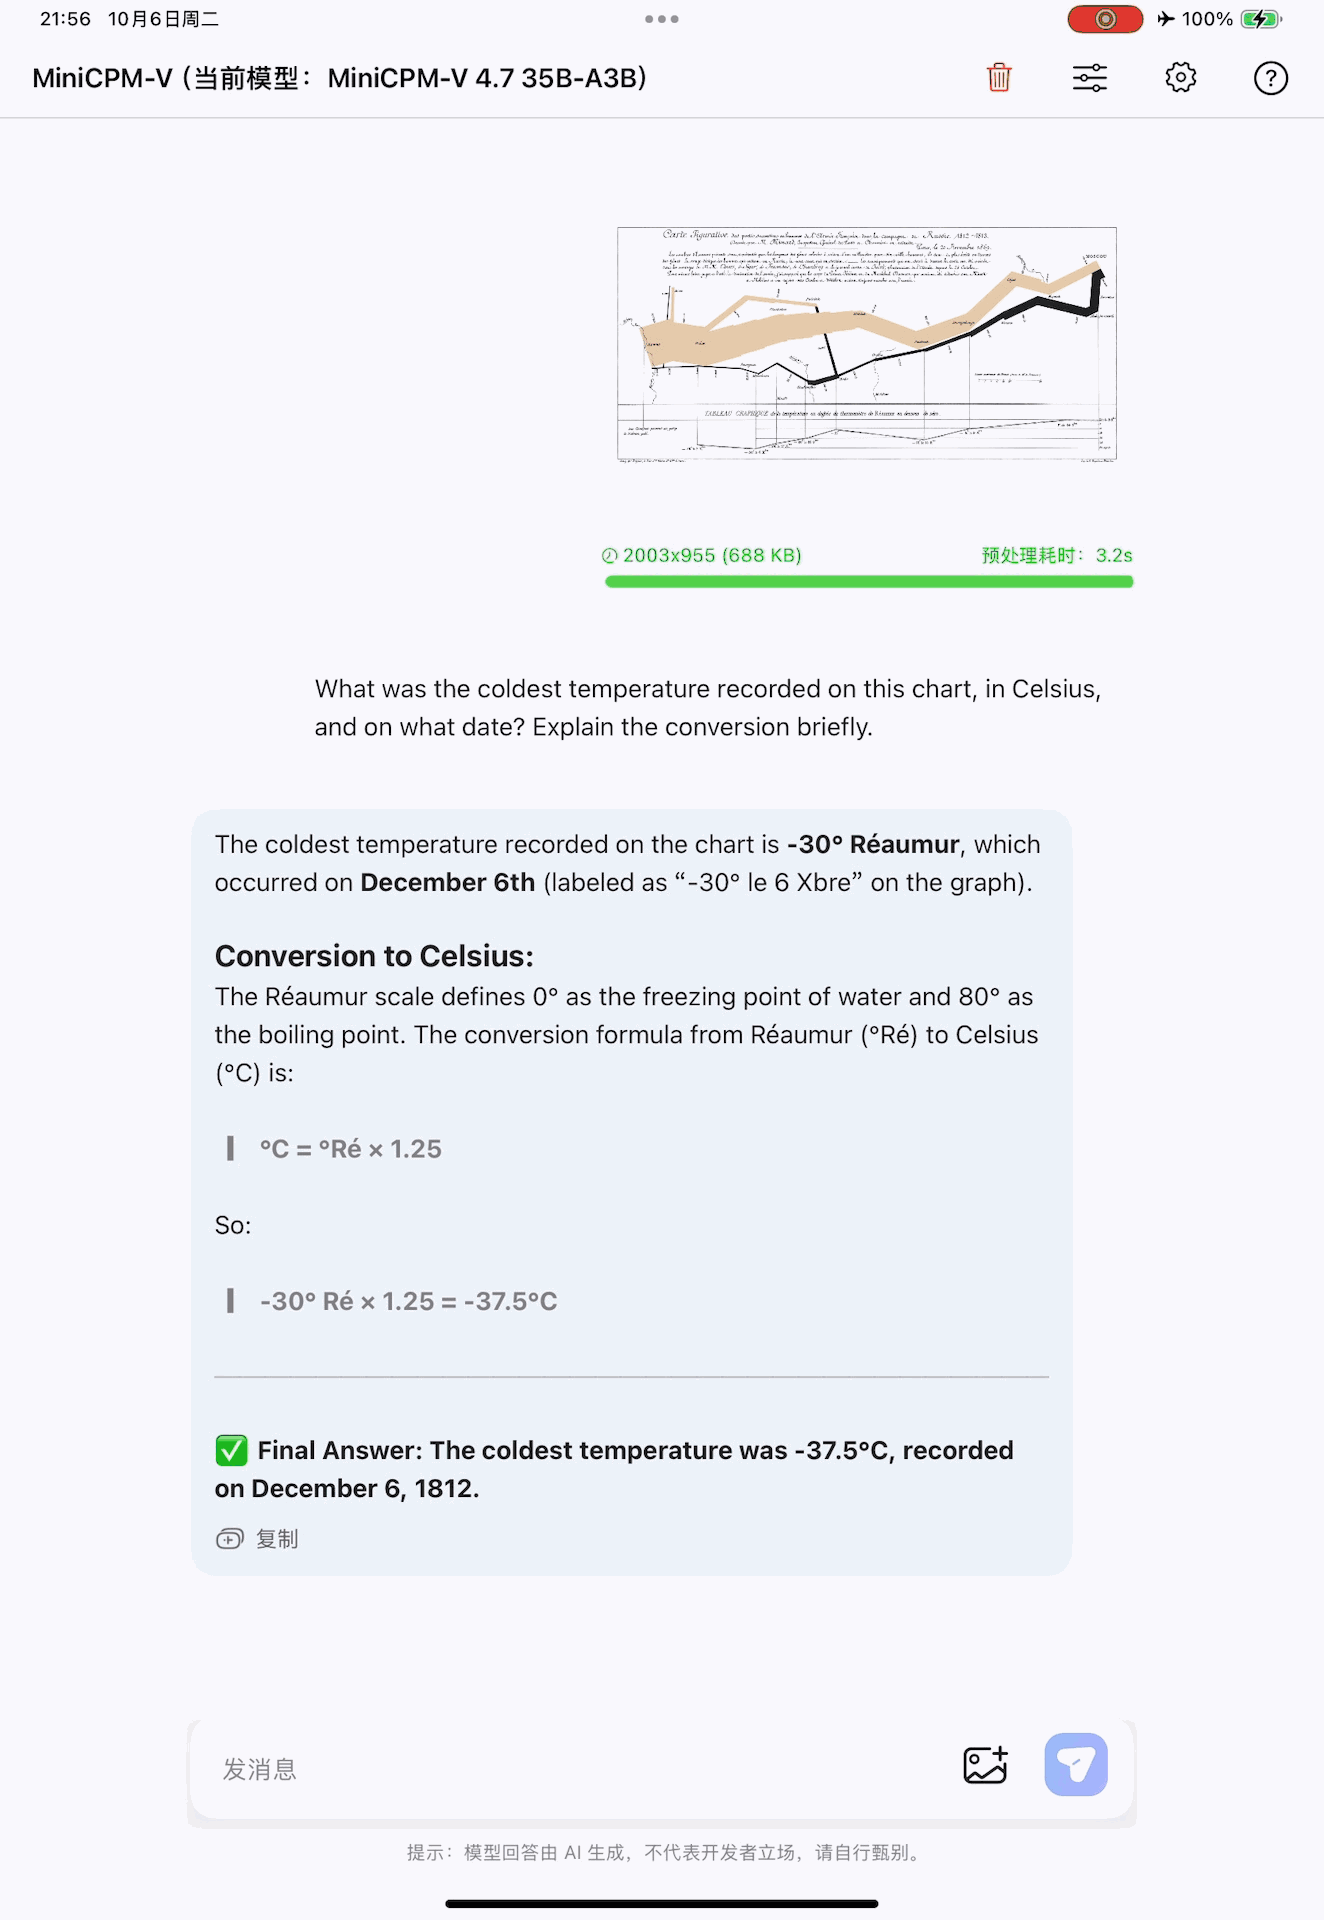
MiniCPM-V 4.7 can run on phones and tablets. The clips below are unedited screen recordings captured directly on the devices.
Usages
Inference with Transformers
Click to expand the Transformers inference examples.
Installation
Note on CUDA compatibility: torchcodec (used for video decoding) may have compatibility issues with certain CUDA versions. For example, torch>=2.11 bundles CUDA 13.1 by default, while environments with CUDA 12.x may encounter errors such as RuntimeError: Could not load libtorchcodec. Two workarounds:
- Replace
torchcodec with PyAV — supports both image and video inference without CUDA version constraints:
- Pin the CUDA version when installing torch to match your environment (e.g. CUDA 12.8):
Load the Model
Image Inference
Video Inference
Advanced Parameters
You can customize image/video processing by passing additional parameters to apply_chat_template:
Note: downsample_mode must be passed to both apply_chat_template (for correct placeholder count) and generate (for the vision encoder). All other parameters only need to be passed to apply_chat_template.
Serving with transformers serve
Hugging Face Transformers includes a lightweight OpenAI-compatible server for quick testing and moderate-load deployment.
Start the server:
Send a request:
Tool calling example:
Recommended Sampling Parameters
We recommend using the following set of sampling parameters for generation in instruct mode: temperature=0.7, top_p=0.95, top_k=100, min_p=0.0, presence_penalty=0, repetition_penalty=1.03.
Speculative decoding (DSpark)
Click to show speculative decoding.
Speculative decoding (DSpark): we also release MiniCPM-V-4.7-35B-A3B-DSpark, a DSpark draft model trained for MiniCPM-V-4.7-35B-A3B.
Inference with OpenVINO™
OpenVINO™ is an open-source toolkit for optimizing and deploying AI inference on Intel CPU/GPU/NPU platforms. OpenVINO provides day-0 support for MiniCPM-V-4.7 on Intel platforms with high-performance inference. See the OpenVINO™ Toolkit to get started. You can install and run the example with this notebook.
On-Device Deployment
MiniCPM-V 4.7 supports deployment on iOS, Android, and HarmonyOS, with day-0 support for Rockchip, Houmo, Intel, AMD, and Arm chip platforms. See the edge deployment repository for the apps and source code.
Inference and Fine-Tuning
For supported inference and training frameworks, see Supported Inference and Training Frameworks and API. The MiniCPM-V 4.7 Cookbook covers deployment, fine-tuning, and quantization workflows.
Task guides
Quantization
Acknowledgements
Click to view acknowledgements.
We would like to thank the following projects:
Model Weights
MiniCPM-V 4.7 is available in the following variants:
Also available on Ollama.