This repository hosts the AWQ (W4A16, AutoAWQ) quantized version of MiniCPM-V 4.7 1B. For the original BF16 weights and the full model card, please refer to openbmb/MiniCPM-V-4.7-1B.
MiniCPM-V 4.7
GitHub · Evaluation · Examples · Usage · Model weights · DSpark
MiniCPM-V 4.7 is the latest model in the MiniCPM-V series, available in a 1B variant. It builds on the family's single-image, multi-image, and video understanding capabilities, combining stronger foundation capabilities with efficient visual encoding and on-device inference. Notable features of MiniCPM-V 4.7 include:
- 🔥 A New Pareto Frontier in Performance and Efficiency.
As model capabilities continue to advance, inference efficiency has become an important measure of a model's value. On resource-constrained devices, delivering the strongest possible capabilities within a limited resource budget calls for higher capability density. The 1B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier for MLLMs. In Instruct mode, the 1B variant continues to improve foundation capabilities over MiniCPM-V 4.6 and substantially outperforms Qwen3.5 0.8B in both overall score and inference efficiency.
- 🚀 Efficient Architecture.
Based on the intra-ViT early compression technique from LLaVA-UHD v4, MiniCPM-V 4.7 compresses visual tokens early within the vision encoder, reducing computation in subsequent encoder layers. It also supports mixed 4x/16x visual token compression, allowing developers to balance visual detail and inference cost across tasks.
- 💻 Broad Platform and Chip Support.
MiniCPM-V 4.7 supports iOS, Android, and HarmonyOS, together with open-source on-device deployment support. It also provides day-0 support for chip platforms from Rockchip, Houmo, Intel, AMD, and Arm, extending deployment options across mobile and local computing devices.
- 🛠️ Developer Friendly.
MiniCPM-V 4.7 supports inference frameworks including SGLang, vLLM, llama.cpp, and Ollama, along with fine-tuning frameworks including SWIFT and LLaMA-Factory. It provides GGUF, BNB, AWQ, and GPTQ quantized variants and adds FP8 quantization support. We also release Self-Replay Fine-Tuning (SRFT), a fine-tuning approach that helps developers extend model capabilities at low cost while reducing forgetting of existing capabilities, making further customization easier.
Get started
Model weights ·
Inference ·
Fine-tuning ·
Live demo ·
Local deployment ·
API ·
Cookbook
Evaluation
Significantly Advancing the Performance–Efficiency Pareto Frontier
The 1B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier. In Instruct mode, 1B substantially outperforms Qwen3.5 0.8B in both overall score and inference efficiency.
Overall Performance (1B, Instruct)
Examples
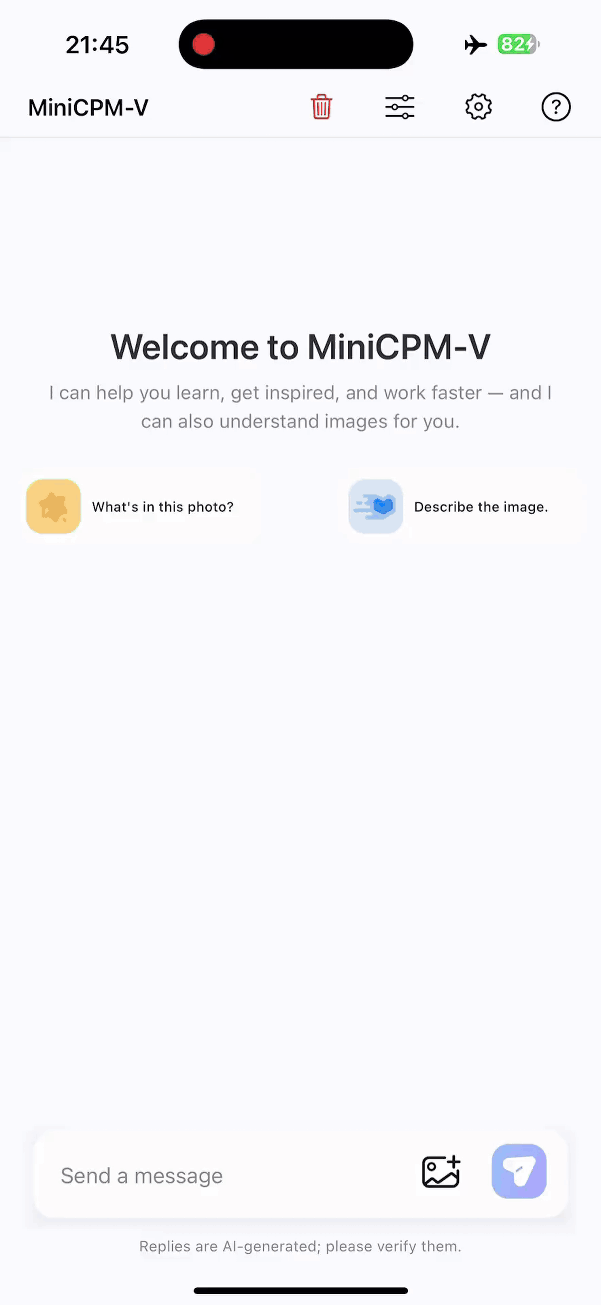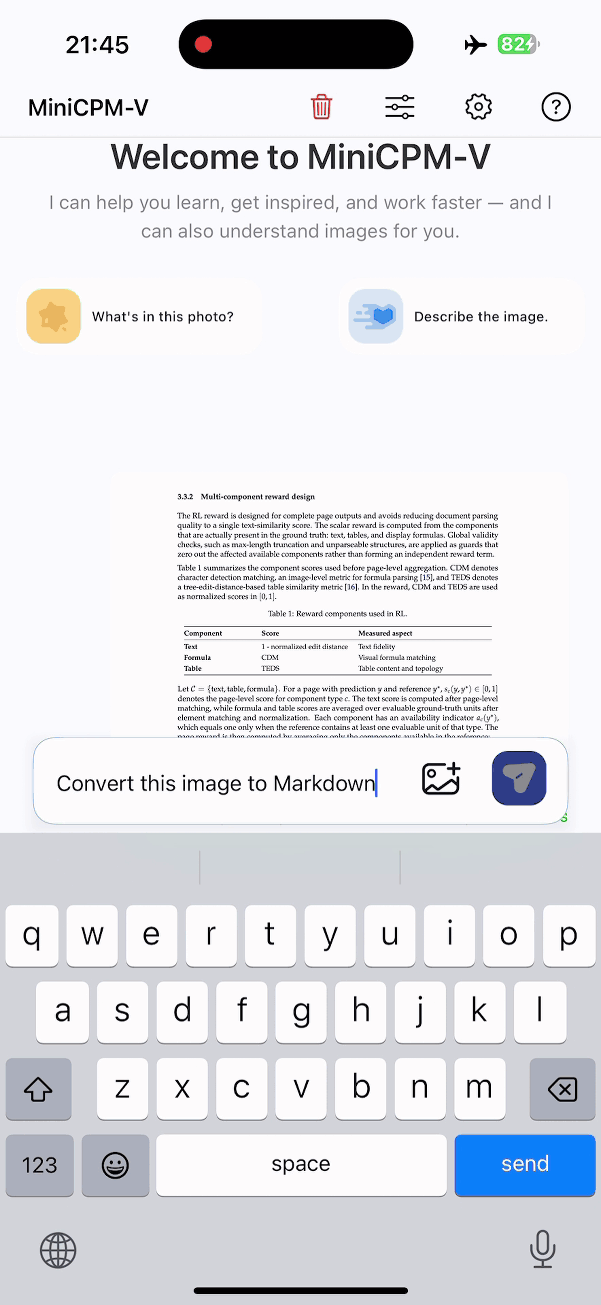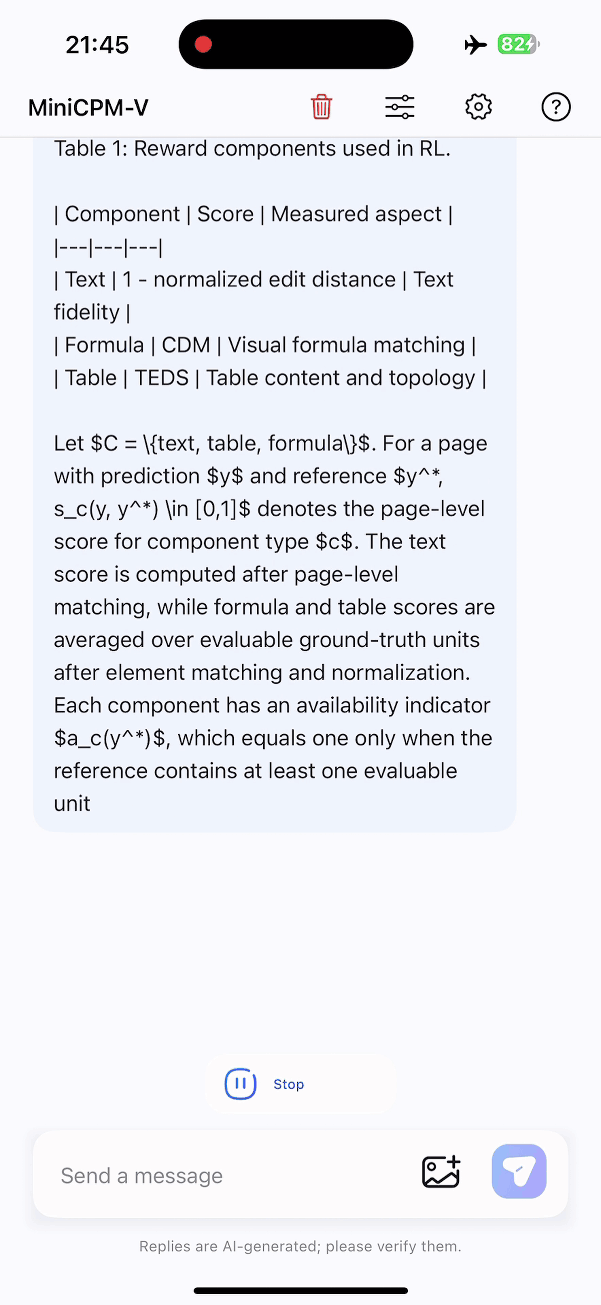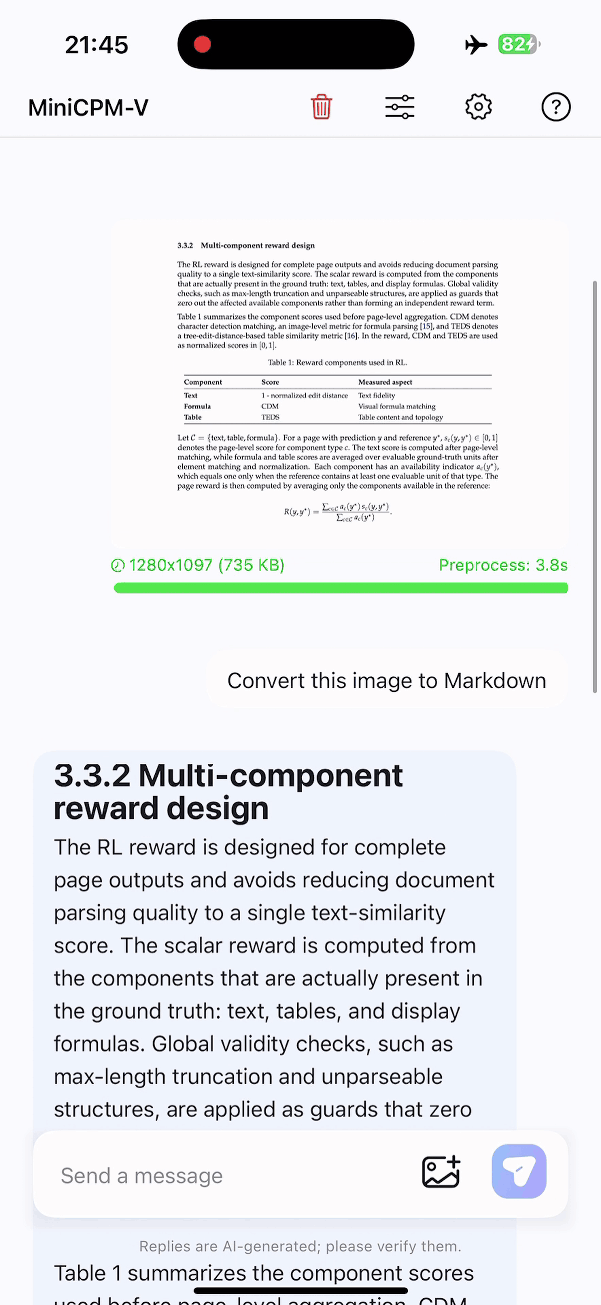
MiniCPM-V 4.7 can run on phones and tablets. The clips below are unedited screen recordings captured directly on the devices.
Usages
Inference with Transformers
Click to expand the Transformers inference examples.
Installation
Note on CUDA compatibility: torchcodec (used for video decoding) may have compatibility issues with certain CUDA versions. For example, torch>=2.11 bundles CUDA 13.1 by default, while environments with CUDA 12.x may encounter errors such as RuntimeError: Could not load libtorchcodec. Two workarounds:
- Replace
torchcodec with PyAV — supports both image and video inference without CUDA version constraints:
- Pin the CUDA version when installing torch to match your environment (e.g. CUDA 12.8):
Load the Model
Image Inference
Video Inference
Advanced Parameters
You can customize image/video processing by passing additional parameters to apply_chat_template:
Note: downsample_mode must be passed to both apply_chat_template (for correct placeholder count) and generate (for the vision encoder). All other parameters only need to be passed to apply_chat_template.
Serving with transformers serve
Hugging Face Transformers includes a lightweight OpenAI-compatible server for quick testing and moderate-load deployment.
Start the server:
Send a request:
Tool calling example:
Recommended Sampling Parameters
We recommend using the following set of sampling parameters for generation in instruct mode: temperature=0.7, top_p=0.95, top_k=100, min_p=0.0, presence_penalty=0, repetition_penalty=1.03.
Speculative decoding (DSpark)
Click to show speculative decoding.
Speculative decoding (DSpark): we also release MiniCPM-V-4.7-1B-DSpark, a DSpark draft model trained for MiniCPM-V-4.7-1B.
Inference with OpenVINO™
OpenVINO™ is an open-source toolkit for optimizing and deploying AI inference on Intel CPU/GPU/NPU platforms. OpenVINO provides day-0 support for MiniCPM-V-4.7 on Intel platforms with high-performance inference. See the OpenVINO™ Toolkit to get started. You can install and run the example with this notebook.
On-Device Deployment
MiniCPM-V 4.7 supports deployment on iOS, Android, and HarmonyOS, with day-0 support for Rockchip, Houmo, Intel, AMD, and Arm chip platforms. See the edge deployment repository for the apps and source code.
Inference and Fine-Tuning
For supported inference and training frameworks, see Supported Inference and Training Frameworks and API. The MiniCPM-V 4.7 Cookbook covers deployment, fine-tuning, and quantization workflows.
Task guides
Quantization
Acknowledgements
Click to view acknowledgements.
We would like to thank the following projects:
Model Weights
MiniCPM-V 4.7 is available in the following variants:
Also available on Ollama.