Qwen3-TTS
Overview
Introduction
Qwen3-TTS covers 10 major languages (Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, and Italian) as well as multiple dialectal voice profiles to meet global application needs. In addition, the models feature strong contextual understanding, enabling adaptive control of tone, speaking rate, and emotional expression based on instructions and text semantics, and they show markedly improved robustness to noisy input text. Key features:
- Powerful Speech Representation: Powered by the self-developed Qwen3-TTS-Tokenizer-12Hz, it achieves efficient acoustic compression and high-dimensional semantic modeling of speech signals. It fully preserves paralinguistic information and acoustic environmental features, enabling high-speed, high-fidelity speech reconstruction through a lightweight non-DiT architecture.
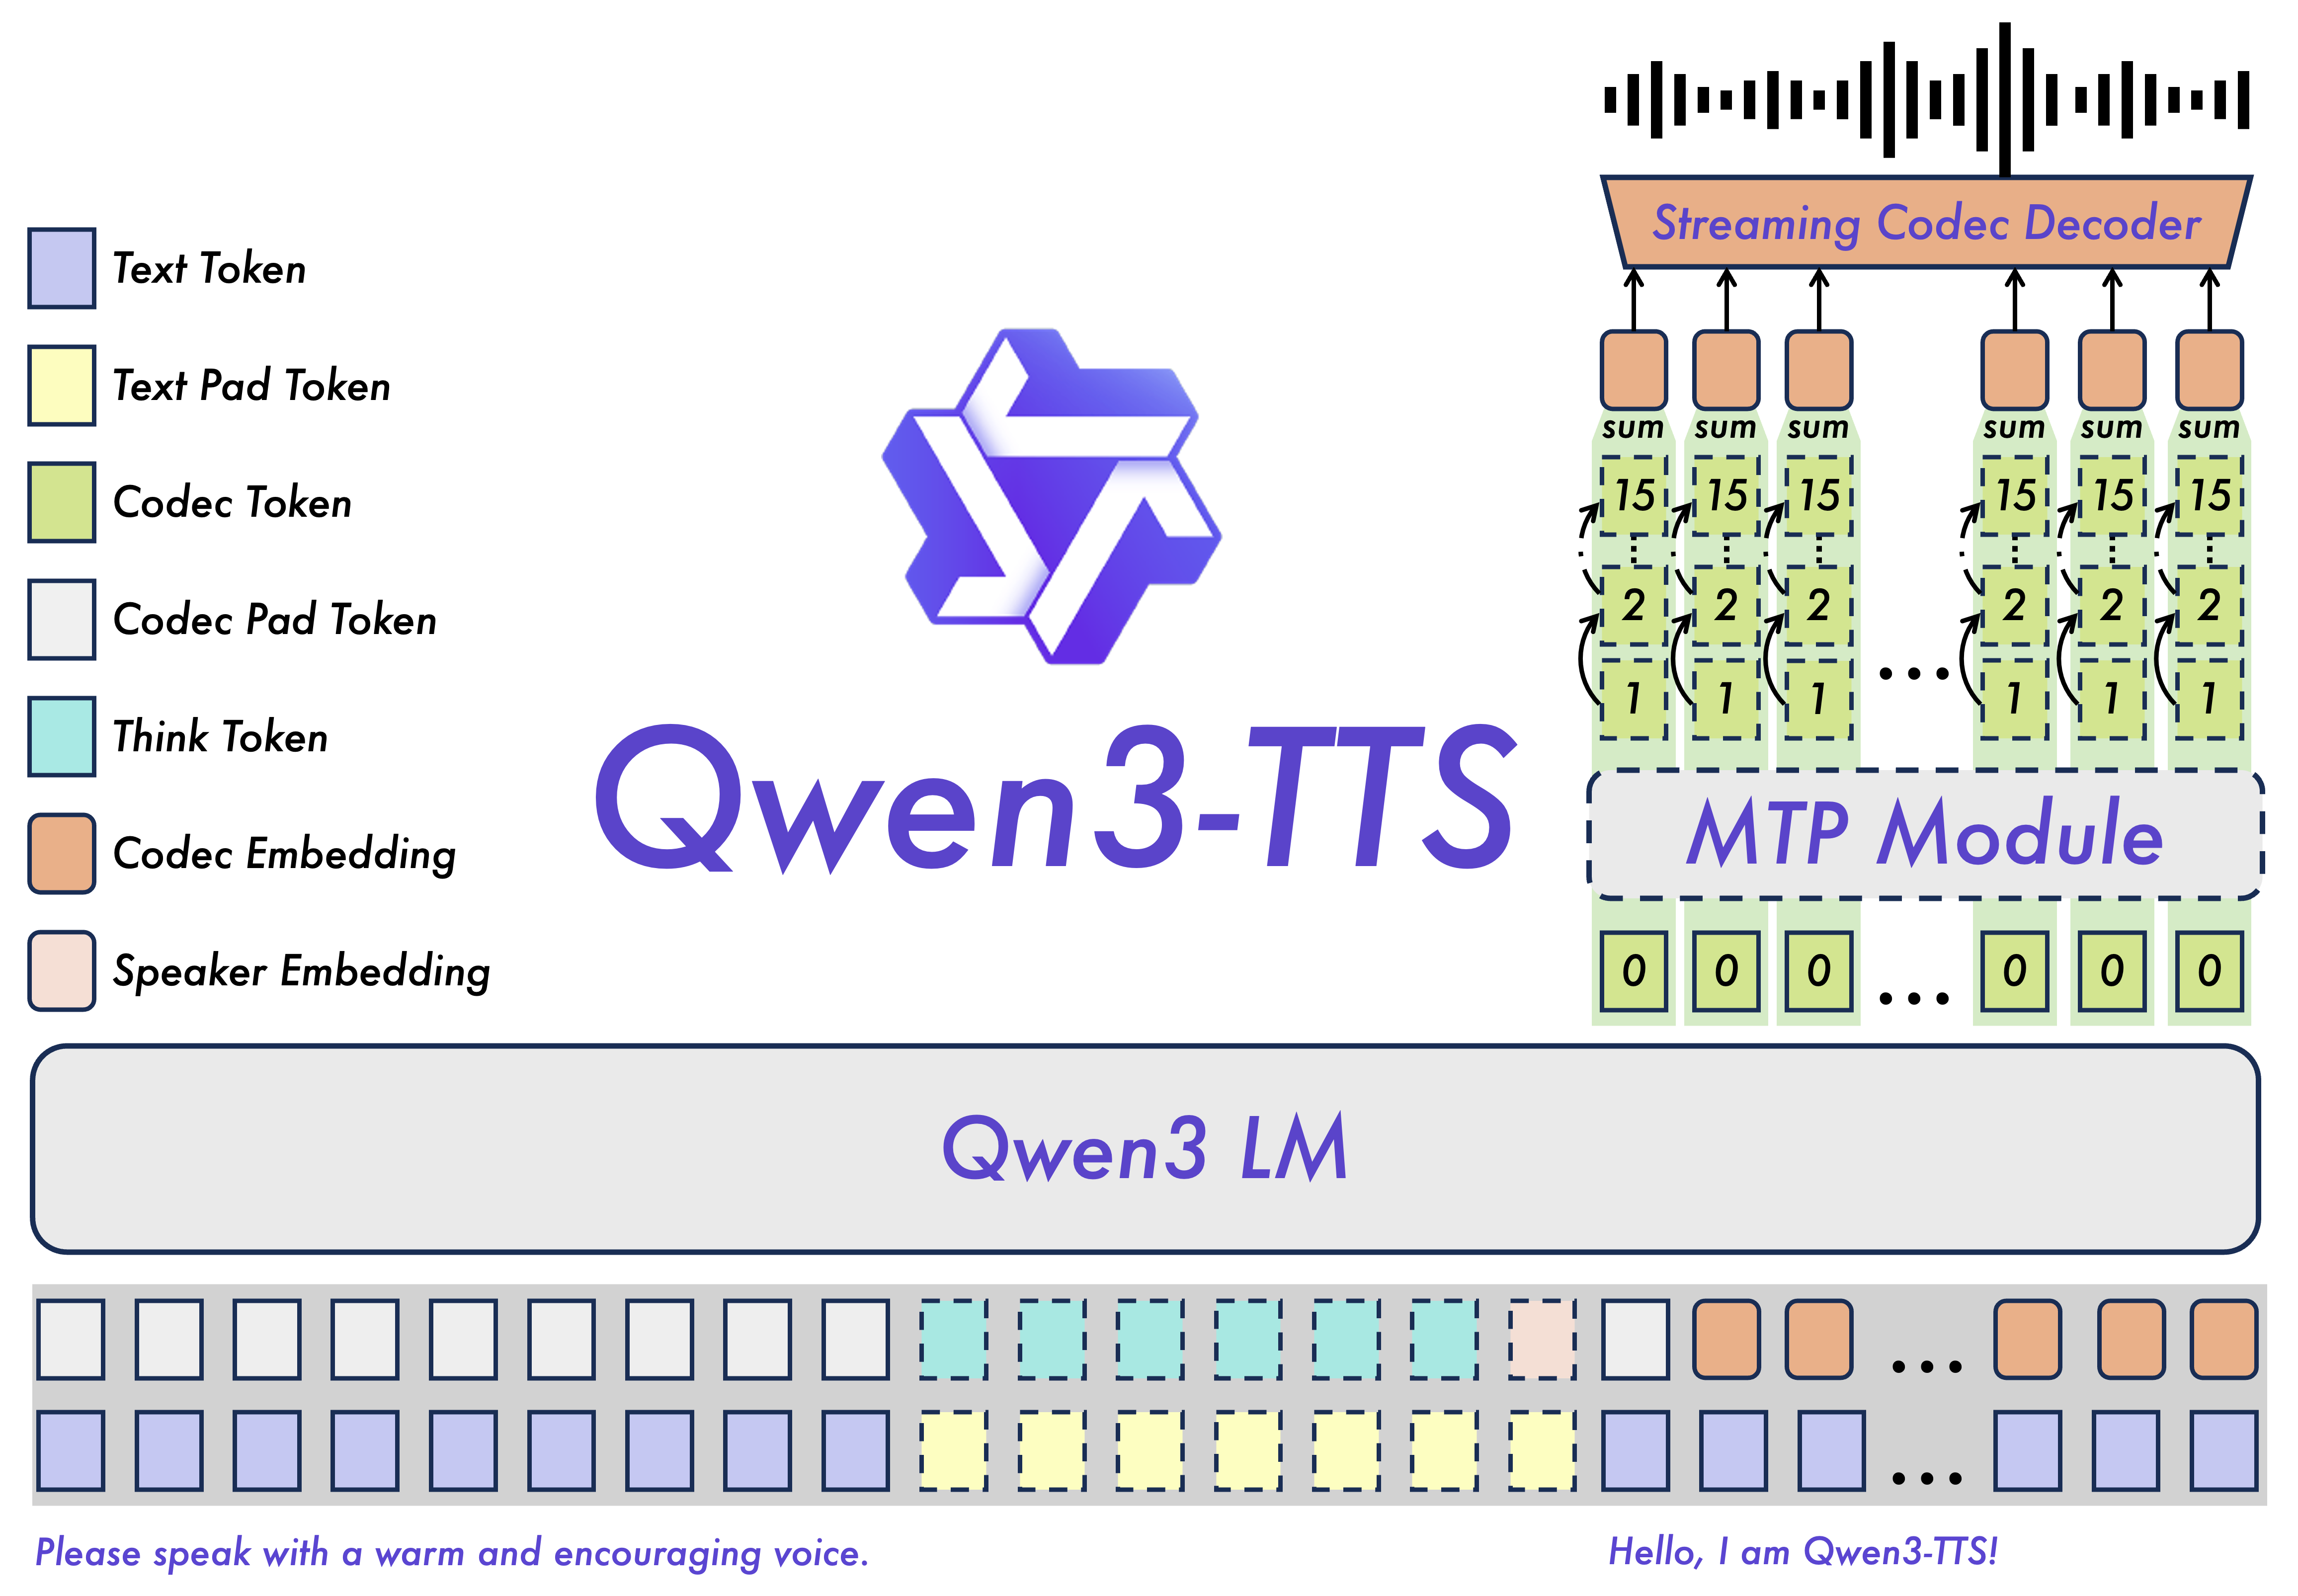
- Universal End-to-End Architecture: Utilizing a discrete multi-codebook LM architecture, it realizes full-information end-to-end speech modeling. This completely bypasses the information bottlenecks and cascading errors inherent in traditional LM+DiT schemes, significantly enhancing the model’s versatility, generation efficiency, and performance ceiling.
- Extreme Low-Latency Streaming Generation: Based on the innovative Dual-Track hybrid streaming generation architecture, a single model supports both streaming and non-streaming generation. It can output the first audio packet immediately after a single character is input, with end-to-end synthesis latency as low as 97ms, meeting the rigorous demands of real-time interactive scenarios.
- Intelligent Text Understanding and Voice Control: Supports speech generation driven by natural language instructions, allowing for flexible control over multi-dimensional acoustic attributes such as timbre, emotion, and prosody. By deeply integrating text semantic understanding, the model adaptively adjusts tone, rhythm, and emotional expression, achieving lifelike “what you imagine is what you hear” output.
Model Architecture
Released Models Description and Download
Below is an introduction and download information for the Qwen3-TTS models that have already been released. Other models mentioned in the technical report will be released in the near future. Please select and download the model that fits your needs.
During model loading in the qwen-tts package or vLLM, model weights will be automatically downloaded based on the model name. However, if your runtime environment is not conducive to downloading weights during execution, you can refer to the following commands to manually download the model weights to a local directory:
Quickstart
Environment Setup
The easiest way to quickly use Qwen3-TTS is to install the qwen-tts Python package from PyPI. This will pull in the required runtime dependencies and allow you to load any released Qwen3-TTS model. We recommend using a fresh, isolated environment to avoid dependency conflicts with existing packages. You can create a clean Python 3.12 environment like this:
then run:
If you want to develop or modify the code locally, install from source in editable mode.
Additionally, we recommend using FlashAttention 2 to reduce GPU memory usage.
If your machine has less than 96GB of RAM and lots of CPU cores, run:
Also, you should have hardware that is compatible with FlashAttention 2. Read more about it in the official documentation of the FlashAttention repository. FlashAttention 2 can only be used when a model is loaded in torch.float16 or torch.bfloat16.
Python Package Usage
After installation, you can import Qwen3TTSModel to run custom voice TTS, voice design, and voice clone. The model weights can be specified either as a Hugging Face model id (recommended) or as a local directory path you downloaded. For all the generate_* functions below, besides the parameters shown and explicitly documented, you can also pass generation kwargs supported by Hugging Face Transformers model.generate, e.g., max_new_tokens, top_p, etc.
Custom Voice Generate
For custom voice models (Qwen3-TTS-12Hz-1.7B/0.6B-CustomVoice), you just need to call generate_custom_voice, passing a single string or a batch list, along with language, speaker, and optional instruct. You can also call model.get_supported_speakers() and model.get_supported_languages() to see which speakers and languages the current model supports.
For Qwen3-TTS-12Hz-1.7B/0.6B-CustomVoice models, the supported speaker list and speaker descriptions are provided below. We recommend using each speaker’s native language for the best quality. Of course, each speaker can speak any language supported by the model.
Voice Design
For the voice design model (Qwen3-TTS-12Hz-1.7B-VoiceDesign), you can use generate_voice_design to provide the target text and a natural-language instruct description.
Voice Clone
For the voice clone model (Qwen3-TTS-12Hz-1.7B/0.6B-Base), to clone a voice and synthesize new content, you just need to provide a reference audio clip (ref_audio) along with its transcript (ref_text). ref_audio can be a local file path, a URL, a base64 string, or a (numpy_array, sample_rate) tuple. If you set x_vector_only_mode=True, only the speaker embedding is used so ref_text is not required, but cloning quality may be reduced.
If you need to reuse the same reference prompt across multiple generations (to avoid recomputing prompt features), build it once with create_voice_clone_prompt and pass it via voice_clone_prompt.
For more examples of reusable voice clone prompts, batch cloning, and batch inference, please refer to the example codes. With those examples and the generate_voice_clone function description, you can explore more advanced usage patterns.
Voice Design then Clone
If you want a designed voice that you can reuse like a cloned speaker, a practical workflow is: (1) use the VoiceDesign model to synthesize a short reference clip that matches your target persona, (2) feed that clip into create_voice_clone_prompt to build a reusable prompt, and then (3) call generate_voice_clone with voice_clone_prompt to generate new content without re-extracting features every time. This is especially useful when you want a consistent character voice across many lines.
Tokenizer Encode and Decode
If you only want to encode and decode audio for transport or training and so on, Qwen3TTSTokenizer supports encode/decode with paths, URLs, numpy waveforms, and dict/list payloads, for example:
For more tokenizer examples (including different input formats and batch usage), please refer to the example codes. With those examples and the description for Qwen3TTSTokenizer, you can explore more advanced usage patterns.
Launch Local Web UI Demo
To launch the Qwen3-TTS web ui demo, simply install the qwen-tts package and run qwen-tts-demo. Use the command below for help:
To launch the demo, you can use the following commands:
And then open http://<your-ip>:8000, or access it via port forwarding in tools like VS Code.
Base Model HTTPS Notes
To avoid browser microphone permission issues after deploying the server, for Base model deployments, it is recommended/required to run the gradio service over HTTPS (especially when accessed remotely or behind modern browsers/gateways). Use --ssl-certfile and --ssl-keyfile to enable HTTPS. First we need to generate a private key and a self-signed cert (valid for 365 days):
Then run the demo with HTTPS:
And open https://<your-ip>:8000 to experience it. If your browser shows a warning, it’s expected for self-signed certificates. For production, use a real certificate.
DashScope API Usage
To further explore Qwen3-TTS, we encourage you to try our DashScope API for a faster and more efficient experience. For detailed API information and documentation, please refer to the following:
vLLM Usage
vLLM officially provides day-0 support for Qwen3-TTS! Welcome to use vLLM-Omni for Qwen3-TTS deployment and inference. For installation and more details, please check vLLM-Omni official documentation. Now only offline inference is supported. Online serving will be supported later, and vLLM-Omni will continue to offer support and optimization for Qwen3-TTS in areas such as inference speed and streaming capabilities.
Offline Inference
You can use vLLM-Omni to inference Qwen3-TTS locally, we provide examples in vLLM-Omni repo which can generate audio output:
Evaluation
During evaluation, we ran inference for all models with dtype=torch.bfloat16 and set max_new_tokens=2048. All other sampling parameters used the defaults from the checkpoint’s generate_config.json. For the Seed-Test and InstructTTS-Eval test sets, we set language="auto", while for all other test sets we explicitly passed the corresponding language. The detailed results are shown below.
Speech Generation Benchmarks
Zero-shot speech generation on the Seed-TTS test set. Performance is measured by Word Error Rate (WER, ↓), where lower is better.
Multilingual speech generation on the TTS multilingual test set. Performance is measured by Word Error Rate (WER, ↓) for content consistency and Cosine Similarity (SIM, ↑) for speaker similarity.
Cross-lingual speech generation on the Cross-Lingual benchmark. Performance is measured by Mixed Error Rate (WER for English, CER for others, ↓).
Controllable speech generation on InstructTTSEval. Performance is measured by Attribute Perception and Synthesis accuracy (APS), Description-Speech Consistency (DSD), and Response Precision (RP).
Target-Speaker Multilingual Speech Generation on the TTS multilingual test set. Performance is measured by Word Error Rate (WER, ↓).
Long speech generation results. Performance is measured by Word Error Rate (WER, ↓).
Speech Tokenizer Benchmarks
Comparison between different supervised semantic speech tokenizers on ASR Task.
Comparison between different semantic-related speech tokenizers.
Citation
If you find our paper and code useful in your research, please consider giving a star :star: and citation :pencil: :)