Qwen3-TTS-12Hz-0.6B-Base
Qwen3-TTS Technical Report | GitHub Repository | Hugging Face Demo
Qwen3-TTS is a family of advanced multilingual, controllable, robust, and streaming text-to-speech models. Trained on over 5 million hours of speech data spanning 10 languages, Qwen3-TTS supports state-of-the-art 3-second voice cloning and description-based control.
This specific checkpoint is the 0.6B Base model, which is capable of rapid voice cloning from a user-provided audio input.
Quickstart
Installation
Sample Usage (Voice Clone)
To clone a voice and synthesize new content using the Base model, you can use the following code snippet:
Overview
Introduction
Qwen3-TTS covers 10 major languages (Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, and Italian) as well as multiple dialectal voice profiles to meet global application needs. Key features:
- Powerful Speech Representation: Powered by the self-developed Qwen3-TTS-Tokenizer-12Hz, it achieves efficient acoustic compression and high-dimensional semantic modeling.
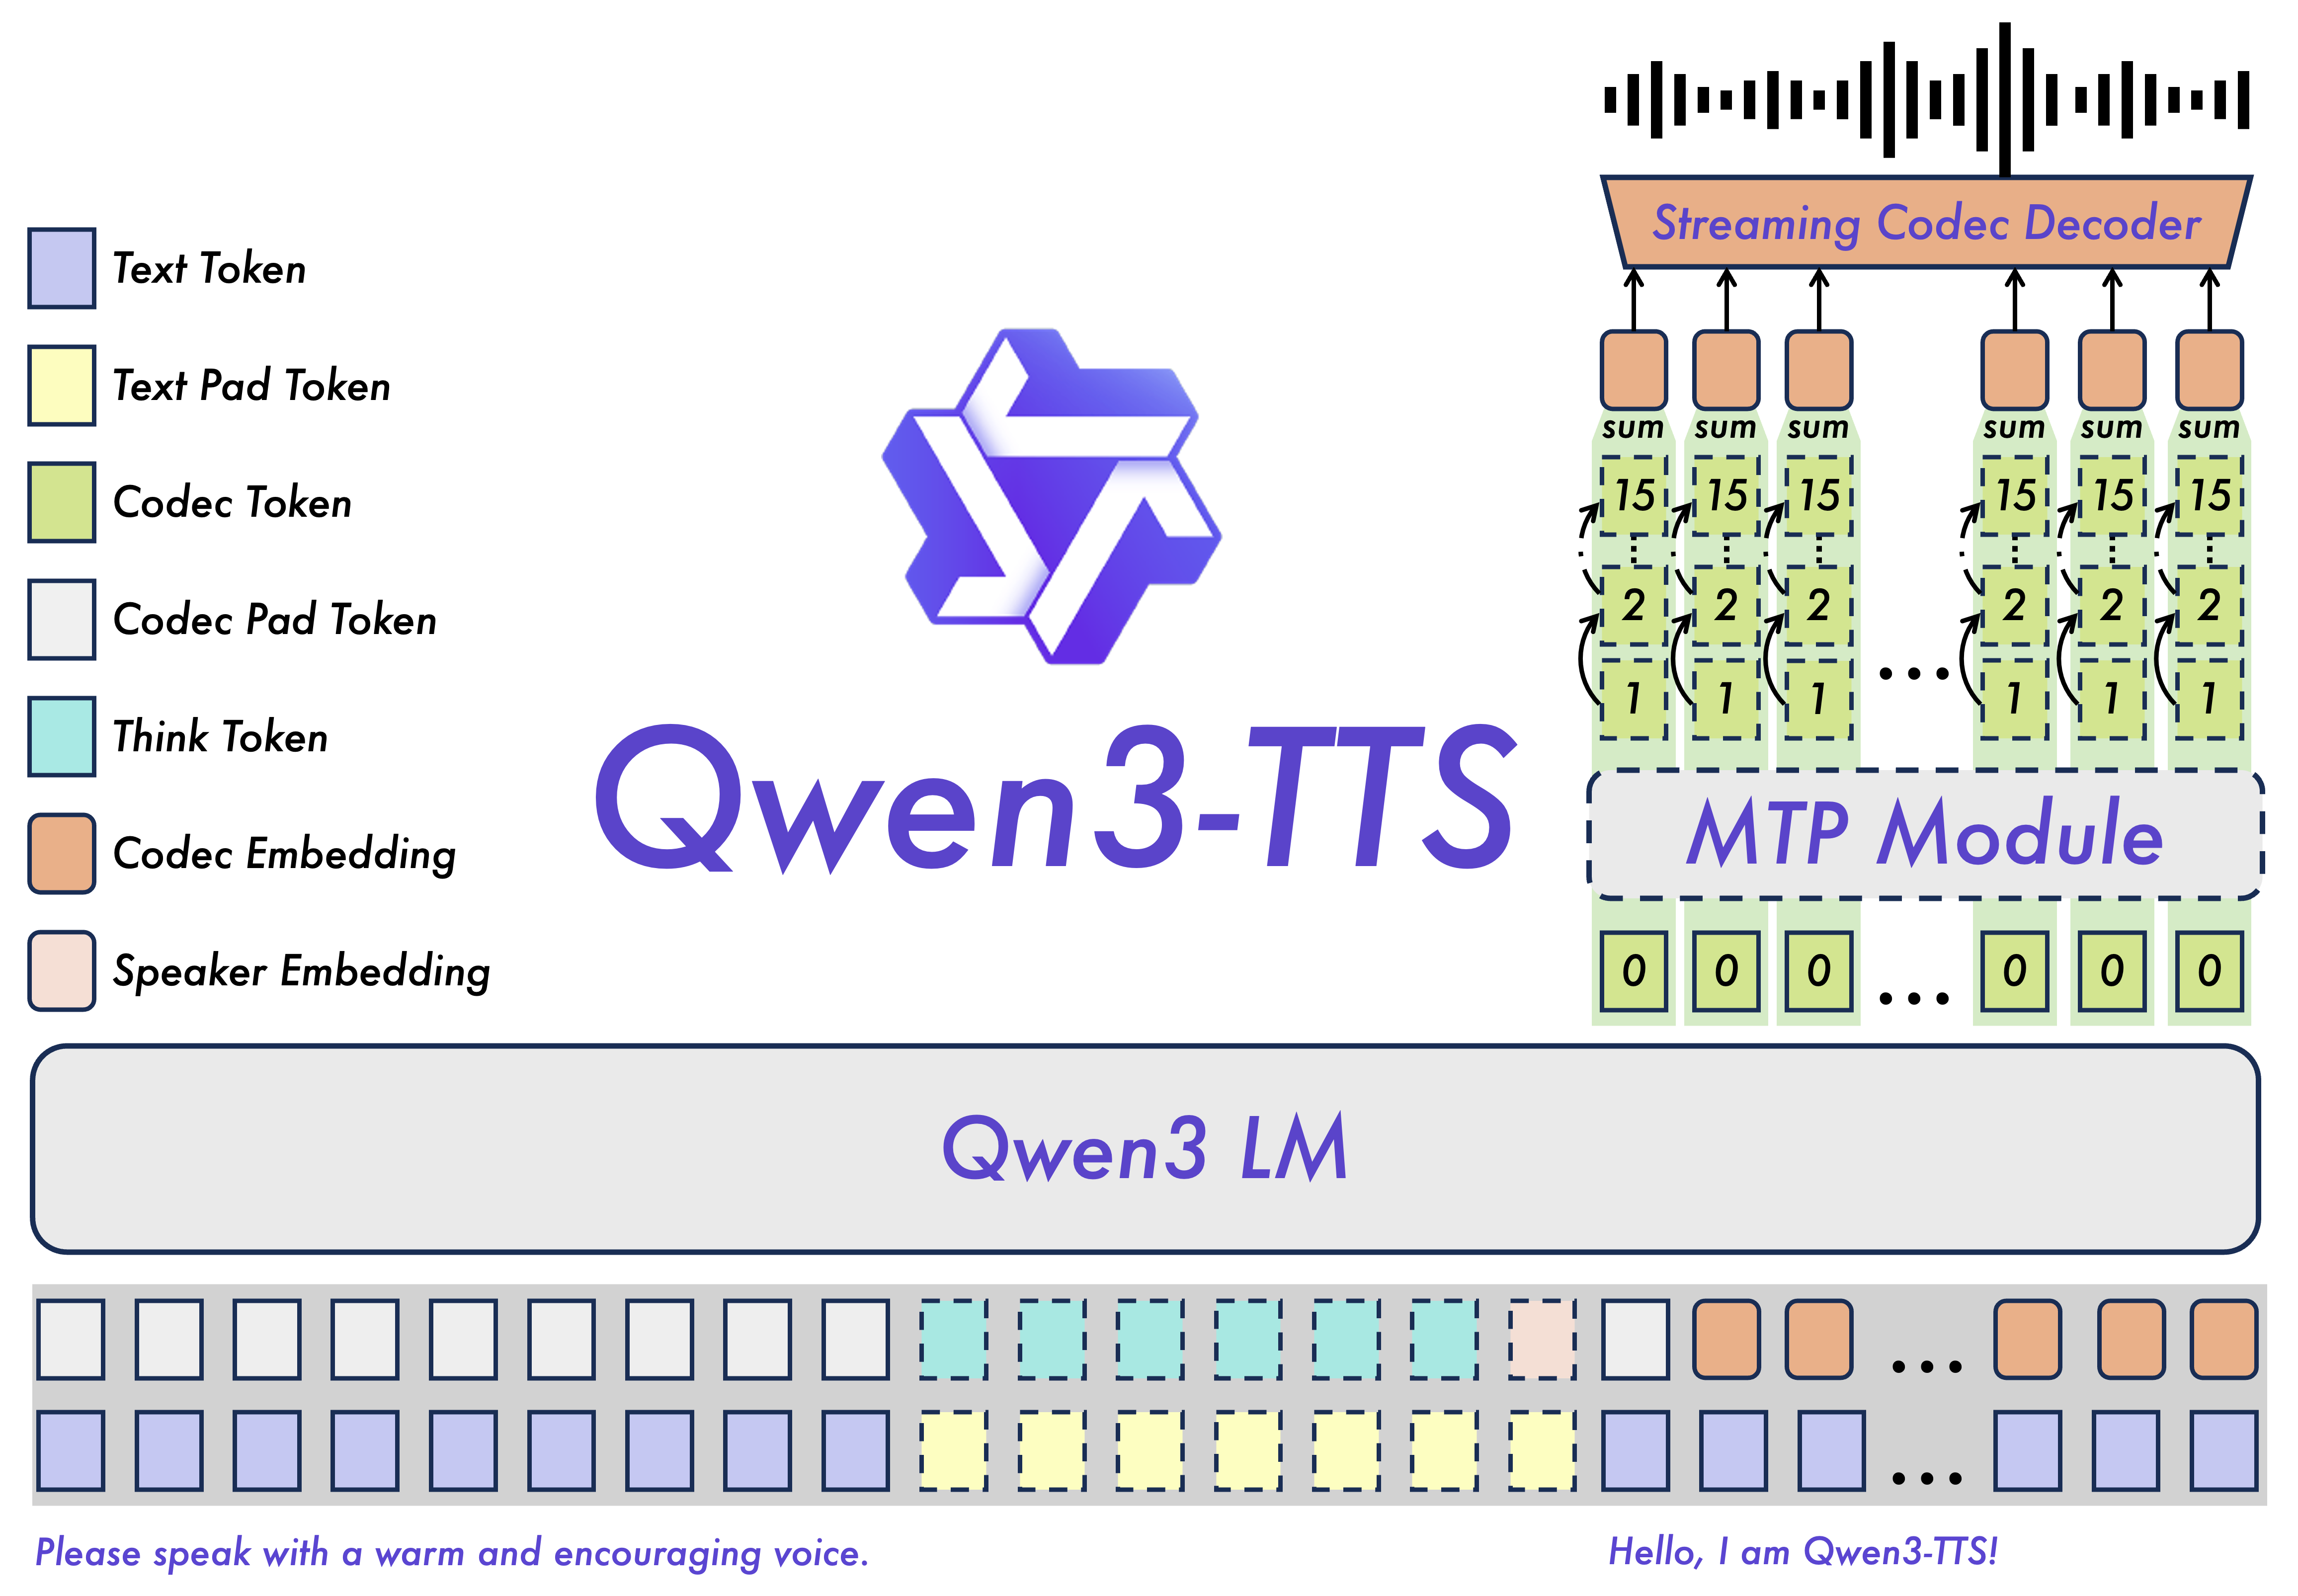
- Universal End-to-End Architecture: Utilizing a discrete multi-codebook LM architecture, it realizes full-information end-to-end speech modeling.
- Extreme Low-Latency Streaming Generation: End-to-end synthesis latency as low as 97ms, meeting the rigorous demands of real-time interactive scenarios.
- Intelligent Text Understanding and Voice Control: Supports speech generation driven by natural language instructions, allowing for flexible control over multi-dimensional acoustic attributes.
Model Architecture
Citation
If you find this work useful, please consider citing the technical report: