Qwen/Qwen3-ASR-1.7B-hf
- License
- apache-2.0
- Size
- not mirrored yet
No official torrent yet β requesting it tells the flock what to host next. You cannot seed a catalog-only page.
Cataloged from Qwen/Qwen3-ASR-1.7B-hf
All models by Qwen βNo official torrent yet β requesting it tells the flock what to host next. You cannot seed a catalog-only page.
Cataloged from Qwen/Qwen3-ASR-1.7B-hf
All models by Qwen β

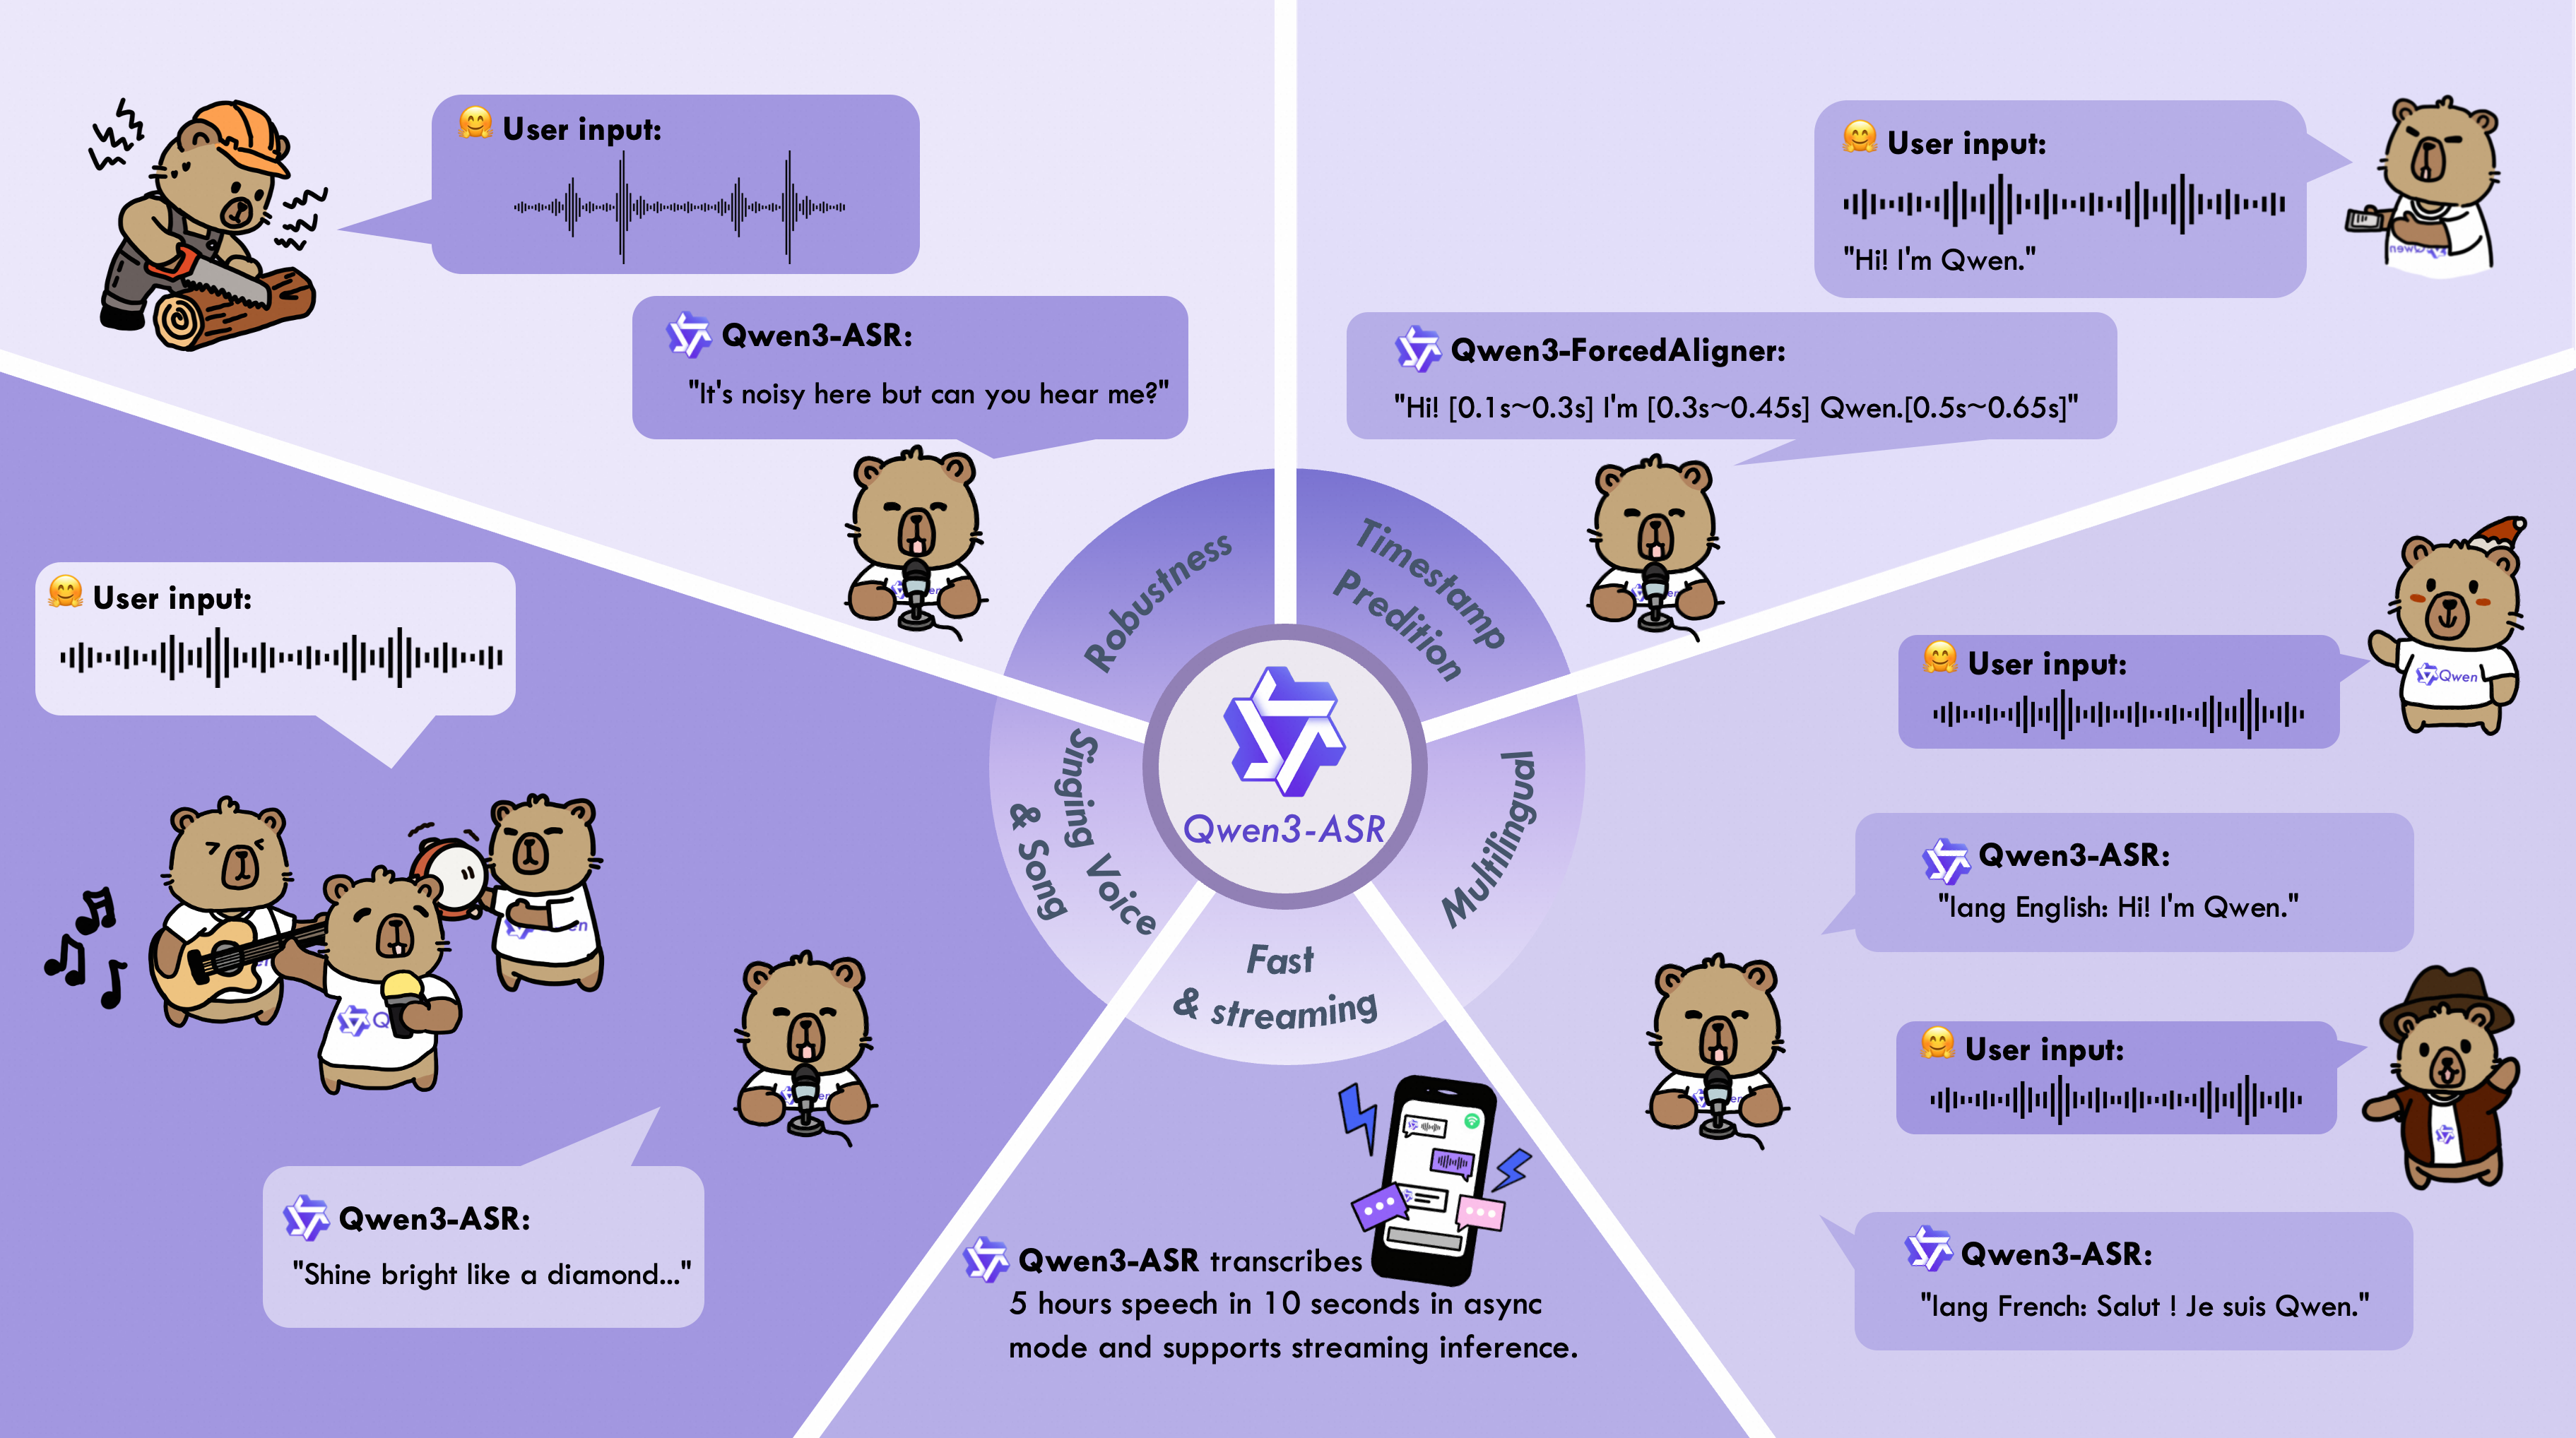
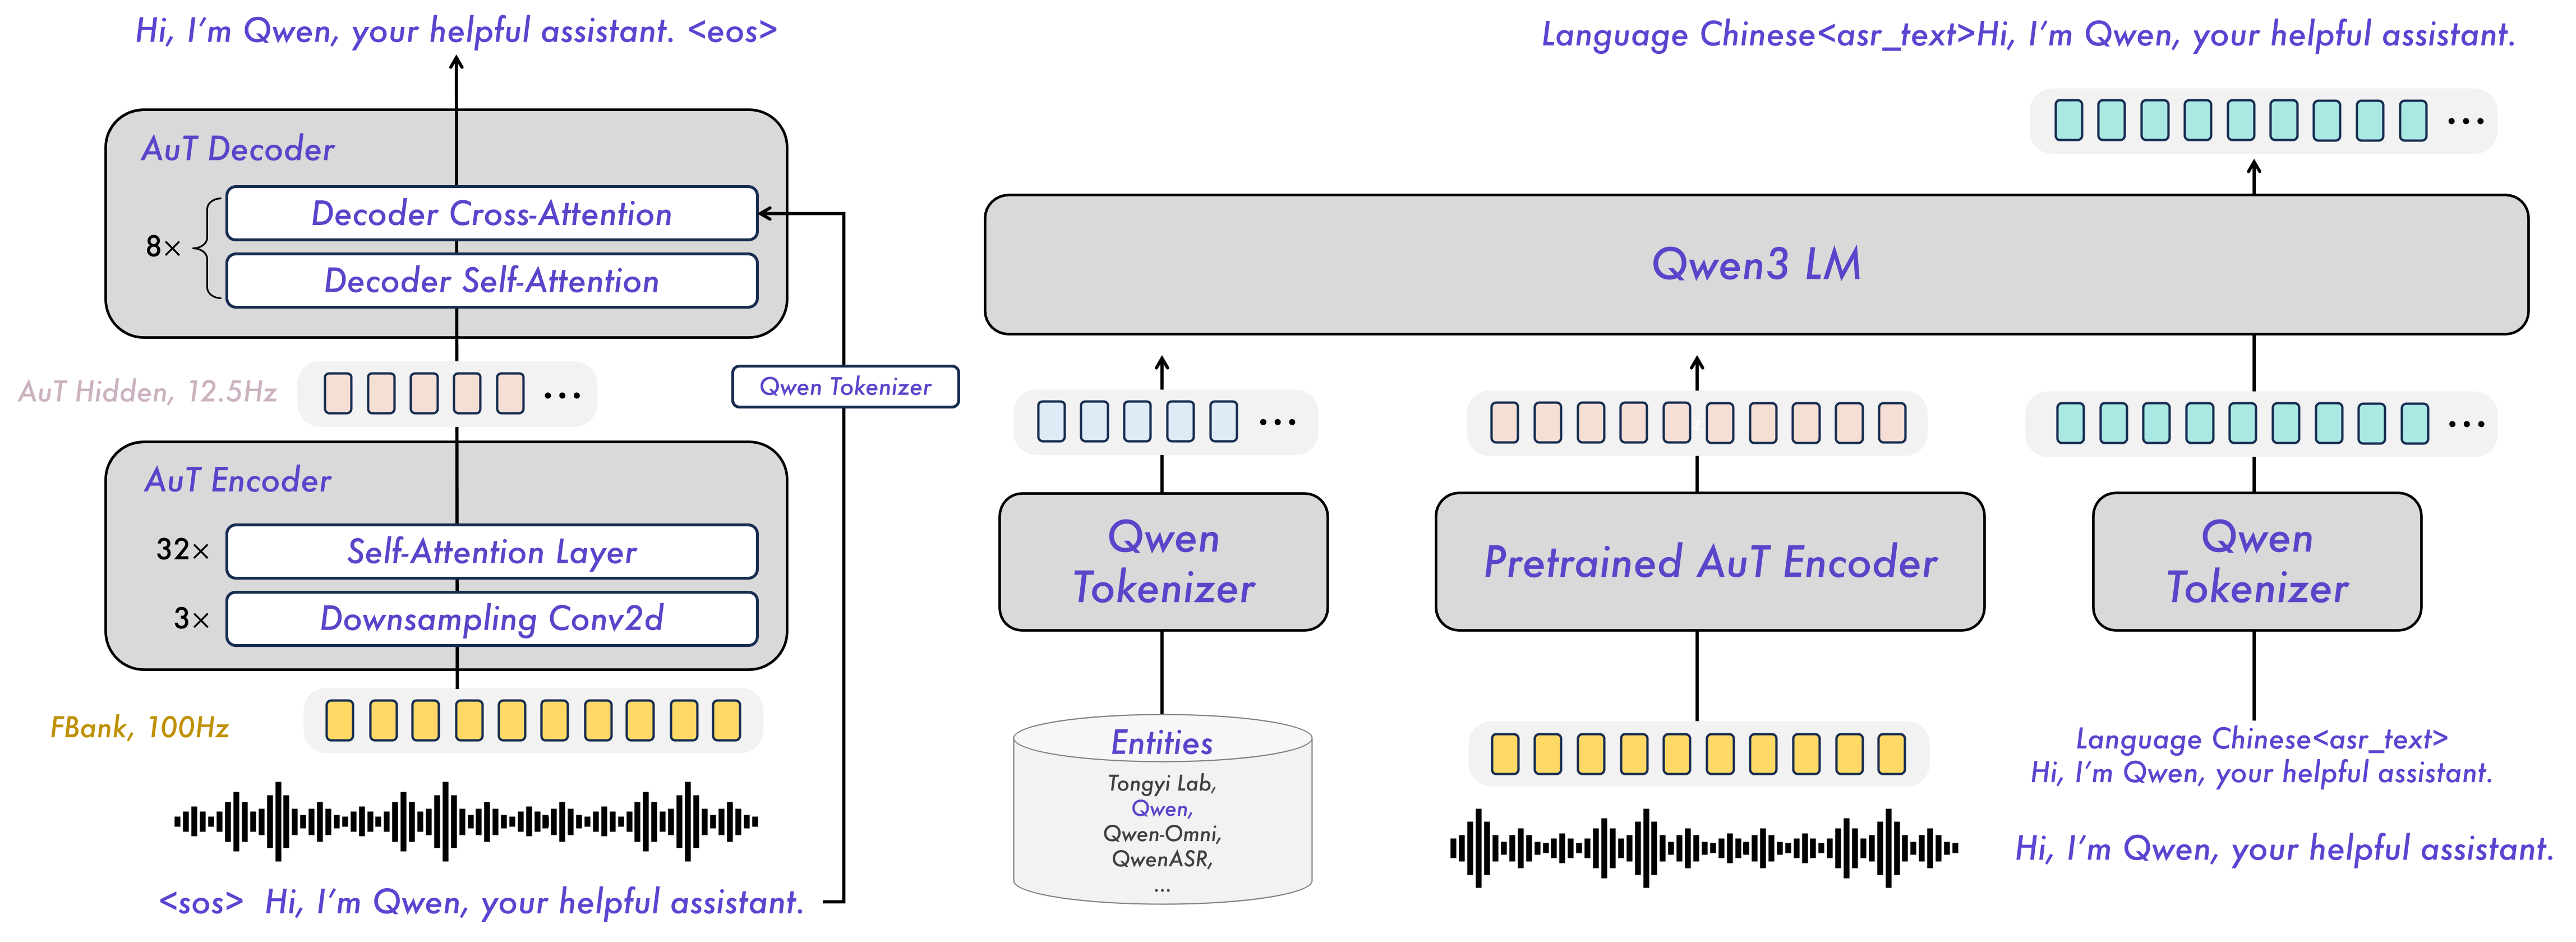
The Qwen3-ASR family includes Qwen3-ASR-1.7B and Qwen3-ASR-0.6B, which support language identification and ASR for 52 languages and dialects. Both leverage large-scale speech training data and the strong audio understanding capability of their foundation model, Qwen3-Omni. The 1.7B version achieves state-of-the-art performance among open-source ASR models and is competitive with the strongest proprietary commercial APIs.
Key features:

Qwen3-ASR is supported natively in π€ Transformers, starting from v5.13.0.
apply_transcription_request handles chat-template formatting for you and is the recommended entry point.
You can force the transcription language as shown below.
You can pass free-form context (e.g. domain-specific vocabulary, names, or background information) via prompt to bias the transcription.
Pass a list of audio paths and optional languages to transcribe multiple files in one call.
Qwen3 ASR also accepts chat template inputs. The apply_transcription_request usage above is a convenience wrapper for apply_chat_template.
The language can be forced through the chat template by prefilling the assistant turn with language <NAME><asr_text> and passing continue_final_message=True, which is what apply_transcription_request does under the hood. Note that if forcing the language, a prefill should be set for all audio in a batch (as shown below).
Qwen3 ASR can be trained with the loss outputted by the model. Put the target transcript in the assistant turn β in the model's output format language <NAME><asr_text>... to preserve the pretrained behavior β and pass output_labels=True. Audio and padding positions are masked automatically.
Use Qwen3ASRForTokenClassification to obtain word-level timestamps from a transcript. Transcribe first with the ASR model, then align with the forced aligner.
Supported languages: Chinese, English, Cantonese, French, German, Italian, Japanese, Korean, Portuguese, Russian, Spanish.
Japanese requires
nagisaand Korean requiressoynlp:pip install nagisa soynlp
Both the ASR and forced aligner models support torch.compile. The forced aligner is a particularly good fit because it runs a single forward pass with no autoregressive decoding, making it ideal for bulk timestamping workflows.
On an A100 we observed ~2.5Γ speed-up for the forced aligner and ~2.4Γ for ASR generate at batch size 4.
WER on the HuggingFace Open ASR Leaderboard (26 June 2026):
pip install "transformers>=5.13.0"from transformers import AutoProcessor, AutoModelForMultimodalLM
model_id = "Qwen/Qwen3-ASR-1.7B-hf"processor = AutoProcessor.from_pretrained(model_id)model = AutoModelForMultimodalLM.from_pretrained(model_id, device_map="auto")print(f"Model loaded on {model.device} with dtype {model.dtype}")
inputs = processor.apply_transcription_request( audio="https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen3-ASR-Repo/asr_en.wav",).to(model.device, model.dtype)
output_ids = model.generate(**inputs, max_new_tokens=256)generated_ids = output_ids[:, inputs["input_ids"].shape[1]:]
# Raw output includes language tag and <asr_text> markerraw = processor.decode(generated_ids)[0]print(f"Raw: {raw}")
# Parsed output: dict with "language" and "transcription"parsed = processor.decode(generated_ids, return_format="parsed")[0]print(f"Parsed: {parsed}")
# Extract only the transcription texttranscription = processor.decode(generated_ids, return_format="transcription_only")[0]print(f"Transcription: {transcription}")
"""Raw: language English<asr_text>Mr. Quilter is the apostle of the middle classes, and we are glad to welcome his gospel.Parsed: {'language': 'English', 'transcription': 'Mr. Quilter is the apostle of the middle classes, and we are glad to welcome his gospel.'}Transcription: Mr. Quilter is the apostle of the middle classes, and we are glad to welcome his gospel."""from transformers import AutoProcessor, AutoModelForMultimodalLM
model_id = "Qwen/Qwen3-ASR-1.7B-hf"processor = AutoProcessor.from_pretrained(model_id)model = AutoModelForMultimodalLM.from_pretrained(model_id, device_map="auto")
# Without language hint (auto-detect)inputs = processor.apply_transcription_request( audio="https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen3-ASR-Repo/asr_zh.wav",).to(model.device, model.dtype)output_ids = model.generate(**inputs, max_new_tokens=256)generated_ids = output_ids[:, inputs["input_ids"].shape[1]:]print(f"Auto-detect: {processor.decode(generated_ids, return_format='transcription_only')[0]}")
# With forced languageinputs = processor.apply_transcription_request( audio="https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen3-ASR-Repo/asr_zh.wav", language="Chinese", # or language code "zh").to(model.device, model.dtype)output_ids = model.generate(**inputs, max_new_tokens=256)generated_ids = output_ids[:, inputs["input_ids"].shape[1]:]print(f"Forced: {processor.decode(generated_ids, return_format='transcription_only')[0]}")from transformers import AutoProcessor, AutoModelForMultimodalLM
model_id = "Qwen/Qwen3-ASR-1.7B-hf"processor = AutoProcessor.from_pretrained(model_id)model = AutoModelForMultimodalLM.from_pretrained(model_id, device_map="auto")
inputs = processor.apply_transcription_request( audio="https://huggingface.co/datasets/bezzam/audio_samples/resolve/main/librispeech_mr_quilter.wav", prompt="Vocabulary: Quilter, apostle, gospel.", language="English",).to(model.device, model.dtype)
output_ids = model.generate(**inputs, max_new_tokens=256)generated_ids = output_ids[:, inputs["input_ids"].shape[1]:]print(processor.decode(generated_ids, return_format="transcription_only")[0])from transformers import AutoProcessor, AutoModelForMultimodalLM
model_id = "Qwen/Qwen3-ASR-1.7B-hf"processor = AutoProcessor.from_pretrained(model_id)model = AutoModelForMultimodalLM.from_pretrained(model_id, device_map="auto")
audio = [ "https://huggingface.co/datasets/bezzam/audio_samples/resolve/main/librispeech_mr_quilter.wav", "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen3-ASR-Repo/asr_zh.wav",]
inputs = processor.apply_transcription_request( audio, language=[None, "zh"],).to(model.device, model.dtype)
output_ids = model.generate(**inputs, max_new_tokens=256)generated_ids = output_ids[:, inputs["input_ids"].shape[1]:]transcriptions = processor.decode(generated_ids, return_format="transcription_only")
for i, text in enumerate(transcriptions): print(f"Audio {i + 1}: {text}")from transformers import AutoProcessor, Qwen3ASRForConditionalGeneration
model_id = "Qwen/Qwen3-ASR-1.7B-hf"processor = AutoProcessor.from_pretrained(model_id)model = Qwen3ASRForConditionalGeneration.from_pretrained(model_id, device_map="auto")
chat_template = [ [ # Context/hotwords as system message {"role": "system", "content": [{"type": "text", "text": "Vocabulary: Quilter, apostle, gospel."}]}, { "role": "user", "content": [ { "type": "audio", "path": "https://huggingface.co/datasets/bezzam/audio_samples/resolve/main/librispeech_mr_quilter.wav", }, ], }, # empty prefill since forcing language in the other sample {"role": "assistant", "content": [{"type": "text", "text": ""}]}, ], [ { "role": "user", "content": [ { "type": "audio", "path": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen3-ASR-Repo/asr_zh.wav", }, ], }, {"role": "assistant", "content": [{"type": "text", "text": "language Chinese<asr_text>"}]}, ],]
inputs = processor.apply_chat_template( chat_template, tokenize=True, return_dict=True, continue_final_message=True,).to(model.device, model.dtype)
output_ids = model.generate(**inputs, max_new_tokens=256)generated_ids = output_ids[:, inputs["input_ids"].shape[1]:]transcriptions = processor.decode(generated_ids, return_format="transcription_only")for text in transcriptions: print(text)from transformers import AutoProcessor, Qwen3ASRForConditionalGeneration
model_id = "Qwen/Qwen3-ASR-1.7B-hf"processor = AutoProcessor.from_pretrained(model_id)model = Qwen3ASRForConditionalGeneration.from_pretrained(model_id, device_map="auto")model.train()
transcript = "Mr. Quilter is the apostle of the middle classes, and we are glad to welcome his gospel."conversation = [ [ { "role": "user", "content": [ { "type": "audio", "path": "https://huggingface.co/datasets/bezzam/audio_samples/resolve/main/librispeech_mr_quilter.wav", }, ], }, {"role": "assistant", "content": [{"type": "text", "text": f"language English<asr_text>{transcript}"}]}, ],]
inputs = processor.apply_chat_template( conversation, tokenize=True, return_dict=True, processor_kwargs={"output_labels": True},).to(model.device, model.dtype)
loss = model(**inputs).lossprint("Loss:", loss.item())loss.backward()import torchfrom transformers import AutoProcessor, AutoModelForMultimodalLM, AutoModelForTokenClassification
asr_model_id = "Qwen/Qwen3-ASR-0.6B-hf"aligner_model_id = "Qwen/Qwen3-ForcedAligner-0.6B-hf"
asr_processor = AutoProcessor.from_pretrained(asr_model_id)asr_model = AutoModelForMultimodalLM.from_pretrained(asr_model_id, device_map="auto")
aligner_processor = AutoProcessor.from_pretrained(aligner_model_id)aligner_model = AutoModelForTokenClassification.from_pretrained( aligner_model_id, dtype=torch.bfloat16, device_map="auto")
audio_url = "https://huggingface.co/datasets/bezzam/audio_samples/resolve/main/librispeech_mr_quilter.wav"
# Step 1: Transcribeinputs = asr_processor.apply_transcription_request(audio=audio_url)inputs = inputs.to(asr_model.device, asr_model.dtype)output_ids = asr_model.generate(**inputs, max_new_tokens=256)generated_ids = output_ids[:, inputs["input_ids"].shape[1]:]parsed = asr_processor.decode(generated_ids, return_format="parsed")[0]transcript = parsed["transcription"]language = parsed["language"] or "English"
# Step 2: Prepare alignment inputsaligner_inputs, word_lists = aligner_processor.prepare_forced_aligner_inputs( audio=audio_url, transcript=transcript, language=language,)aligner_inputs = aligner_inputs.to(aligner_model.device, aligner_model.dtype)
# Step 3: Run forced alignerwith torch.inference_mode(): outputs = aligner_model(**aligner_inputs)
# Step 4: Decode timestampstimestamps = aligner_processor.decode_forced_alignment( logits=outputs.logits, input_ids=aligner_inputs["input_ids"], word_lists=word_lists, timestamp_token_id=aligner_model.config.timestamp_token_id,)[0]
for item in timestamps: print(f"{item['text']:<20} {item['start_time']:>8.3f}s β {item['end_time']:>8.3f}s")
"""Word Start (s) End (s)------------------------------------------Mr 0.560 0.800Quilter 0.800 1.280is 1.280 1.440the 1.440 1.520apostle 1.520 2.080..."""from transformers import pipeline
model_id = "Qwen/Qwen3-ASR-1.7B-hf"pipe = pipeline("any-to-any", model=model_id, device_map="auto")
chat_template = [ { "role": "user", "content": [ { "type": "audio", "path": "https://huggingface.co/datasets/bezzam/audio_samples/resolve/main/librispeech_mr_quilter.wav", }, ], }]outputs = pipe(text=chat_template, return_full_text=False)raw_text = outputs[0]["generated_text"]
# Use processor helper to extract transcriptiontranscription = pipe.processor.extract_transcription(raw_text)print(f"Transcription: {transcription}")import torchfrom transformers import AutoProcessor, AutoModelForMultimodalLM
model_id = "Qwen/Qwen3-ASR-1.7B-hf"processor = AutoProcessor.from_pretrained(model_id)model = AutoModelForMultimodalLM.from_pretrained(model_id, dtype=torch.bfloat16).to("cuda").eval()
audio_url = "https://huggingface.co/datasets/bezzam/audio_samples/resolve/main/librispeech_mr_quilter.wav"inputs = processor.apply_transcription_request( audio=[audio_url] * 4,).to("cuda", torch.bfloat16)
model.forward = torch.compile(model.forward)
# Warmupwith torch.inference_mode(): for _ in range(3): _ = model.generate(**inputs, max_new_tokens=256, do_sample=False)
# Inferencewith torch.inference_mode(): output_ids = model.generate(**inputs, max_new_tokens=256, do_sample=False)
generated_ids = output_ids[:, inputs["input_ids"].shape[1]:]print(processor.decode(generated_ids, return_format="transcription_only")[0])@article{Qwen3-ASR, title={Qwen3-ASR Technical Report}, author={Xian Shi, Xiong Wang, Zhifang Guo, Yongqi Wang, Pei Zhang, Xinyu Zhang, Zishan Guo, Hongkun Hao, Yu Xi, Baosong Yang, Jin Xu, Jingren Zhou, Junyang Lin}, journal={arXiv preprint arXiv:2601.21337}, year={2026}}