"700 Zone": This model's performance has been "beaten" (by a mile) by the new "711" (and includes "MTP" quants too):
https://huggingface.co/DavidAU/Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF
This model's benchmarks are in the OpenAI, Claude and Gemini "zone" - it is that strong.
Ultimate: Exceeds Qwen 3.6 27B performance, uncensored and NEO-Di-Matrix quants to bring all that power in quant form.
Q4/IQ4s clock in at 94% of full precision (BF16), with Q6 at just under 98%. Even IQ2_M : 83% of BF16. 5 Metrics per quant, plus benchmarks.
Qwen3.6-27B-Heretic-Uncensored-FINETUNE-NEO-CODE-Di-IMatrix-MAX-GGUF
[Image blocked: No description]
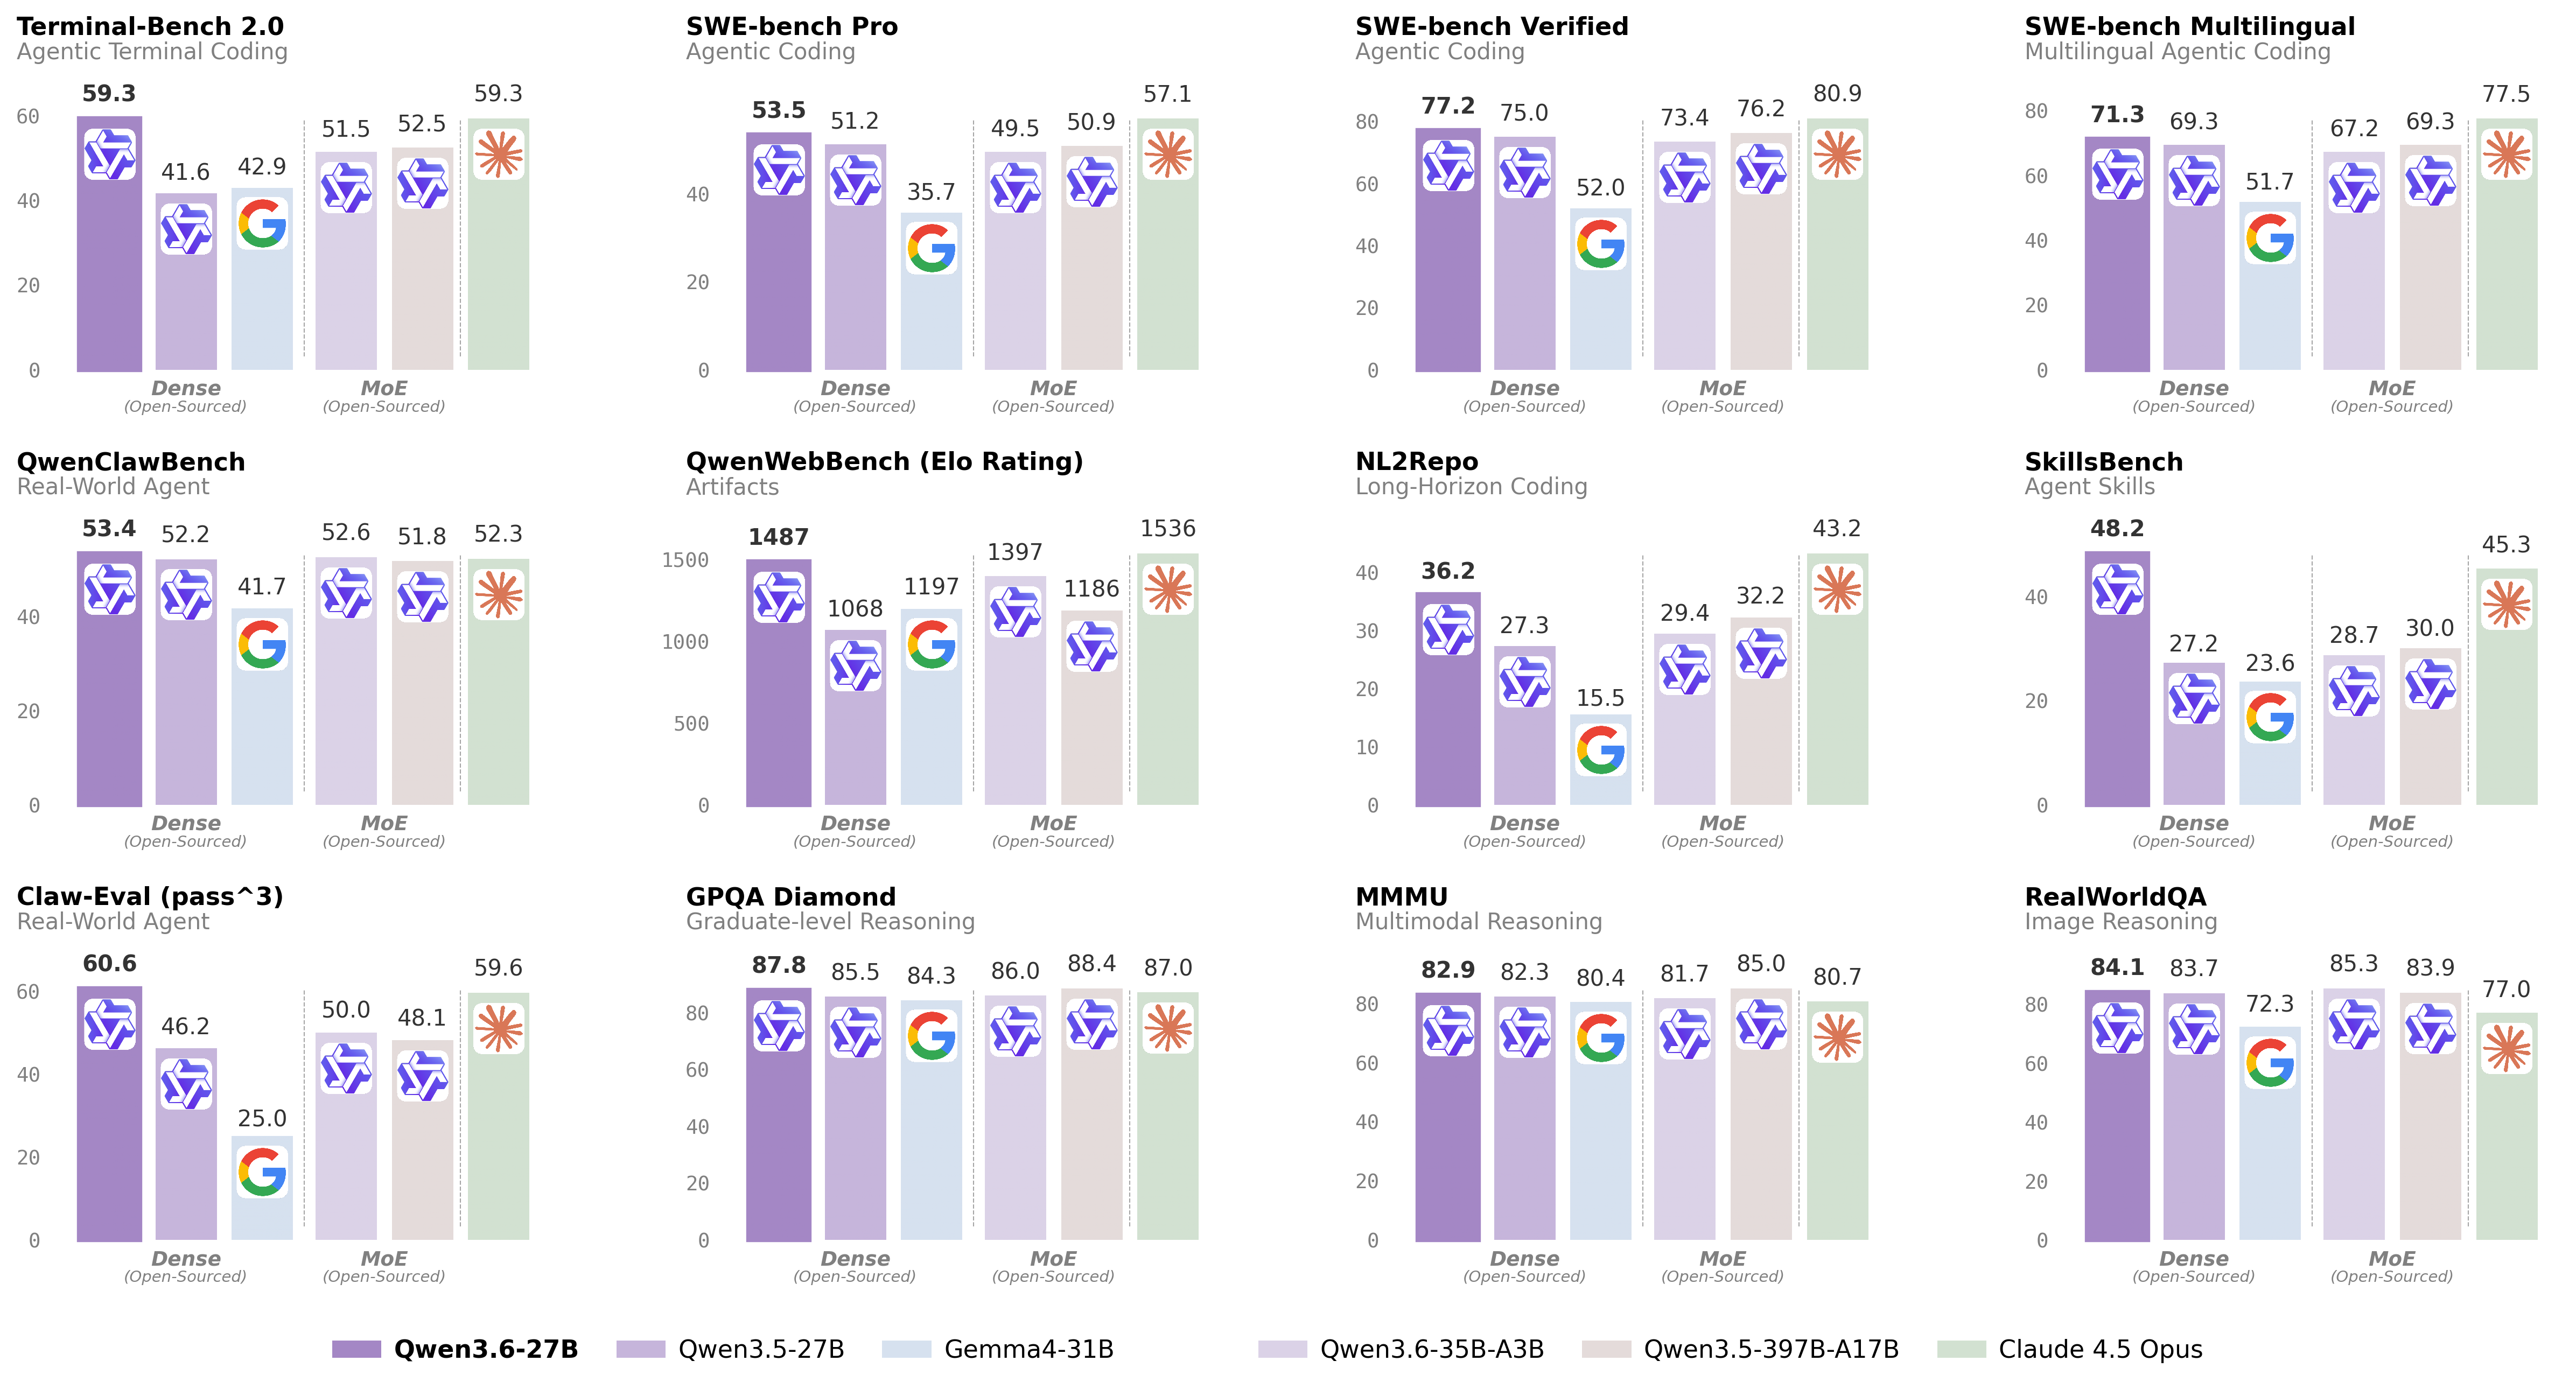
Team Qwen exceeded all expectations with this new Qwen 3.6 27B model [even exceeding their own 398B model] AND GEMMA 4s too, so here are the
balanced and precision quants to match.
And 256k context too. Check out Team Qwen's 3.6 27B detailed stats below.
And now :
Freedom (uncensored), a stronger model (than Qwen 3.6 27B) via tuning by Unsloth on a custom dataset, and ultimate GGUF quant performance as well using NEO/Code Di-Matrix.
DETAILS:
- Heretic'ed and de-censored: The "nanny" was "evicted" from Qwen 3.6 27B.
- Finetune via Unsloth post Heretic'ing, and now this model exceeds root Qwen 3.6 27B (censored) model performance.
- NEO/NEO Code Di-matrix GGUF performance; with Q4ks clocking in at 94% of BF16/Full precision performance.
Pure FREEDOM (Heretic stats):
KLD: Less than .3 is great, lower than this is excellent. This is a measurement of how much the "heretic" version differs from "original model".
STRONGER then Qwen 3.6 27B:
Low level fine tune (post Heretic'ing) to boost the model's core power just a wee bit, don't want to mess with the "Qwen magic":
NOTE: Instruct mode will often test higher than "thinking" mode due to token usage in thinking and context limits.
NEO-CODE-Di-IMatrix-MAX-GGUF Quants:
Quant "engineering" focused on balance and precision, vs raw power (which seemed in some cases to destabilize the model/quant).
In other words benchmarks / stats determined the best quants, not guesswork or one size fits all approach.
This was done to ensure long context, long/multi-convos, coding and math etc etc performed as close as possible to full precision model as well as one-shot, and standard prompting / problem solving.
TWO Imatrix datasets were used to do this by first getting "raw stats" on both, then merging them to get the best of each imatrix in one dataset then this was used to make the "NEO-CODE-Di-IMatrix-MAX" quants.
Additional tensor adjustments were also made, which were also measured (benched) and adjusted too.
IQ2_M: 83% accuracy of BF16/full precision model at only 20% of the org model's size.
Q4K_S: 94% accuracy of BF16/full precision model at only 25% of the org model's size.
[ see full chart, all quants and compared to non-heretic quants too below.]
GGUF POWER UPS:
A radically stronger, more potent GGUF for all use cases.
Meets Unsloth quality, and exceeds it in some metrics (see below).
DETAILS:
- DI-MATRIX (duel imatrix) of NEO and NEO-CODE imatrix datasets (by DavidAU).
- All Unsloth tensor enhancements + additional enhancements CALIBRATED thru metrics testing.
- Every quant benchmarked against BF16/full precision model.
- There is a special Q8_0 quant, with BF16 components. Imatrix has no effect on Q8/BF16 tensors.
VISION:
- Vision (images) tested.
- You need an "mmproj" (just one) of these downloaded too, and placed in the same folder as the GGUF for images.
Qwen Model Settings (suggested):
- Thinking mode for general tasks: temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
- Thinking mode for precise coding tasks (e.g. WebDev): temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
- Instruct (or non-thinking) mode: temperature=0.7, top_p=0.80, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0
- Context window min from 8k to 16k.
FULL STATS, per quant and compared to "non-heretic" too:
This table shows all the quants for Heretic-FineTuned (this repo) and also compares against NEO-CODE-Dimatrix quants for non heretic (numbers are in "[]").
Non-Heretic quants are here:
https://huggingface.co/DavidAU/Qwen3.6-27B-NEO-CODE-Di-IMatrix-MAX-GGUF
NOTES:
- With the exception of "Same Top P (%)" (how close it matchs full precision), lower is better for all other metrics.
- Numbers in [] are for NON-Heretic quants.
- "(!)" for "Mean PPL (Q)" are LOWER than the BF16/full (6.900) precision model; (!) Heretic Version is BF16/full is 6.688.
- Q8_0 contains BF16 components, and not affected by IMATRIX. This is an ULTIMATE PERFORMANCE quant. I have also put the full breakdown of metrics in detail for this quant below.
- Q2s/Q3s are not here because IQ2/3s are faster, and smaller with same or slightly better quality.
- To see how these metrics are generated see "SUPPLEMENT: Q6_K, Q8_0 ULTIMATE PERFORMANCE, detailed metrics" below.
A Beginner's Primer to Quantization Metrics
Quantization compresses Large Language Models to make them run faster and on cheaper hardware. To know if a model is still "smart" after compression, we use these five key metrics:
1. Same Top P (%)
What it is: How often the compressed model picks the exact same word as its first choice compared to the original, uncompressed model.
In plain English: This is "Word-for-Word Accuracy." If this is 94%, it means in 94 out of 100 cases, the model’s top choice remains identical to the original.
The Goal: Higher is better (93% or above is near-perfect).
2. Mean KLD (KL Divergence)
What it is: A measure of how much the "logic" or "thought process" of the model has drifted. It looks at the probabilities of all possible next words, not just the top one.
In plain English: This is the "Reasoning Loss." It measures how much the model's internal "brain" changed during compression.
The Goal: Lower is better (Below 0.03 is excellent).
3. 99.9% KLD (Stability)
What it is: This focuses on the "worst" 0.1% of tokens—the most difficult edge cases the model encountered during testing.
In plain English: This is the "Reliability Score." It tells you if the model is prone to "glitching" or producing gibberish when the conversation gets complicated.
The Goal: Lower is better (Lower numbers mean a more stable model).
4. RMS Δp (%)
What it is: The average change in the model’s confidence levels.
In plain English: This is "Confidence Alignment." Even if the model picks the right word, does it feel as sure as the original? High numbers mean the model feels "jittery" or hesitant.
The Goal: Lower is better (Ideally near 4%).
5. Mean PPL (Perplexity)
What it is: A measure of how "surprised" the model is by the text it is reading.
In plain English: This is "Fluency." If perplexity goes up significantly, the model’s writing will feel less natural, more robotic, or repetitive.
The Goal: Lower is better (Should be as close to the Base model as possible).
Quick Comparison Cheat Sheet
SUPPLEMENT: Q6_K, Q8_0 ULTIMATE PERFORMANCE, detailed metrics
All the quants have this report.
Q6_K and Q8_0 - Ultimate, with BF16 components.
Report generated by:
-
Generate LOGICS.DAT file from the BF16 GGUF: ./perplexity -m w:/main.gguf -f wiki.test.raw --kl-divergence-base logits.dat
-
Generate Quant: ./llama-quantize ...
-
Test the Quant: ./llama-perplexity -m Q6_K.gguf -f wiki.test.raw --kl-divergence-base logits.dat --kl-divergence
"wiki.test.raw" is the standard for ppl testing, and has 580 chunks of testing/580 tests PER QUANT.
Q6_K
Q8_0
Information about this model from Qwen:
Qwen3.6-27B
[!Note]
This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
Qwen3.6 Highlights
This release delivers substantial upgrades, particularly in
- Agentic Coding: the model now handles frontend workflows and repository-level reasoning with greater fluency and precision.
- Thinking Preservation: we've introduced a new option to retain reasoning context from historical messages, streamlining iterative development and reducing overhead.
For more details, please refer to our blog post Qwen3.6-27B.
Model Overview
- Type: Causal Language Model with Vision Encoder
- Training Stage: Pre-training & Post-training
- Language Model
- Number of Parameters: 27B
- Hidden Dimension: 5120
- Token Embedding: 248320 (Padded)
- Number of Layers: 64
- Hidden Layout: 16 × (3 × (Gated DeltaNet → FFN) → 1 × (Gated Attention → FFN))
- Gated DeltaNet:
- Number of Linear Attention Heads: 48 for V and 16 for QK
- Head Dimension: 128
- Gated Attention:
- Number of Attention Heads: 24 for Q and 4 for KV
- Head Dimension: 256
- Rotary Position Embedding Dimension: 64
- Feed Forward Network:
- Intermediate Dimension: 17408
- LM Output: 248320 (Padded)
- MTP: trained with multi-steps
- Context Length: 262,144 natively and extensible up to 1,010,000 tokens.
Benchmark Results
Language
* SWE-Bench Series: Internal agent scaffold (bash + file-edit tools); temp=1.0, top_p=0.95, 200K context window. We correct some problematic tasks in the public set of SWE-bench Pro and evaluate all baselines on the refined benchmark.
* Terminal-Bench 2.0: Harbor/Terminus-2 harness; 3h timeout, 32 CPU/48 GB RAM; temp=1.0, top_p=0.95, top_k=20, max_tokens=80K, 256K ctx; avg of 5 runs.
* SkillsBench: Evaluated via OpenCode on 78 tasks (self-contained subset, excluding API-dependent tasks); avg of 5 runs.
* NL2Repo: Others are evaluated via Claude Code (temp=1.0, top_p=0.95, max_turns=900).
* QwenClawBench: A real-user-distribution Claw agent benchmark; temp=0.6, 256K ctx.
* QwenWebBench: An internal front-end code generation benchmark; bilingual (EN/CN), 7 categories (Web Design, Web Apps, Games, SVG, Data Visualization, Animation, and 3D); auto-render + multimodal judge (code/visual correctness); BT/Elo rating system.
* AIME 26: We use the full AIME 2026 (I & II), where the scores may differ from Qwen 3.5 notes.
Vision Language
* Empty cells (--) indicate scores not yet available or not applicable.
Quickstart
For streamlined integration, we recommend using Qwen3.6 via APIs. Below is a guide to use Qwen3.6 via OpenAI-compatible API.
Serving Qwen3.6
Qwen3.6 can be served via APIs with popular inference frameworks.
In the following, we show example commands to launch OpenAI-Compatible API servers for Qwen3.6 models.
[!Important]
Inference efficiency and throughput vary significantly across frameworks.
We recommend using the latest framework versions to ensure optimal performance and compatibility.
For production workloads or high-throughput scenarios, dedicated serving engines such as SGLang, KTransformers or vLLM are strongly recommended.
[!Important]
The model has a default context length of 262,144 tokens.
If you encounter out-of-memory (OOM) errors, consider reducing the context window.
However, because Qwen3.6 leverages extended context for complex tasks, we advise maintaining a context length of at least 128K tokens to preserve thinking capabilities.
SGLang
SGLang is a fast serving framework for large language models and vision language models.
sglang>=0.5.10 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
-
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
-
Tool Use: To support tool use, you can use the following command.
-
Multi-Token Prediction (MTP): The following command is recommended for MTP:
For detailed deployment guide, see the SGLang Qwen3.5 Cookbook.
vLLM
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs.
vllm>=0.19.0 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
-
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
-
Tool Call: To support tool use, you can use the following command.
-
Multi-Token Prediction (MTP): The following command is recommended for MTP:
-
Text-Only: The following command skips the vision encoder and multimodal profiling to free up memory for additional KV cache:
For detailed deployment guide, see the vLLM Qwen3.5 Recipe.
KTransformers
KTransformers is a flexible framework for experiencing cutting-edge LLM inference optimizations with CPU-GPU heterogeneous computing.
For running Qwen3.6 with KTransformers, see the KTransformers Deployment Guide.
Hugging Face Transformers
Hugging Face Transformers contains a lightweight server which can be used for quick testing and moderate load deployment.
The latest transformers is required for Qwen3.6:
See its documentation for more details. Please also make sure torchvision and pillow are installed.
Then, run transformers serve to launch a server with API endpoints at http://localhost:8000/v1; it will place the model on accelerators if available:
Using Qwen3.6 via the Chat Completions API
The chat completions API is accessible via standard HTTP requests or OpenAI SDKs.
Here, we show examples using the OpenAI Python SDK.
Before starting, make sure it is installed and the API key and the API base URL is configured, e.g.:
[!Tip]
We recommend using the following set of sampling parameters for generation
- Thinking mode for general tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
- Thinking mode for precise coding tasks (e.g. WebDev):
temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
- Instruct (or non-thinking) mode:
temperature=0.7, top_p=0.80, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0
Please note that the support for sampling parameters varies according to inference frameworks.
[!Important]
Qwen3.6 models operate in thinking mode by default, generating thinking content signified by <think>\n...</think>\n\n before producing the final responses.
To disable thinking content and obtain direct response, refer to the examples here.
Text-Only Input
Image Input
Video Input
Instruct (or Non-Thinking) Mode
[!Important]
Qwen3.6 does not officially support the soft switch of Qwen3, i.e., /think and /nothink.
Qwen3.6 will think by default before response.
You can obtain direct response from the model without thinking by configuring the API parameters.
For example,
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changing model, please use "enable_thinking": False instead of "chat_template_kwargs": {"enable_thinking": False}.
Preserve Thinking
By default, only the thinking blocks generated in handling the latest user message is retained, resulting in a pattern commonly as interleaved thinking.
Qwen3.6 has been additionally trained to preserve and leverage thinking traces from historical messages.
You can enable this behavior by setting the preserve_thinking option:
[!Note]
If you are using APIs from Alibaba Cloud Model Studio, in addition to changing model, please use "preserve_thinking": True instead of "chat_template_kwargs": {"preserve_thinking": False}.
This capability is particularly beneficial for agent scenarios, where maintaining full reasoning context can enhance decision consistency and, in many cases, reduce overall token consumption by minimizing redundant reasoning. Additionally, it can improve KV cache utilization, optimizing inference efficiency in both thinking and non-thinking modes.
Agentic Usage
Qwen3.6 excels in tool calling capabilities.
Qwen-Agent
We recommend using Qwen-Agent to quickly build Agent applications with Qwen3.6.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
Qwen Code
Qwen Code is an open-source AI agent for the terminal, optimized for Qwen models. It helps you understand large codebases, automate tedious work, and ship faster.
For more information, please refer to Qwen Code.
Processing Ultra-Long Texts
Qwen3.6 natively supports context lengths of up to 262,144 tokens.
For long-horizon tasks where the total length (including both input and output) exceeds this limit, we recommend using RoPE scaling techniques to handle long texts effectively., e.g., YaRN.
YaRN is currently supported by several inference frameworks, e.g., transformers, vllm, ktransformers and sglang.
In general, there are two approaches to enabling YaRN for supported frameworks:
-
Modifying the model configuration file:
In the config.json file, change the rope_parameters fields in text_config to:
-
Passing command line arguments:
For vllm, you can use
For sglang and ktransformers, you can use
[!NOTE]
All the notable open-source frameworks implement static YaRN, which means the scaling factor remains constant regardless of input length, potentially impacting performance on shorter texts.
We advise modifying the rope_parameters configuration only when processing long contexts is required.
It is also recommended to modify the factor as needed. For example, if the typical context length for your application is 524,288 tokens, it would be better to set factor as 2.0.
Best Practices
To achieve optimal performance, we recommend the following settings:
-
Sampling Parameters:
- We suggest using the following sets of sampling parameters depending on the mode and task type:
- Thinking mode for general tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
- Thinking mode for precise coding tasks (e.g., WebDev):
temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0
- Instruct (or non-thinking) mode:
temperature=0.7, top_p=0.80, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0
- For supported frameworks, you can adjust the
presence_penalty parameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.
-
Adequate Output Length: We recommend using an output length of 32,768 tokens for most queries. For benchmarking on highly complex problems, such as those found in math and programming competitions, we suggest setting the max output length to 81,920 tokens. This provides the model with sufficient space to generate detailed and comprehensive responses, thereby enhancing its overall performance.
-
Standardize Output Format: We recommend using prompts to standardize model outputs when benchmarking.
- Math Problems: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
- Multiple-Choice Questions: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the
answer field with only the choice letter, e.g., "answer": "C"."
-
Long Video Understanding: To optimize inference efficiency for plain text and images, the size parameter in the released video_preprocessor_config.json is conservatively configured. It is recommended to set the longest_edge parameter in the video_preprocessor_config file to 469,762,048 (corresponding to 224k video tokens) to enable higher frame-rate sampling for hour-scale videos and thereby achieve superior performance. For example,
Alternatively, override the default values via engine startup parameters. For implementation details, refer to: vLLM / SGLang.
Citation
If you find our work helpful, feel free to give us a cite.